huggingface / huggingface/diffusers
Where should a training-free high-resolution hook for Flux (DyPE / spectral attention) live?
- Ngôn ngữ chính
- Python
- Star
- 34.5k
- Fork
- 7.3k
- Merge trung bình
- 3 ngày 3 giờ
- Pull request đã merge (30 ngày)
- 91
Mô tả
### Summary
I have a working, tested implementation of training-free ultra-high-resolution generation for RoPE DiTs (Flux) — [DyPE](https://huggingface.co/papers/2510.20766) plus an optional spectral-attention mode ([SEGA](https://huggingface.co/papers/2605.22668)) — and I'd like to contribute it. Before opening the PR I want to align on **where it should live**, because precedent points two ways.
### The placement question (the main thing I'd like a call on)
- **Core `src/diffusers/hooks/`** — the method modifies the transformer's positional embedding at inference, exactly like `apply_pyramid_attention_broadcast` / `apply_faster_cache` modify attention. That argues for a core hook (`apply_dype`).
- **`examples/community/`** — but training-free *high-resolution generation* methods have historically landed as community pipelines (e.g. DemoFusion, #6022), which argues for a community pipeline instead.
DyPE straddles the two. I've built it as a core hook (details below), but I'm happy to reshape it as a community pipeline if that's the preferred home. **Which do you want?**
### What it does
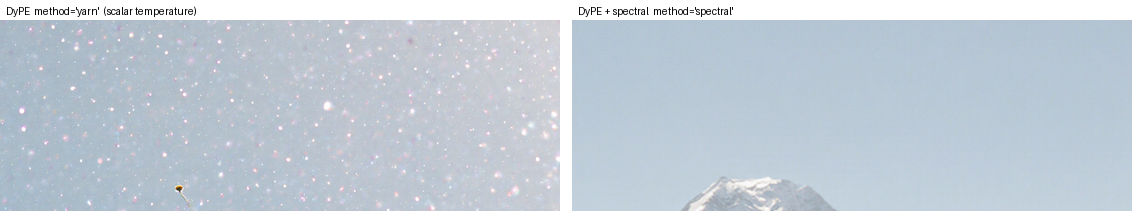
`apply_dype(pipe.transformer, method="yarn")` swaps the transformer's RoPE embedding for a timestep-aware YaRN/NTK-by-parts schedule that engages only above the trained resolution (a no-op at/below 1024² for Flux). `method="spectral"` adds a per-frequency, content-aware attention temperature derived from the latent's spectral energy, which removes the residual high-frequency speckle a scalar temperature leaves in flat regions at 4K. State is fed via a native `register_forward_pre_hook`, so it survives `enable_model_cpu_offload`.
> Naming note: the spectral mode implements SEGA (arXiv:2605.22668), but I've named the API value `method="spectral"` rather than `"sega"` to avoid confusion with the existing **Semantic Guidance ("SEGA")** in diffusers (`SemanticStableDiffusionPipeline`, `examples/community/pipeline_flux_semantic_guidance.py`). Open to a different name.
### Validation (FLUX.1-Krea-dev, 4096²)
- `method="yarn"` reproduces the reference ([guyyariv/DyPE](https://github.com/guyyariv/DyPE), MIT) bit-for-bit (Δ=0 on the positional-embedding output).
- `method="spectral"` drops flat-sky high-frequency energy ~6× (76.5 → 12.7) with detail retained:
### Other design questions
1. **One PR or split?** DyPE and the spectral mode are independent (spectral layers on top). Land DyPE first + spectral as a follow-up, or both together?
2. **High-resolution flow-match shift.** Above ~2K, `calculate_shift`'s `mu` grows with sequence length and collapses the sigma schedule; today the fix is a documented `pipe.scheduler.register_to_config(base_shift=1.15, max_shift=1.15)`. A pos-embed hook can't reach the pipeline schedule — keep it as documented usage, add a helper, or handle it pipeline-side?
3. **`.item()` in the embedding forward.** Extrapolation engages only above the trained resolution, which needs a data-dependent read of the max position (a device sync / `torch.compile` graph break the stock embedding doesn't have). Acceptable, or a preferred pattern?
### Status
Implementation + docs + tests are ready and rebased on current `main` (24 hook tests pass, `make fix-copies` clean, `apply_dype` a no-op at/below the trained resolution). I can open the PR as soon as we settle placement (1) — reference branch/diff available on request.
Hướng dẫn đóng góp
Hướng nghiên cứu
Bắt đầu bằng việc xem xét các triển khai hiện có trong src/diffusers/hooks/ và các pipeline cộng đồng độ phân giải cao liên quan dưới examples/community/. Kiểm tra 24 bài kiểm thử hook đã được báo cáo và khả năng tương thích với current-main, sau đó giải quyết các câu hỏi thiết kế về vị trí, phân tách, dịch chuyển scheduler và .item(). Công việc được xem là hoàn tất khi các maintainer thống nhất về vị trí và phạm vi của đóng góp trước khi mở một PR.
Do mô hình lập chỉ mục viết ra từ nội dung của issue.
Đánh giá
- Công nghệ
- python, pytorch
- Lĩnh vực
- machine-learning, performance
- Loại issue
- Tính năng
- Độ khó
- 5/5
- Thời gian dự kiến
- Hơn một tuần
- Mức độ hoạt động
- Sôi nổi
- Độ rõ ràng
- Cần làm rõ
- Mức phù hợp với người mới
- 30/100