huggingface / huggingface/diffusers
Where should a training-free high-resolution hook for Flux (DyPE / spectral attention) live?
- Vorherrschende Sprache
- Python
- Sterne
- 34.5k
- Forks
- 7.3k
- Ø Merge
- 3 T. 3 Std.
- Gemergte PRs (30 T.)
- 91
Beschreibung
### Summary
I have a working, tested implementation of training-free ultra-high-resolution generation for RoPE DiTs (Flux) — [DyPE](https://huggingface.co/papers/2510.20766) plus an optional spectral-attention mode ([SEGA](https://huggingface.co/papers/2605.22668)) — and I'd like to contribute it. Before opening the PR I want to align on **where it should live**, because precedent points two ways.
### The placement question (the main thing I'd like a call on)
- **Core `src/diffusers/hooks/`** — the method modifies the transformer's positional embedding at inference, exactly like `apply_pyramid_attention_broadcast` / `apply_faster_cache` modify attention. That argues for a core hook (`apply_dype`).
- **`examples/community/`** — but training-free *high-resolution generation* methods have historically landed as community pipelines (e.g. DemoFusion, #6022), which argues for a community pipeline instead.
DyPE straddles the two. I've built it as a core hook (details below), but I'm happy to reshape it as a community pipeline if that's the preferred home. **Which do you want?**
### What it does
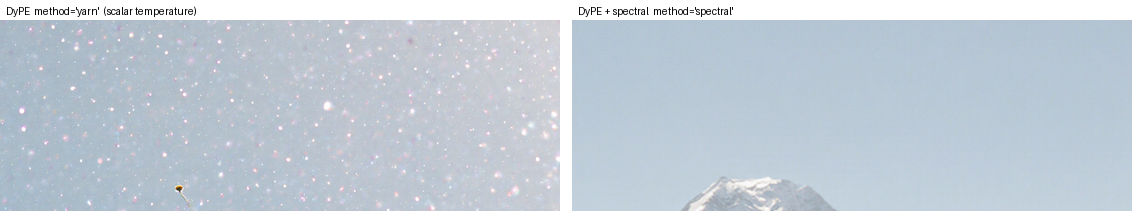
`apply_dype(pipe.transformer, method="yarn")` swaps the transformer's RoPE embedding for a timestep-aware YaRN/NTK-by-parts schedule that engages only above the trained resolution (a no-op at/below 1024² for Flux). `method="spectral"` adds a per-frequency, content-aware attention temperature derived from the latent's spectral energy, which removes the residual high-frequency speckle a scalar temperature leaves in flat regions at 4K. State is fed via a native `register_forward_pre_hook`, so it survives `enable_model_cpu_offload`.
> Naming note: the spectral mode implements SEGA (arXiv:2605.22668), but I've named the API value `method="spectral"` rather than `"sega"` to avoid confusion with the existing **Semantic Guidance ("SEGA")** in diffusers (`SemanticStableDiffusionPipeline`, `examples/community/pipeline_flux_semantic_guidance.py`). Open to a different name.
### Validation (FLUX.1-Krea-dev, 4096²)
- `method="yarn"` reproduces the reference ([guyyariv/DyPE](https://github.com/guyyariv/DyPE), MIT) bit-for-bit (Δ=0 on the positional-embedding output).
- `method="spectral"` drops flat-sky high-frequency energy ~6× (76.5 → 12.7) with detail retained:
### Other design questions
1. **One PR or split?** DyPE and the spectral mode are independent (spectral layers on top). Land DyPE first + spectral as a follow-up, or both together?
2. **High-resolution flow-match shift.** Above ~2K, `calculate_shift`'s `mu` grows with sequence length and collapses the sigma schedule; today the fix is a documented `pipe.scheduler.register_to_config(base_shift=1.15, max_shift=1.15)`. A pos-embed hook can't reach the pipeline schedule — keep it as documented usage, add a helper, or handle it pipeline-side?
3. **`.item()` in the embedding forward.** Extrapolation engages only above the trained resolution, which needs a data-dependent read of the max position (a device sync / `torch.compile` graph break the stock embedding doesn't have). Acceptable, or a preferred pattern?
### Status
Implementation + docs + tests are ready and rebased on current `main` (24 hook tests pass, `make fix-copies` clean, `apply_dype` a no-op at/below the trained resolution). I can open the PR as soon as we settle placement (1) — reference branch/diff available on request.
Beitragsleitfaden
Rechercherichtung
Start by reviewing existing implementations in src/diffusers/hooks/ and related high-resolution community pipelines under examples/community/. Examine the reported 24 hook tests and current-main compatibility, then resolve the placement, split, scheduler-shift, and .item() design questions. Done means maintainers agree on the contribution's location and scope before a PR is opened.
Vom Indexierungsmodell aus dem Issue-Text verfasst.
Bewertung
- Tech-Stack
- python, pytorch
- Bereich
- machine-learning, performance
- Issue-Typ
- Feature
- Schwierigkeit
- 5/5
- Geschätzter Aufwand
- Über eine Woche
- Aktivitätsstatus
- Aktiv
- Klarheit
- Muss geklärt werden
- Anfängerfreundlichkeit
- 30/100