zlib: reset() after flush() silently produces an undecodable zstd stream
还没有人认领这个 Issue。
- 主要语言
- JavaScript
- 星标
- 122k
- 派生
- 37.3k
- 平均合并
- 4 天 2 小时
- 30 天内合并 PR
- 283
描述
Version
v27.0.0-pre (built from main at 99f0ddef)
Platform
Linux x86_64 (Ubuntu 22.04, built with clang 20)
Reproduced identically on macOS arm64 with v26.8.1
Subsystem
zlib
What steps will reproduce the bug?
Call .flush() on a zstd compressor and then .reset() it. The stream keeps
producing output, but that output can no longer be decompressed, and nothing
throws.
import * as zlib from 'node:zlib';

const stream = zlib.createZstdCompress();
const chunks = [];
stream.on('data', (chunk) => chunks.push(chunk));
stream.on('error', (err) => console.log('compress error:', err.code)); // never fires

stream.write(Buffer.from('hello'));
await new Promise((resolve) => stream.flush(resolve));  // <-- produces 14 bytes
stream.reset();                                          // <-- drops the frame state
stream.end(Buffer.from('world'));
await new Promise((resolve) => stream.on('end', resolve));

const output = Buffer.concat(chunks);
console.log('compressed bytes:', output.length);          // 28
console.log(zlib.zstdDecompressSync(output).toString());  // throws
Result:
compressed bytes: 28
Error: Data corruption detected (code: ZSTD_error_corruption_detected)
How often does it reproduce? Is there a required condition?
Always, as long as reset() is called after some bytes have already been
written out but before the frame is finished. A plain flush() (without
reset()) is fine, and so is reset() before any write — you need both calls
in that order.
What is the expected behavior? Why is that the expected behavior?
The compressor should either produce a stream that decompresses correctly, or
report an error. It currently does neither — it silently emits a stream that no
zstd decoder can read.
reset() is documented as "cancel the current frame and start a new session".
Cancelling a frame would be fine on its own, but the bytes that flush()
already handed to the output stream cannot be taken back, so the next frame gets
appended to a fragment of the cancelled one.
zstd itself is explicit that this is not allowed. From deps/zstd/lib/zstd.h
(ZSTD_compressStream2):
Before starting a new compression job, or changing compression parameters, it
is required to fully flush internal buffers.
flush() leaves the frame unfinished: ZSTD_compressStream2 returns non-zero
in that case, which is how a caller is supposed to know there is still work
pending.
What do you see instead?
flush() emits a fragment of the frame (14 bytes in the example above).
reset() throws that frame away, but the 14 bytes stay in the output. end()
then starts a brand-new frame on the reset session and emits 14 more bytes. The
result is a 28-byte stream made of fragment + complete frame, which decodes as
corruption.
The same amount of data without the reset() produces 22 bytes and decodes to
helloworld — because end() continues the existing frame (8 bytes) instead of
starting a new one (14 bytes).
Additional information
This is a source code level debugging observation
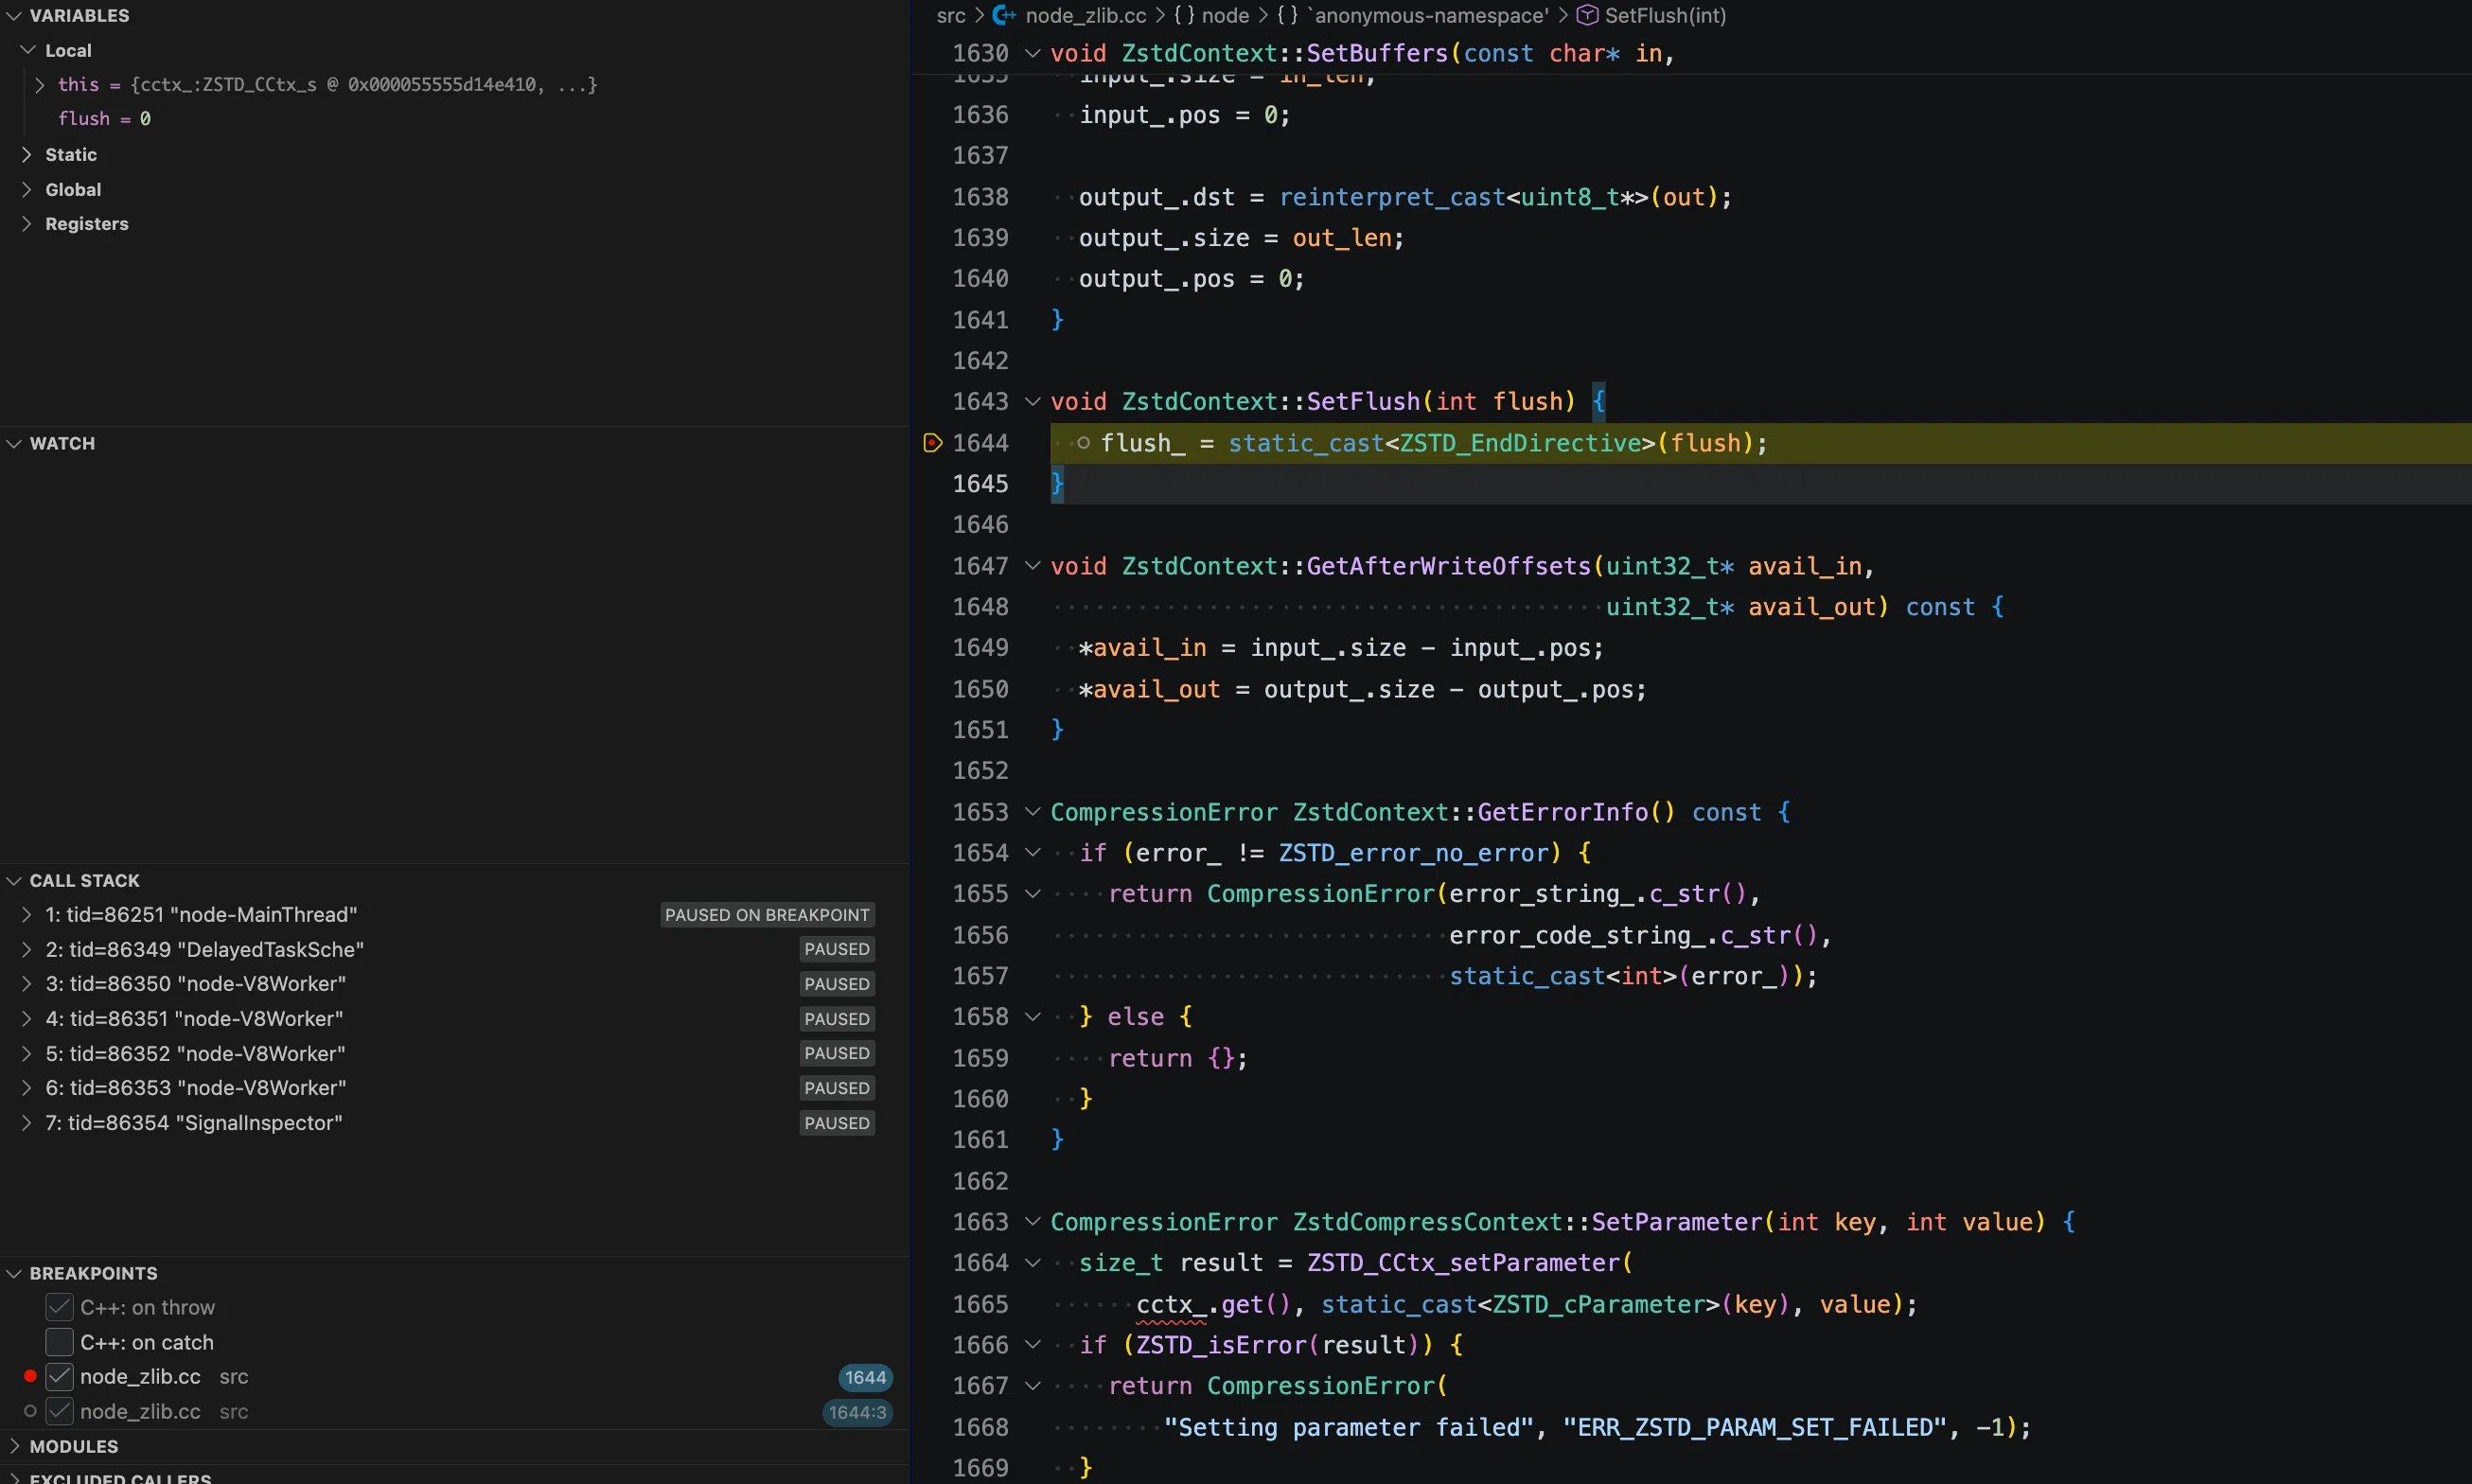
1. write("hello") → SetFlush, flush = 0 (ZSTD_e_continue)
The data goes into the compressor but nothing comes out yet.
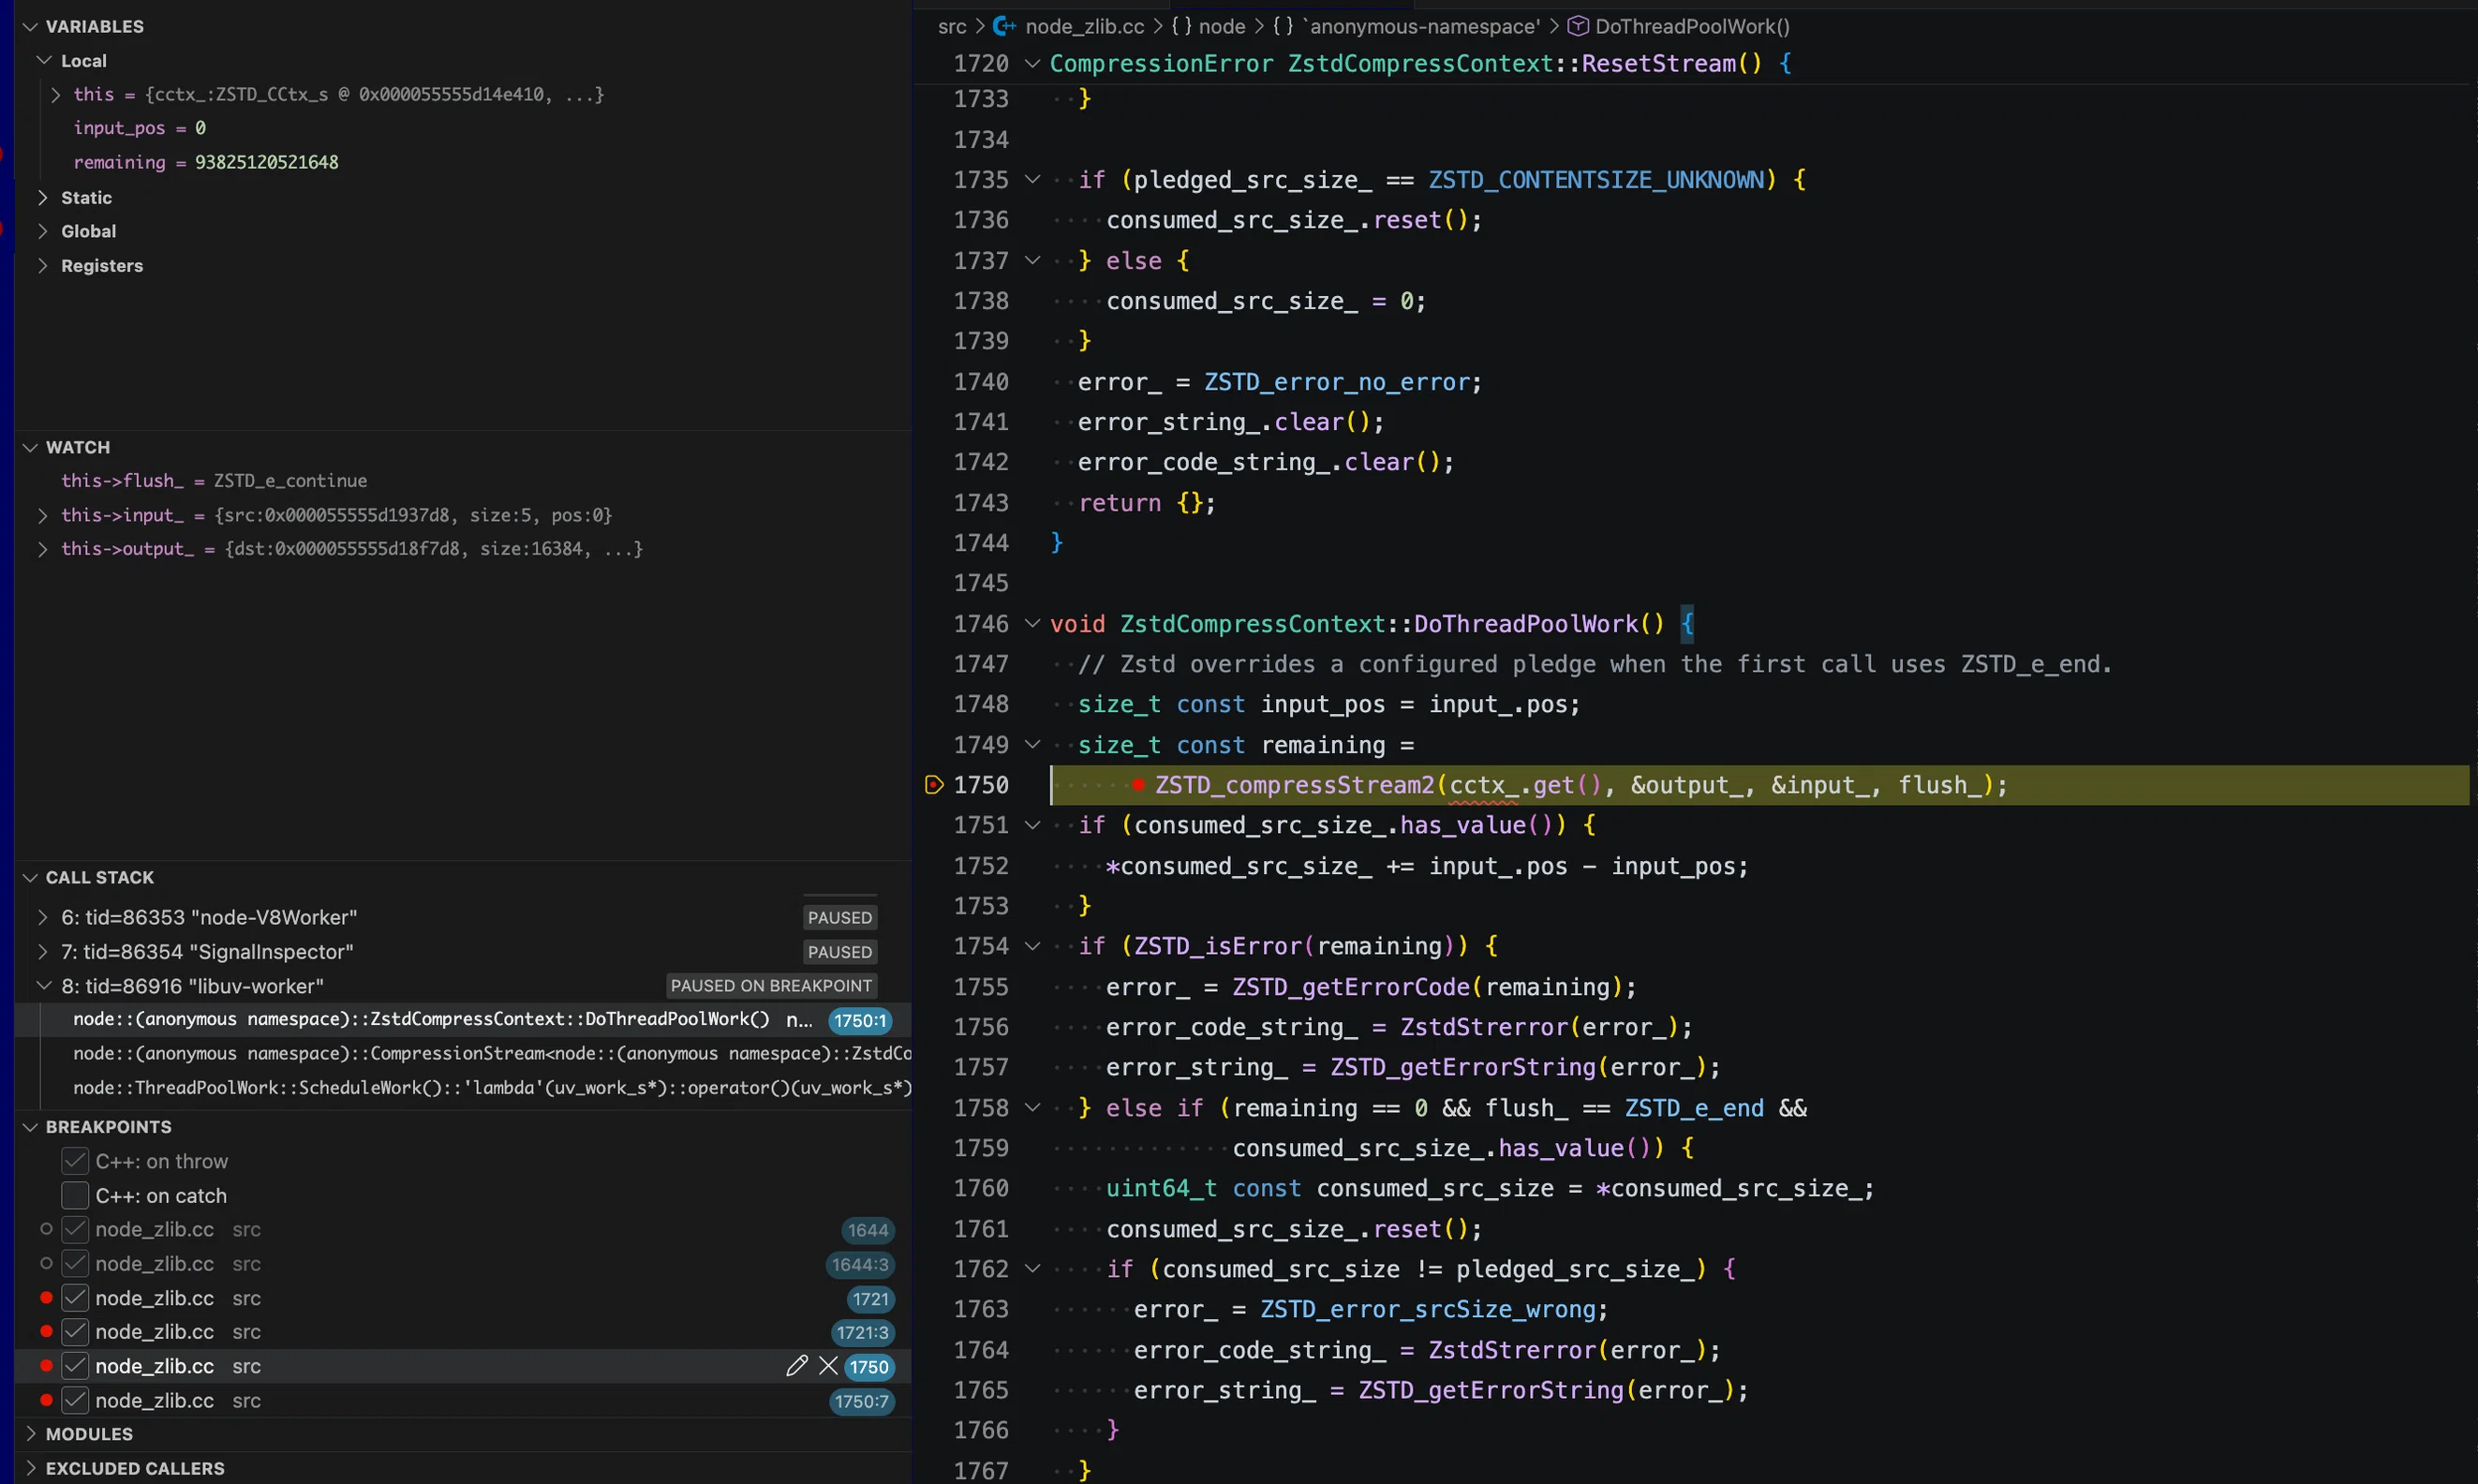
2. DoThreadPoolWork with flush_ = ZSTD_e_continue
input_ holds the 5 bytes, output_.pos is still 0.
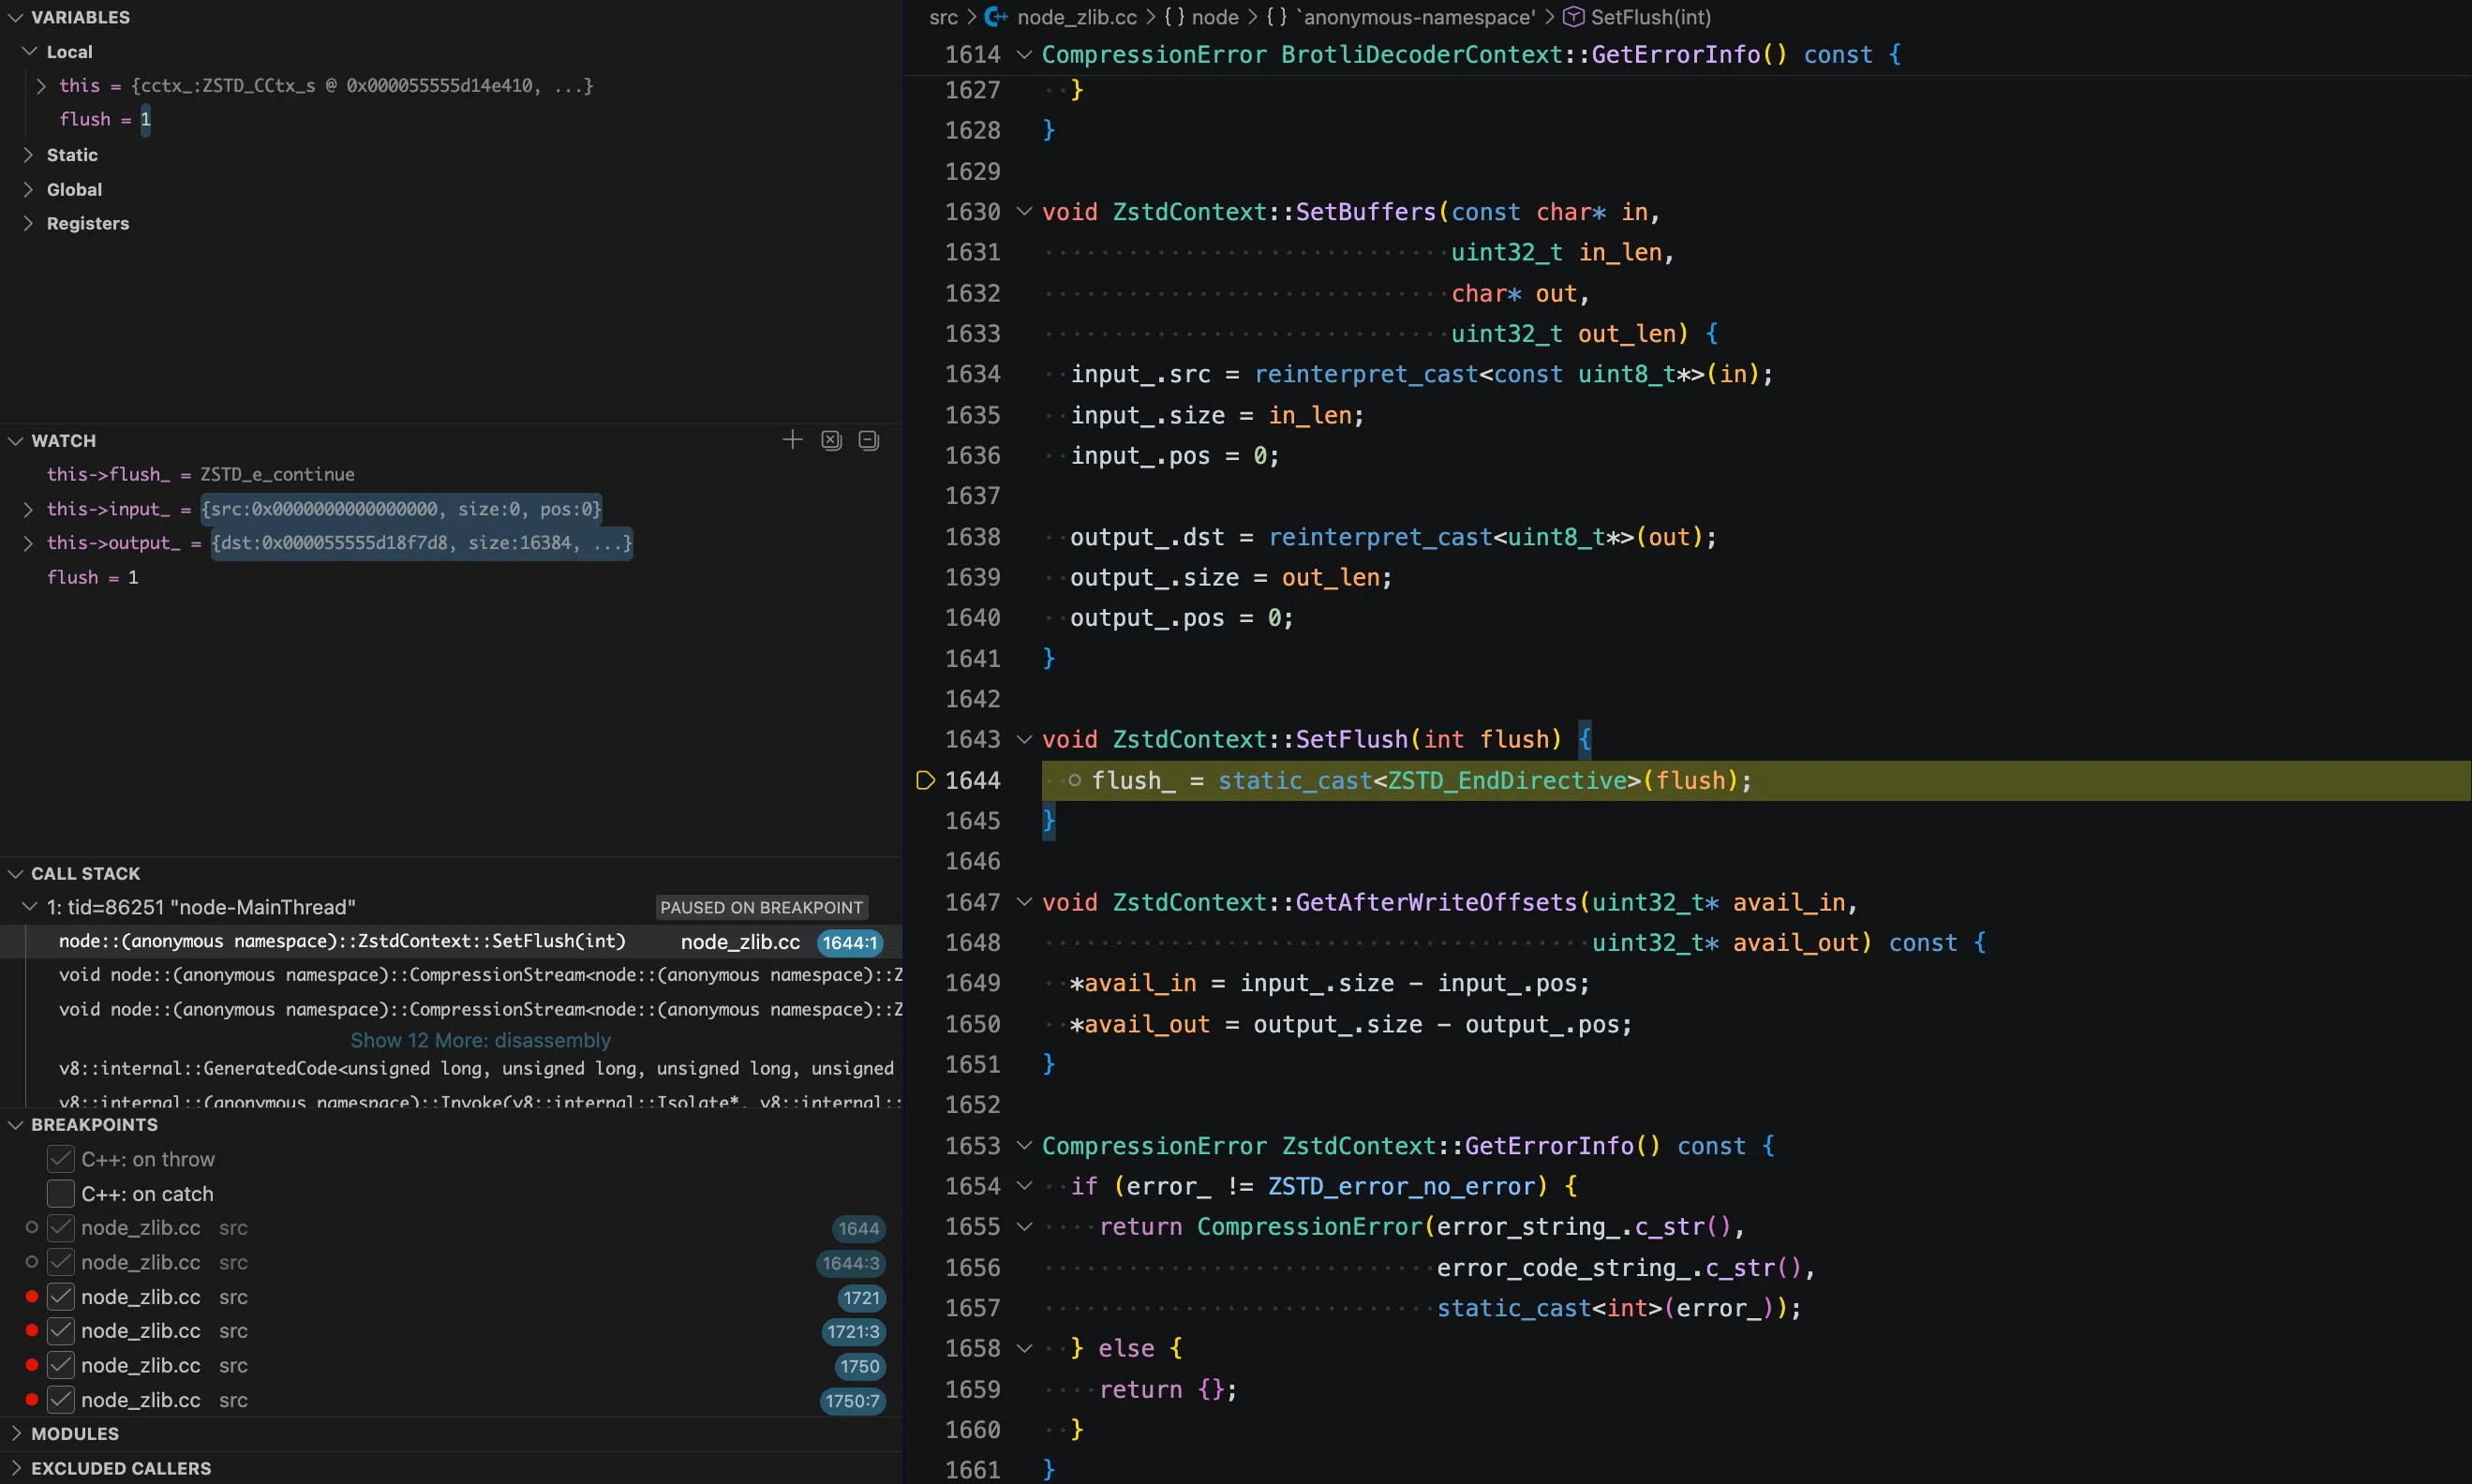
3. flush() → SetFlush, flush = 1 (ZSTD_e_flush)
Same breakpoint, now with the value that forces output.
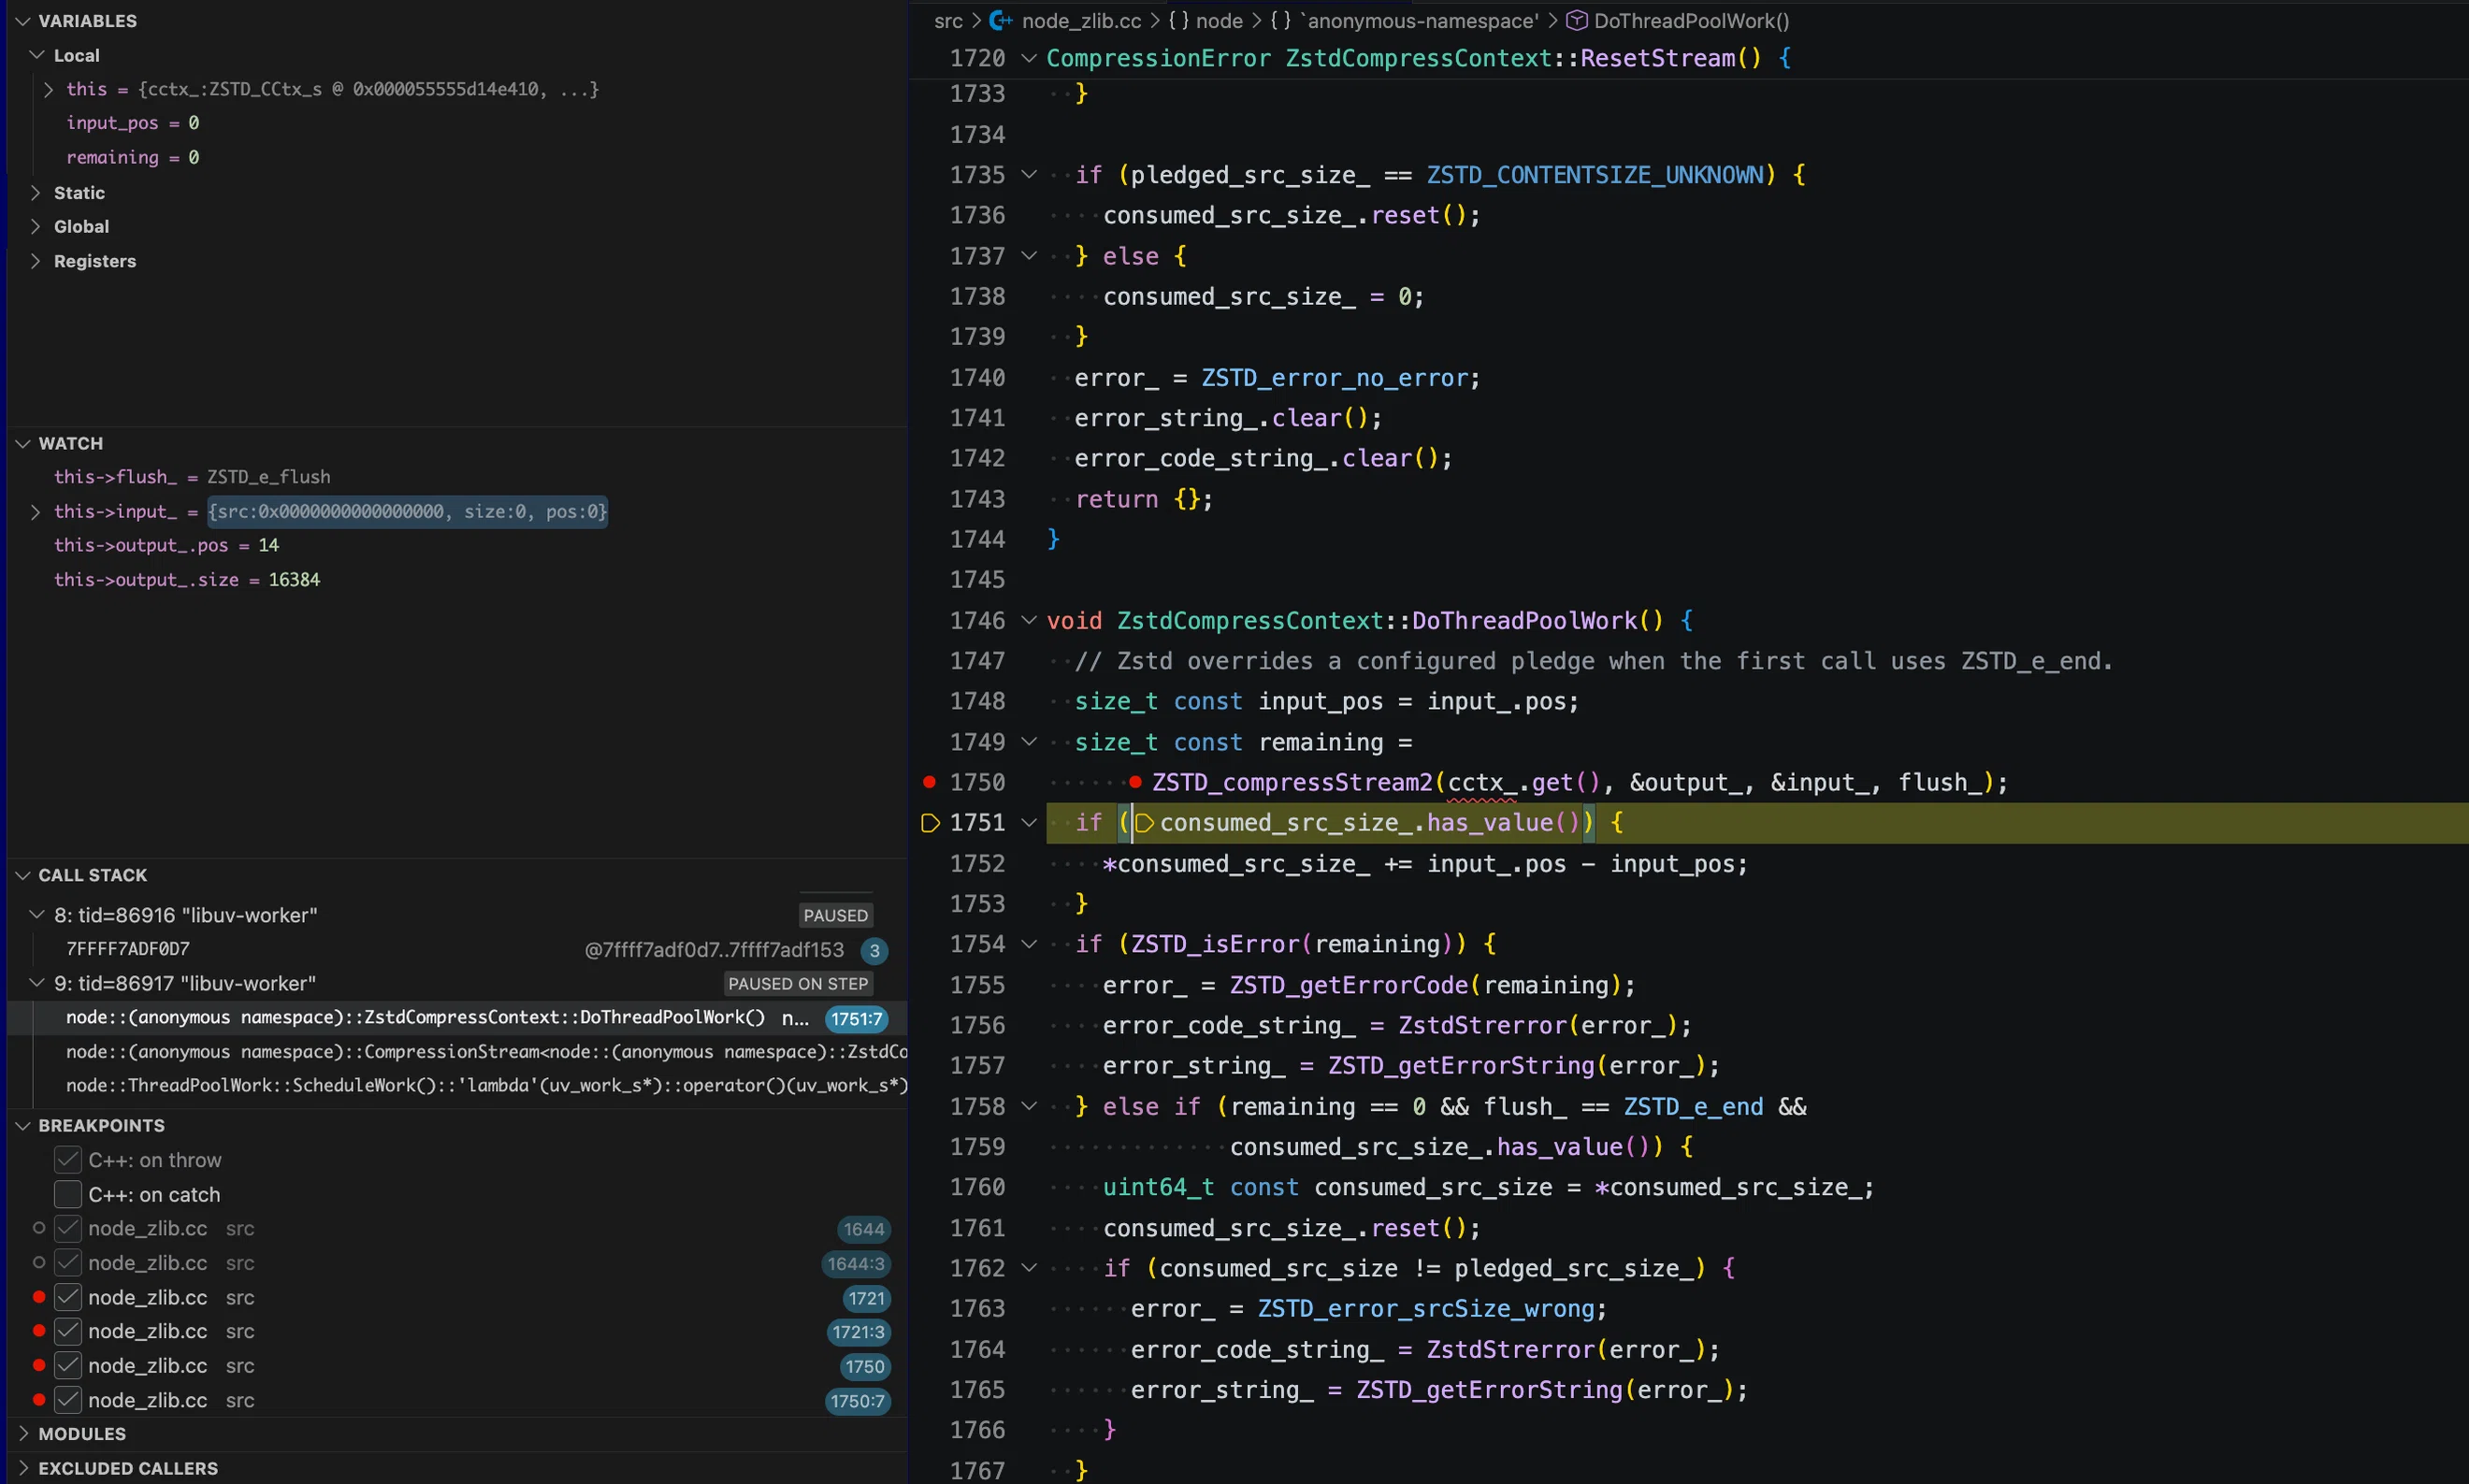
4. DoThreadPoolWork with flush_ = ZSTD_e_flush, before the call
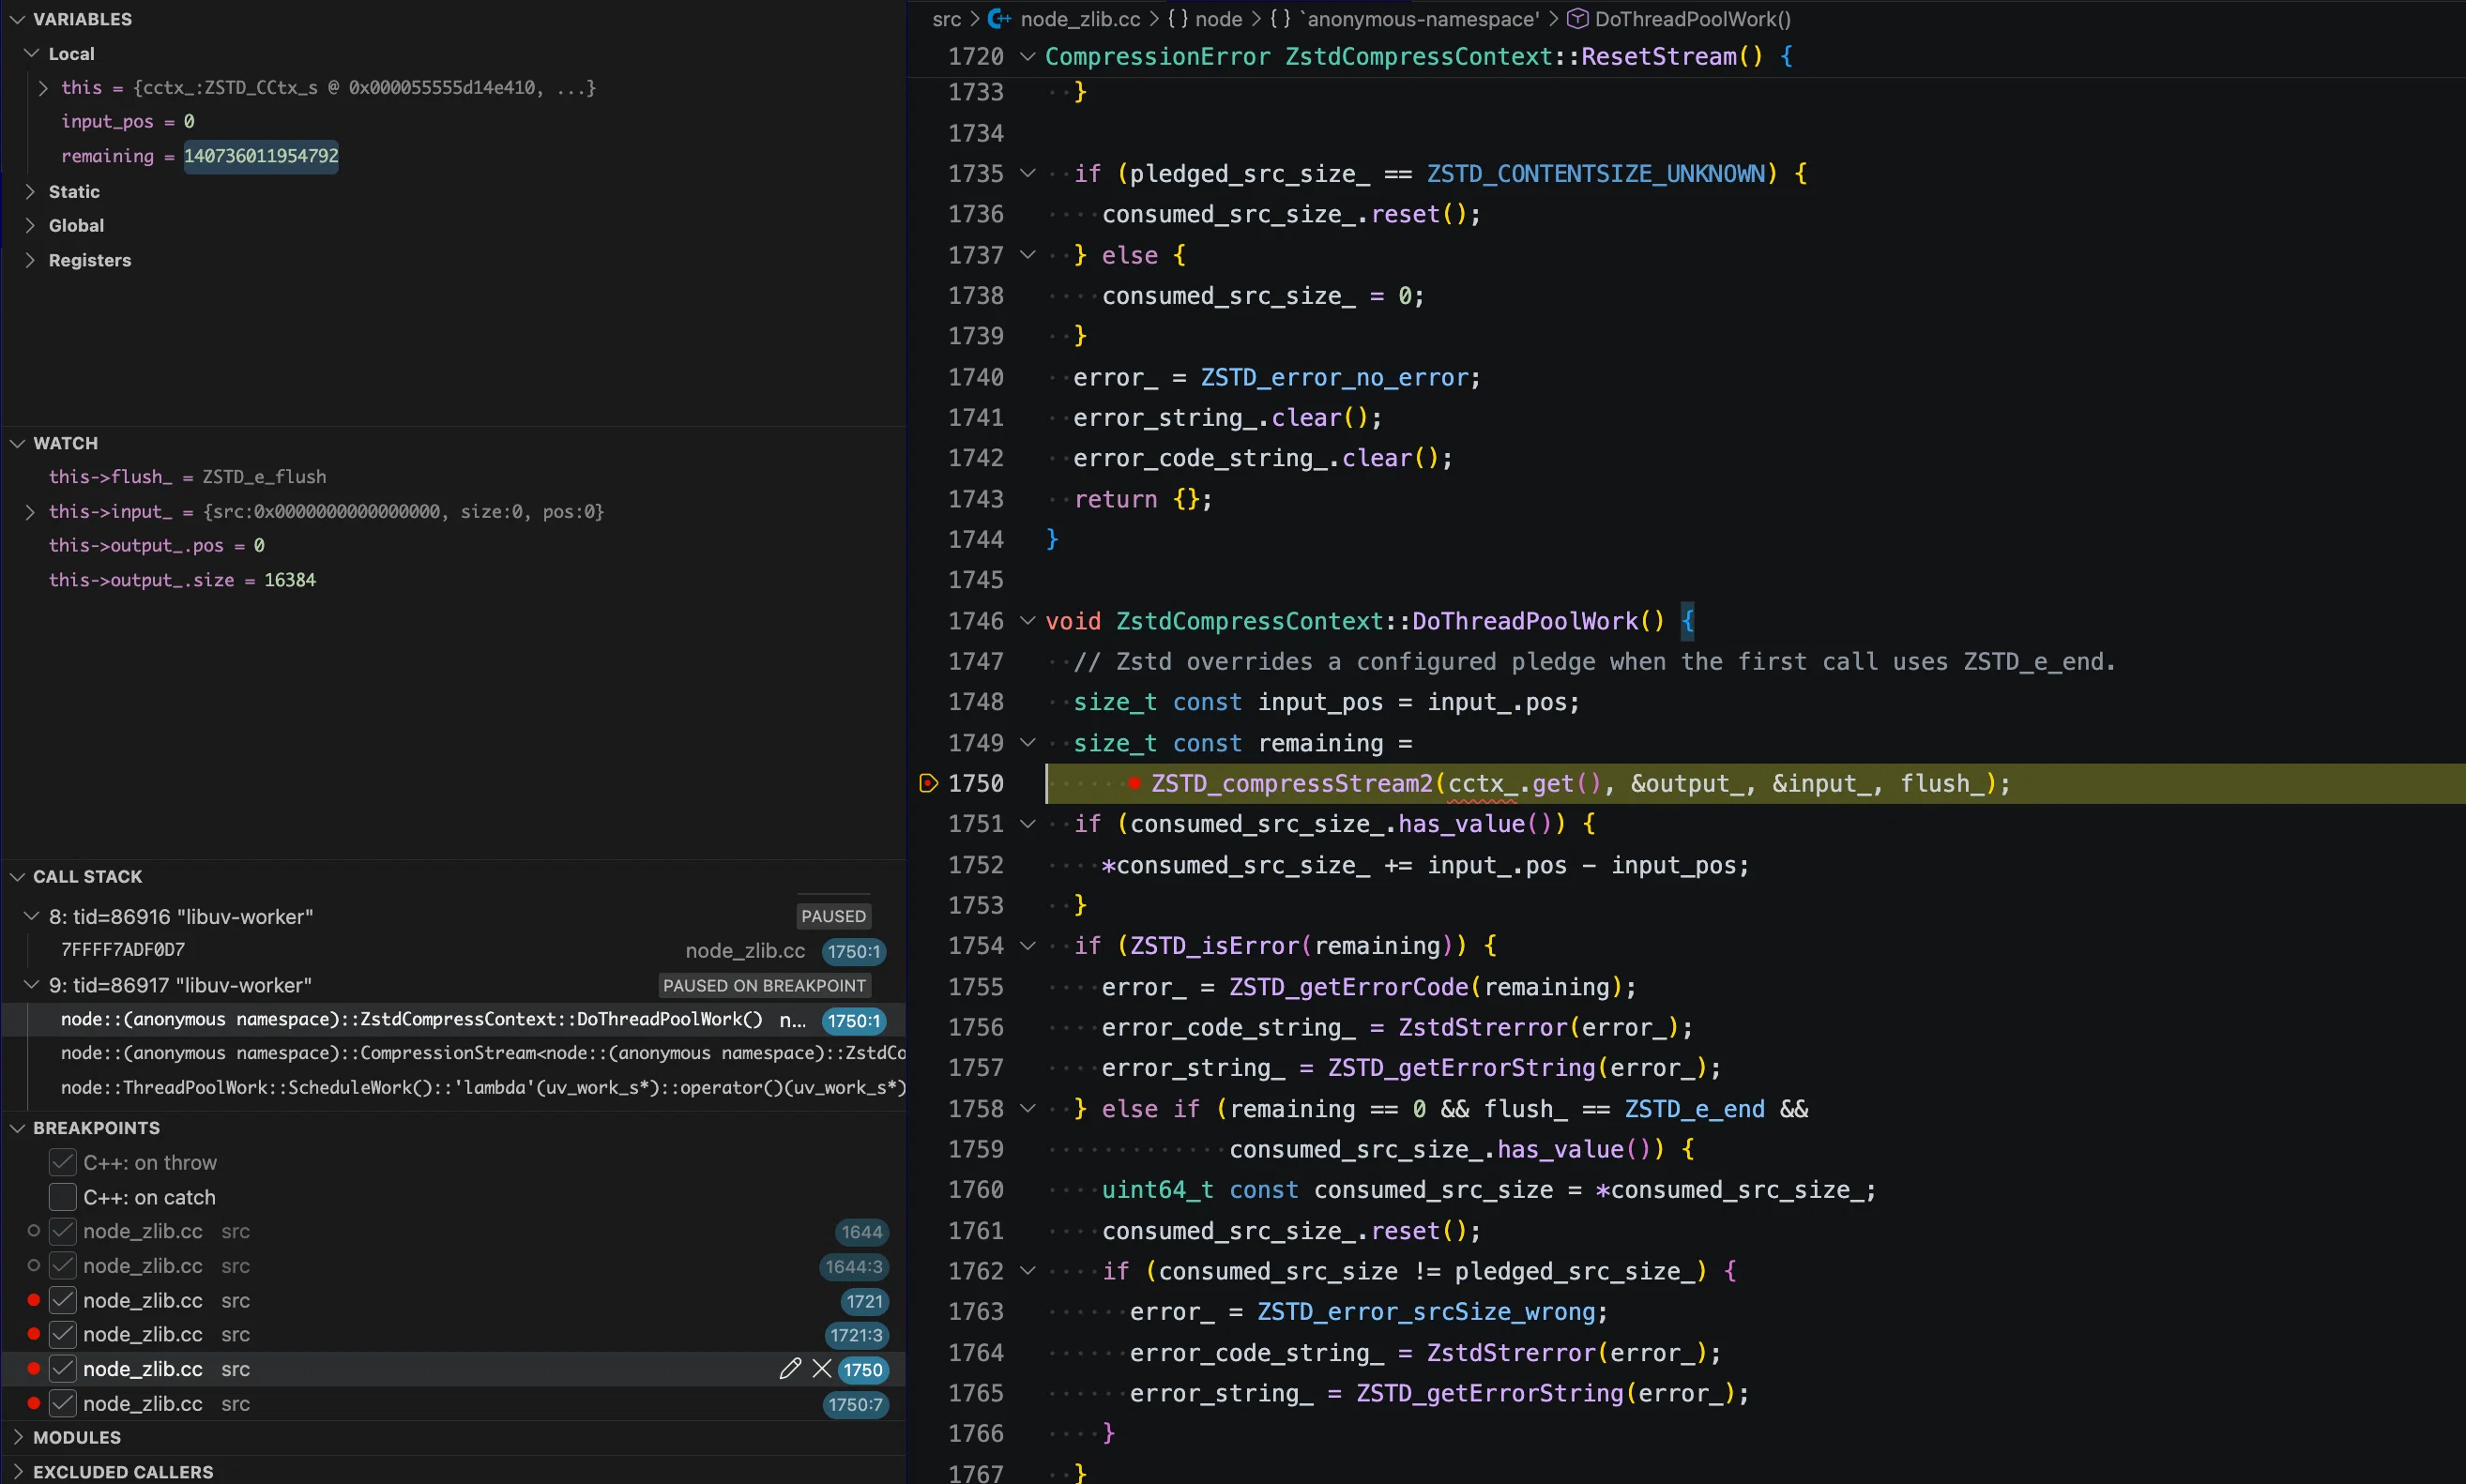
5. After stepping over the call: output_.pos = 14
input_ is empty, but 14 bytes were flushed out — an unfinished frame.
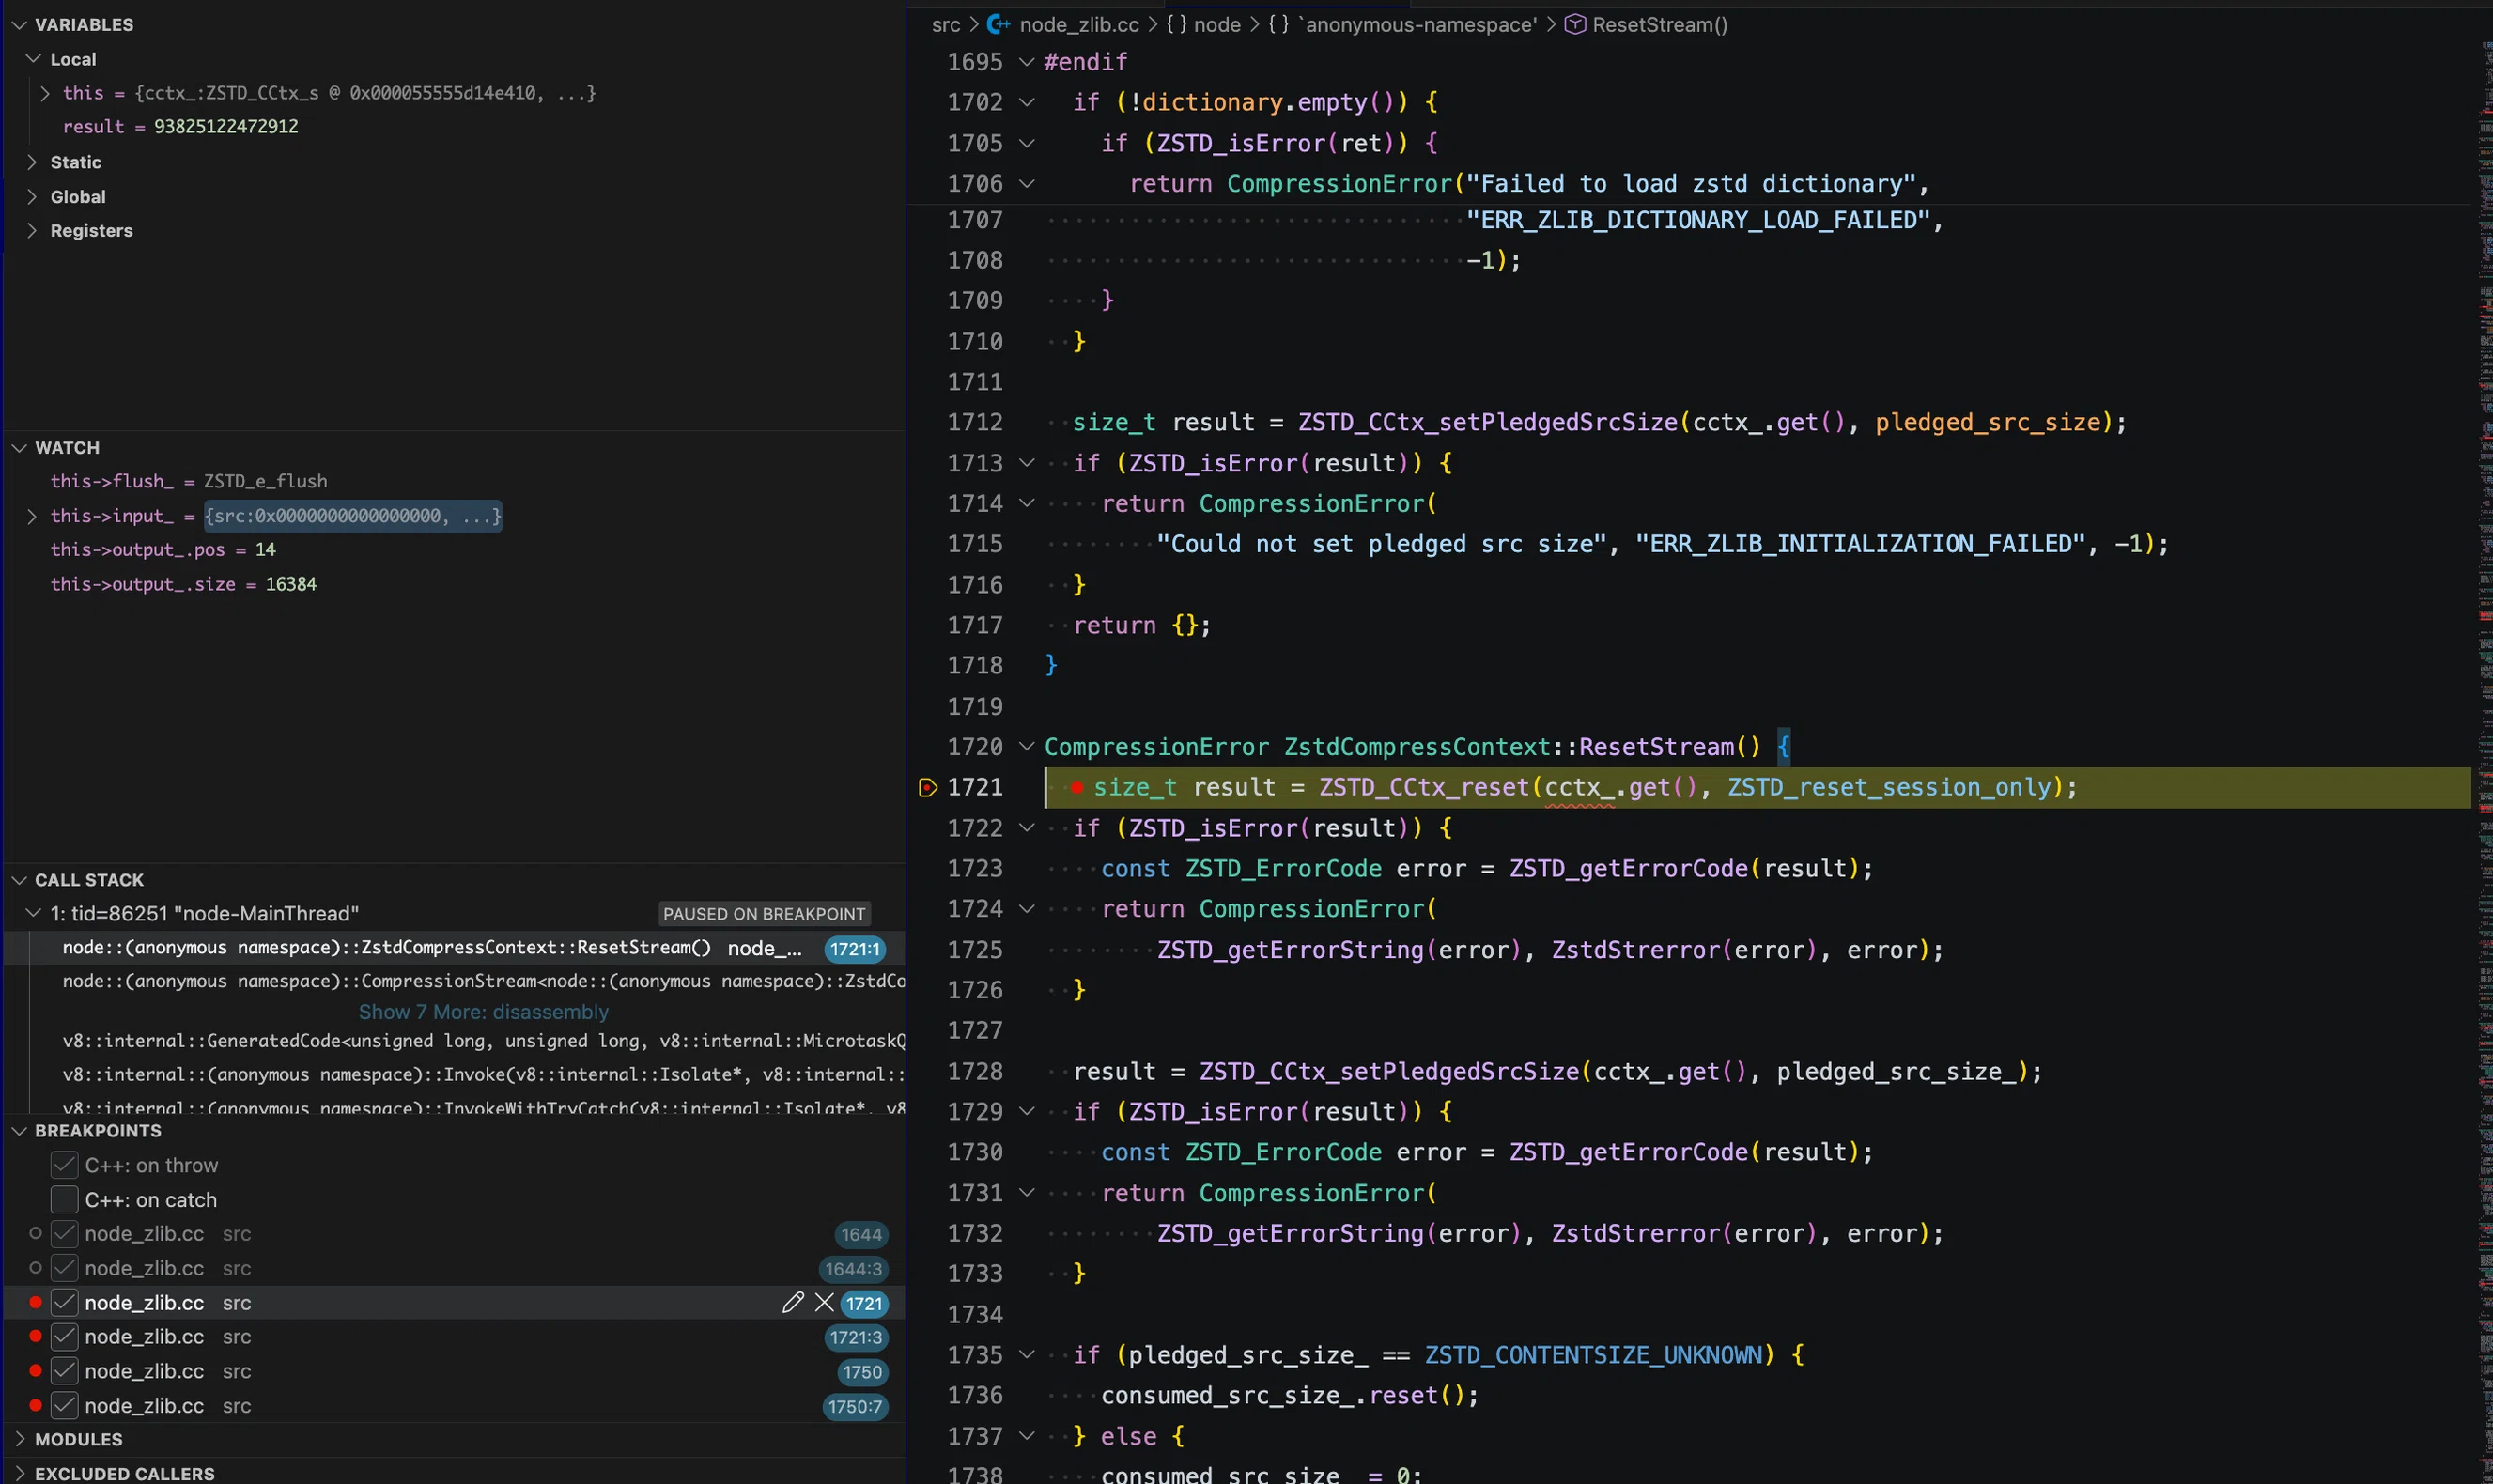
6. reset() → ResetStream runs ZSTD_CCtx_reset(session_only)
The 14 bytes are already out, but the frame state is about to be dropped.
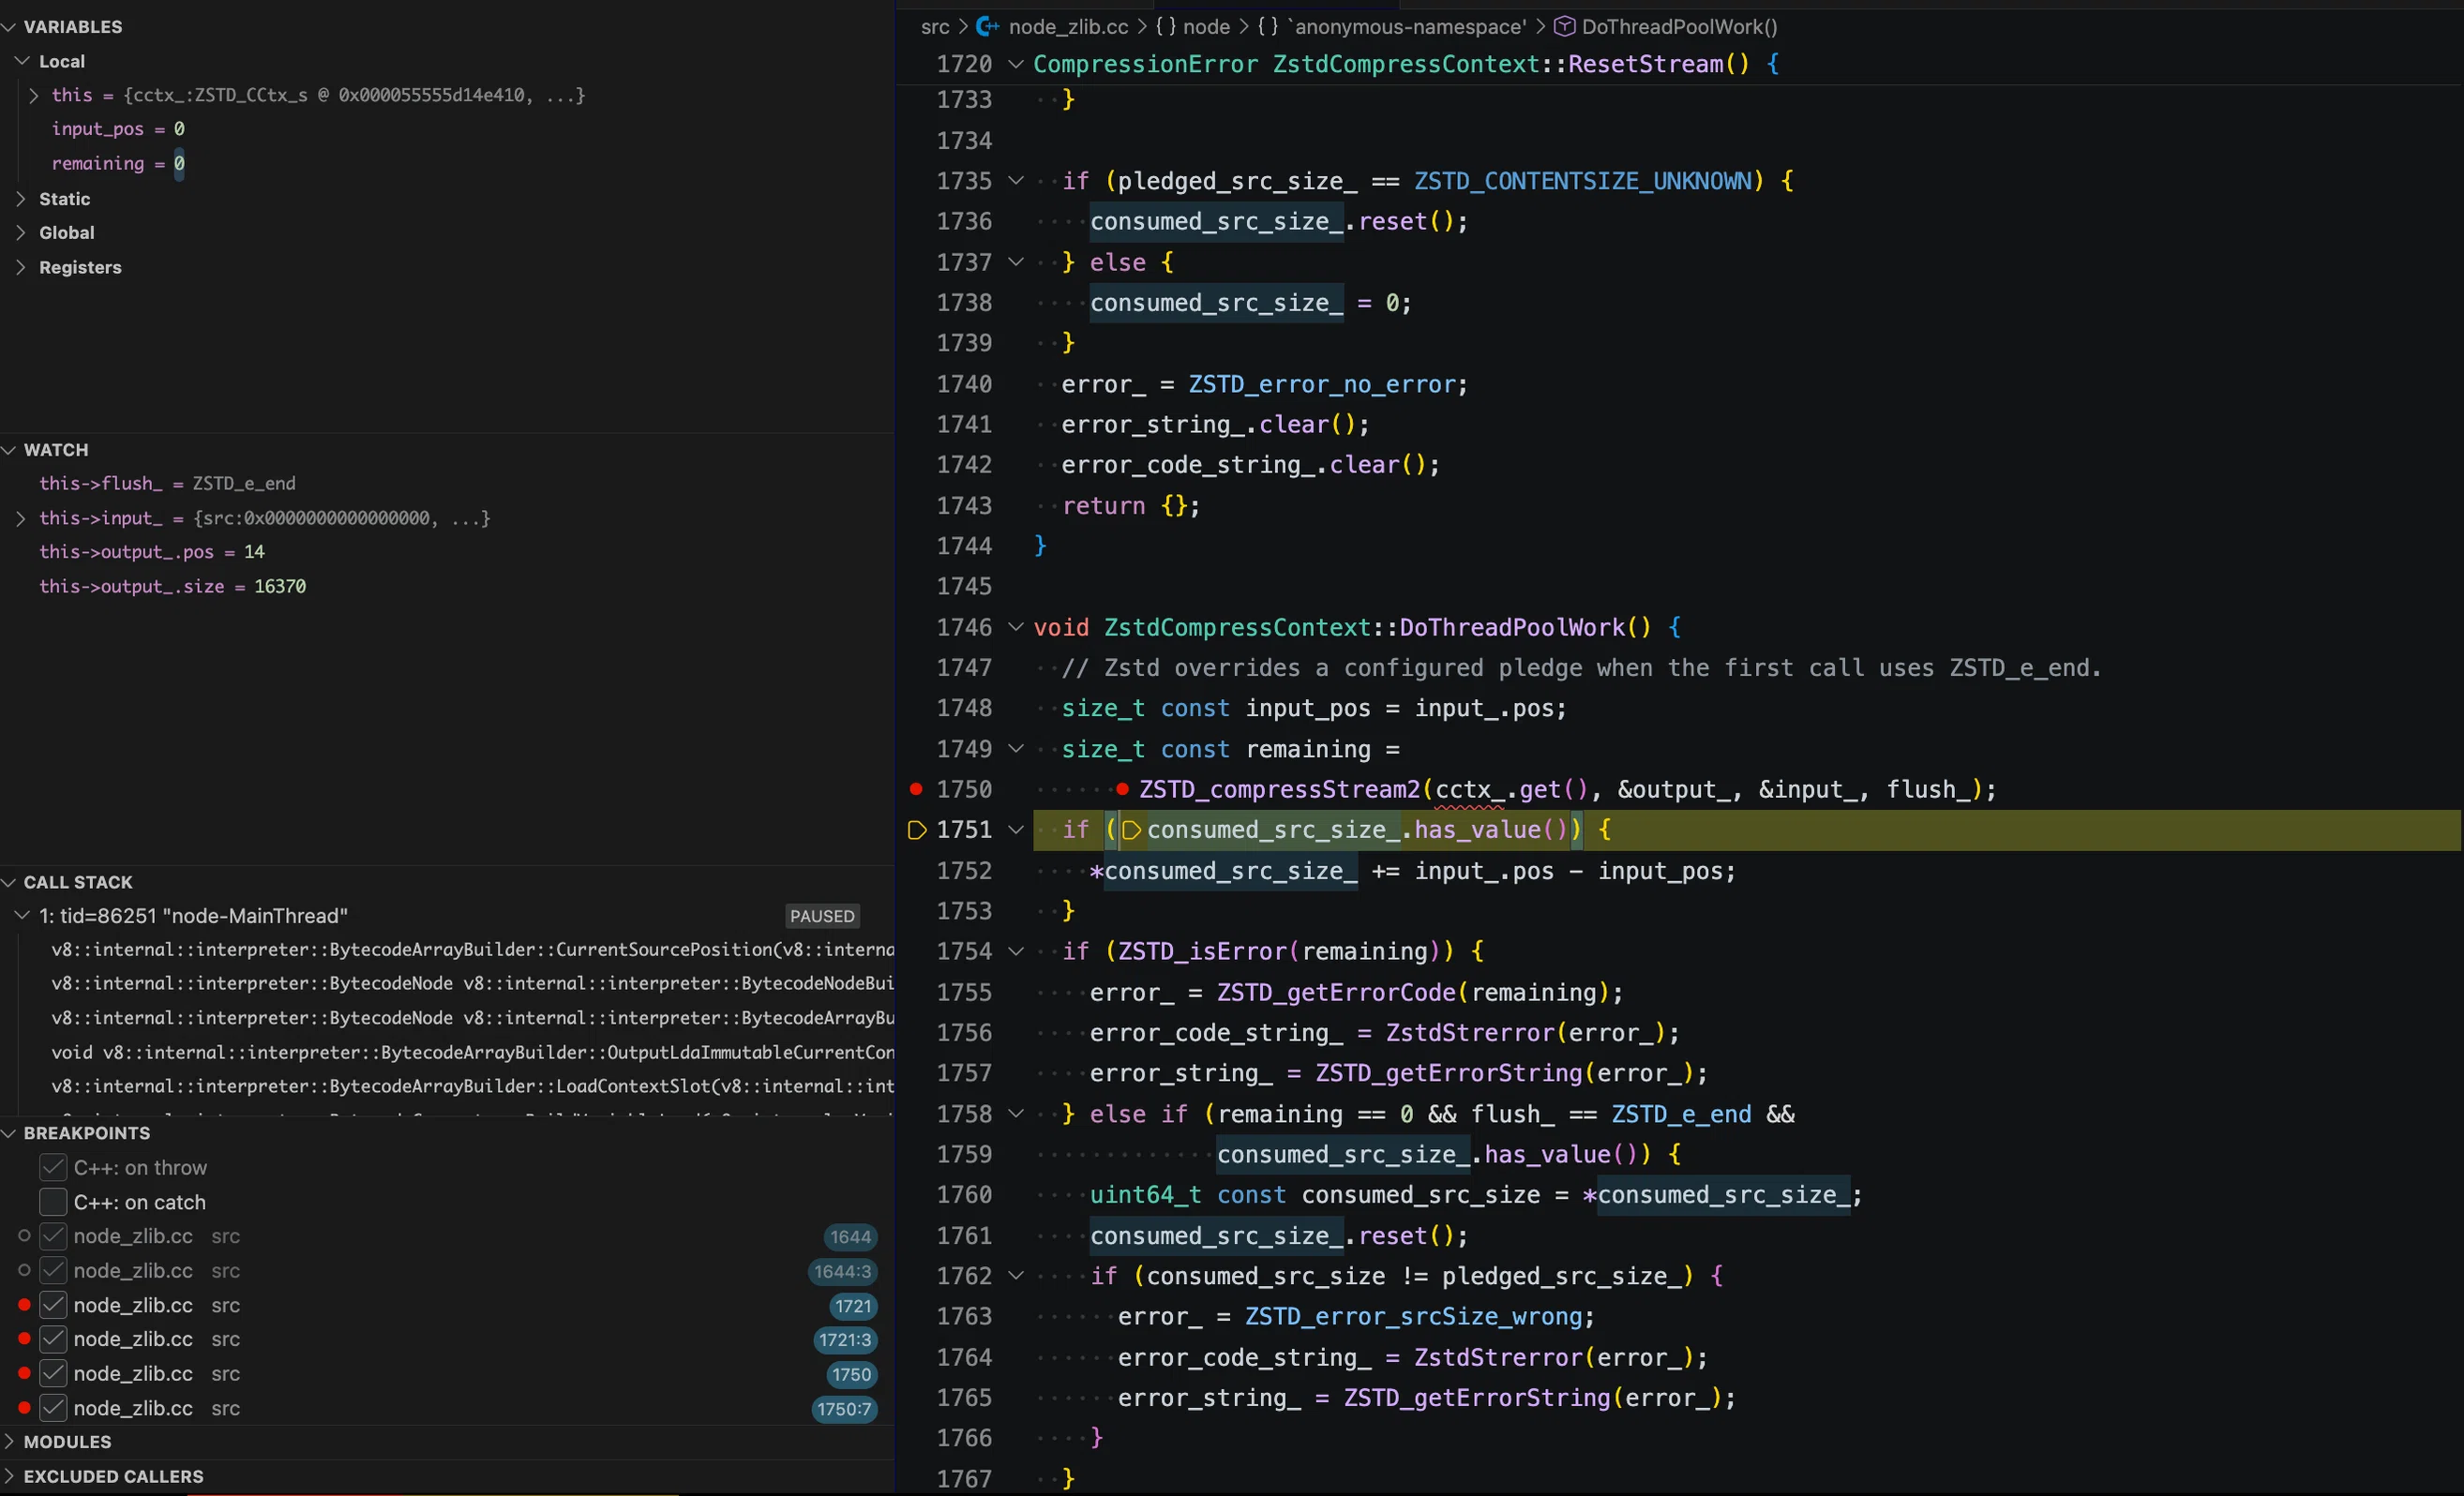
7. end() → DoThreadPoolWork with flush_ = ZSTD_e_end produces another 14 bytes
A fresh frame, not a continuation of the previous one. 14 + 14 = the 28 bytes
above.
Other codecs are affected the same way. gzip and brotli both produce
undecodable output for the same flush() + reset() sequence, so this is not
specific to the zstd backend:
| codec | result of flush() + reset() |
|---|---|
| gzip | Z_DATA_ERROR |
| brotli | ERR__ERROR_FORMAT_PADDING_2 |
| zstd | ZSTD_error_corruption_detected |
The zstd case is arguably the worst of the three because the compressor itself
reports nothing at all — with gzip/brotli the failure at least surfaces on the
same stream.
贡献指南
从这里开始
- 先读完整个 Issue,再读项目的贡献指南。
- 在 Issue 下留言说明你要接手 —— 这能避免两个人做同样的事。
- Fork 仓库,在一个分支上完成修改。
- 提交 Pull Request,并在描述里引用这个 Issue 编号。
调研方向
首先使用 node:zlib 重现 JavaScript 示例,然后跟踪 SetFlush、DoThreadPoolWork 和 ResetStream 周围的 flush 和 reset 路径。阅读 deps/zstd/lib/zstd.h 中引用的 ZSTD_compressStream2 指导,并比较 zstd 与 gzip 和 brotli 的行为。完成的标准是 flush/reset 序列不会静默地产生无法解码的输出,并且针对已报告的案例有回归测试覆盖。
由索引模型根据 Issue 内容生成。
评估
- 技术栈
- javascript, nodejs
- 领域
- backend
- Issue 类型
- 缺陷
- 难度
- 4/5
- 预计耗时
- 3-5 天
- 活跃度
- 活跃
- 描述清晰度
- 基本清楚
- 新手友好度
- 55/100