huggingface / huggingface/diffusers
Make the input `UNet2DConditionModel` and the returned `UNetMotionModel` instances share weights
- 主要言語
- Python
- スター
- 34.5k
- フォーク
- 7.3k
- 平均マージ
- 3日 3時間
- マージ済み PR(30日)
- 91
説明
**What API design would you like to have changed or added to the library? Why?**
[diffusers.UNetMotionModel](https://huggingface.co/docs/diffusers/main/en/api/models/unet-motion#diffusers.UNetMotionModel).from_unet2d
https://github.com/huggingface/diffusers/blob/6be43bd855772f5ffb064bc7c6049f578b3856f8/src/diffusers/models/unets/unet_motion_model.py#L431-L437
**New feature**
Add an option to make the input `UNet2DConditionModel` and the returned `UNetMotionModel` instances share weights (Res, SA, CA).
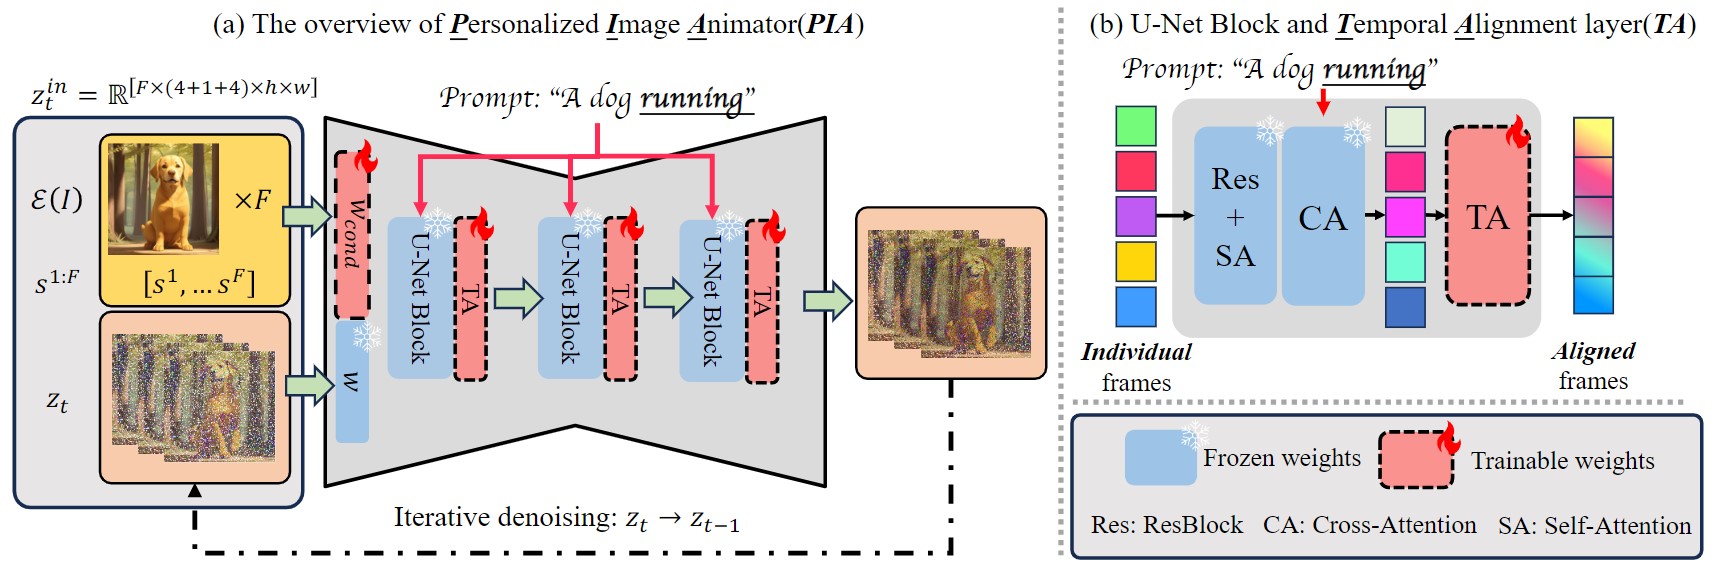
> Image from [PIA project page](https://pi-animator.github.io)
**What use case would this enable or better enable? Can you give us a code example?**
In the [example](https://huggingface.co/docs/diffusers/en/api/pipelines/pia#usage-example) in the current doc of PIA, users can provide an existing image to generate a video (img2vid). However, one can also perform text2vid by using an image pipeline to generate the input image first. In such case, it would be best if we only make **one copy** of the weights (Res, SA, CA) in both unets of image and video pipeline.
| Modules | Res | SA | CA | TA | `conv_in` (first 4 ch) | `conv_in` (last 5 ch) |
|-|-|-|-|-|-|-|
|`UNet2DConditionModel`|✅|✅|✅|❌|✅|❌|
|`UNetMotionModel`|✅|✅|✅|✅|✅|✅|
**Note**
The additional channels in `conv_in` takes neglectable amount of vram, and I don't know if it is possible to share only half of this module.
コントリビューションガイド
調査の方向性
src/diffusers/models/unets/unet_motion_model.py から始め、特にリンクされた行の周辺にあるエントリポイント from_unet2d を確認し、PIA の使用例で画像パイプラインと動画パイプラインをどのように構築しているかを調べます。モーション固有のモジュールと異なる conv_in チャネルを維持しながら、Res、SA、CA の重みを共有するというオプションの動作を定義します。入力の UNet2DConditionModel と返される UNetMotionModel がそれらの重みを共有すれば完了です。
索引モデルが issue の本文から書いたものです。
評価
- 技術スタック
- python, pytorch
- 領域
- machine-learning
- issue の種類
- 機能追加
- 難易度
- 5/5
- 見積もり時間
- 1週間以上
- 活発さ
- 停滞
- 明瞭さ
- おおむね明確
- 初心者へのやさしさ
- 35/100