huggingface / huggingface/diffusers
Make the input `UNet2DConditionModel` and the returned `UNetMotionModel` instances share weights
- Dominant language
- Python
- Stars
- 34.5k
- Forks
- 7.3k
- Avg merge
- 3d 3h
- Merged PRs (30d)
- 91
Description
**What API design would you like to have changed or added to the library? Why?**
[diffusers.UNetMotionModel](https://huggingface.co/docs/diffusers/main/en/api/models/unet-motion#diffusers.UNetMotionModel).from_unet2d
https://github.com/huggingface/diffusers/blob/6be43bd855772f5ffb064bc7c6049f578b3856f8/src/diffusers/models/unets/unet_motion_model.py#L431-L437
**New feature**
Add an option to make the input `UNet2DConditionModel` and the returned `UNetMotionModel` instances share weights (Res, SA, CA).
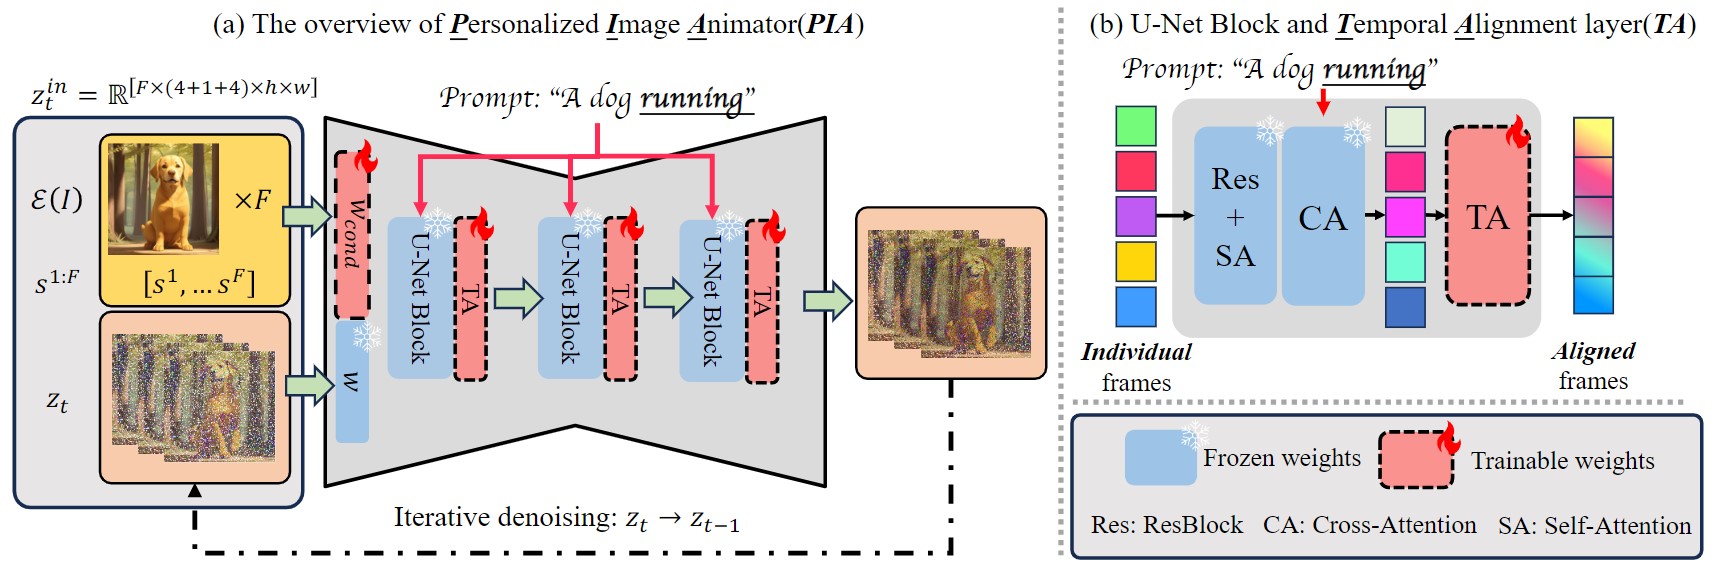
> Image from [PIA project page](https://pi-animator.github.io)
**What use case would this enable or better enable? Can you give us a code example?**
In the [example](https://huggingface.co/docs/diffusers/en/api/pipelines/pia#usage-example) in the current doc of PIA, users can provide an existing image to generate a video (img2vid). However, one can also perform text2vid by using an image pipeline to generate the input image first. In such case, it would be best if we only make **one copy** of the weights (Res, SA, CA) in both unets of image and video pipeline.
| Modules | Res | SA | CA | TA | `conv_in` (first 4 ch) | `conv_in` (last 5 ch) |
|-|-|-|-|-|-|-|
|`UNet2DConditionModel`|✅|✅|✅|❌|✅|❌|
|`UNetMotionModel`|✅|✅|✅|✅|✅|✅|
**Note**
The additional channels in `conv_in` takes neglectable amount of vram, and I don't know if it is possible to share only half of this module.
Contributor guide
Assessment
This issue has not been assessed yet.