flowable / flowable/flowable-engine
Frequent Async message Send and Receive bug while use Kafka
- Lingua principale
- Java
- Stelle
- 9.5k
- Fork
- 2.9k
- Merge medio
- 7h 8m
- PR unite (30g)
- 2
Descrizione
**Describe the bug**
In version 6.4.0, and in version 6.0. because I read the sourcode both of them.
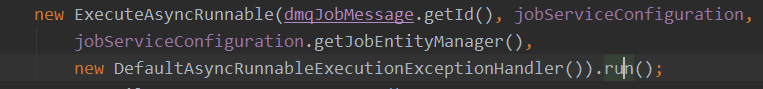
I use kafka as async job Manager(extends AbstractMessageBaseJobManager) and send message to kafka. The consumer consumes the job message and call ExecuteAsyncRunnable's run method to exeucte asyc job.
I record the log info while send and receive job message called send and receive log.
Occasionally, very frequently send and receive log happened which caused CPU up to 100%. Only suspend the flow can recover the cpu load.
**Expected behavior**
Only once send and receive of job message.
**Code**
In org.flowable.job.service.impl.asyncexecutor.ExecuteAsyncRunnable#run, lockjob() method will be executed.

When lockjob() failed, the bug will be reproduced.
Because in org.flowable.job.service.impl.asyncexecutor.ExecuteAsyncRunnable#lockJob, the catch block whill call unacuqireJob() and this method will resend the job message. Then rotated,circle, repeated send and receive.

But I don't know which Exeception is throwed to cause this bug.
One possible reason is repeated consuming of kafka message. once one message consumed two time at one time. one message can lock the Execution Entity in DB using column LOCK_TIME_ in table act_ru_execution. Then the next same message try to lock the same execution ,but it is failed.

**Additional context**
Add the version of Flowable that you are using, the database vendor and if you are using Flowable within Spring Boot, the Flowable Task application etc.
Guida per i contributori
Nessuna guida per i contributori indicizzata per questo repository
Direzione di ricerca
Inizia con ExecuteAsyncRunnable#run e lockJob, quindi esamina il percorso catch attraverso unacquireJob, dove l’issue segnala che il messaggio viene inviato nuovamente. Riproduci gli invii e le ricezioni ripetuti con Kafka osservando il lock di esecuzione in act_ru_execution e acquisisci l’eccezione che causa il fallimento di lockJob. Il lavoro è completato quando la causa del fallimento è stata identificata e il ciclo di messaggi ripetuti non porta più la CPU al 100%.
Scritto dal modello di indicizzazione a partire dal testo della issue.
Valutazione
- Stack tecnologico
- java, kafka
- Ambito
- backend, databases, distributed-systems
- Tipo di issue
- Bug
- Difficoltà
- 4/5
- Tempo stimato
- 3-5 giorni
- Stato di attività
- Ferma
- Chiarezza
- Da chiarire
- Idoneità per principianti
- 25/100