dotnet / dotnet/machinelearning-modelbuilder
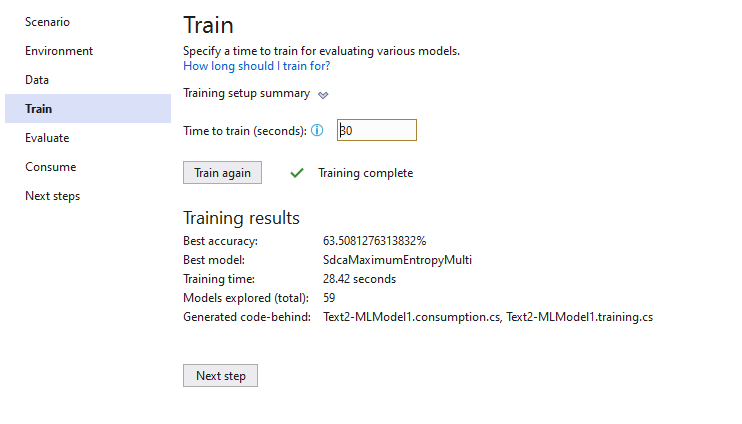
Should not complete the train for the incorrect data type.
- Vorherrschende Sprache
- Dockerfile
- Sterne
- 285
- Forks
- 66
- PR-Merge-Kennzahlen
- Keine gemergten PRs in 30 T.
Beschreibung
**System Information (please complete the following information):**
- Windows OS: Windows-10-Enterprise-21H1
- ML.Net Model Builder (Preview): 16.6.2.2136201 (Main Branch)
- Microsoft Visual Studio Enterprise 2019: 16.10.2
- .Net: 5.0.301
**Describe the bug**
- On which step of the process did you run into an issue: Evaluate page
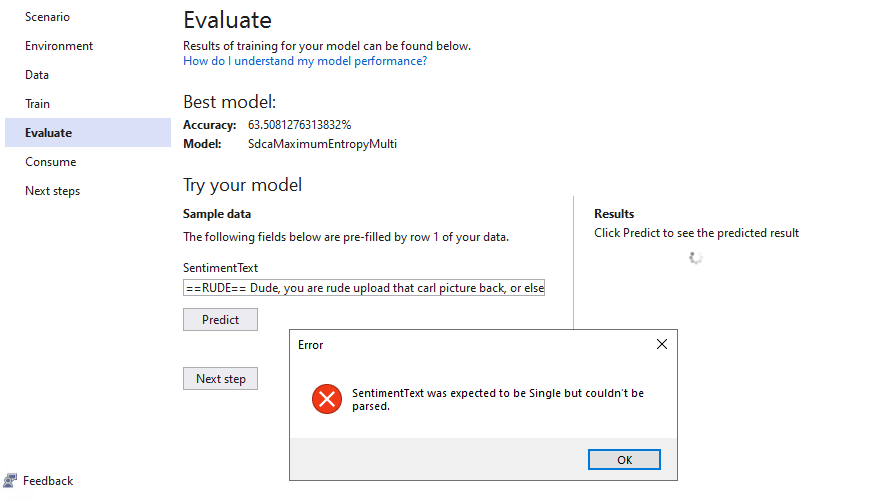
- Clear description of the problem: A "couldn't be parsed" error occurred on evaluate page, but there was no message during training period to warn that the data type was incorrect. If the data source is large, and it takes a long time to complete the train, finally be told some data types are incorrect, then back to change the data type, and then retrain. This experience is not very good for the user.
**To Reproduce**
Steps to reproduce the behavior:
1. Select Create a new project from the Visual Studio 2019 start window.
2. Choose the C# Console App (.NET Core) project template with .Net 5.0;
3. Add model builder by right click on the project;
4. Set "Sentiment" to Label, and set "SentimentText" to Single type that only has strings;
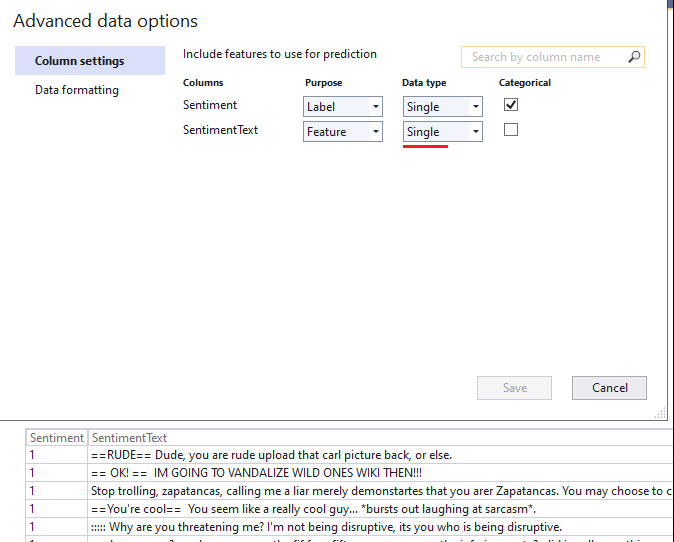
5. Find that can be trained successfully;
6. Navigate to Evaluate page, click "Predict" button, pop up error dialog: SentimentText was expected to be Single but couldn't be parsed.
**Expected behavior**
Hope that the "couldn't be parsed" error can appear in the training phase in advance to remind user if the data type is incorrect.
**Additional context**
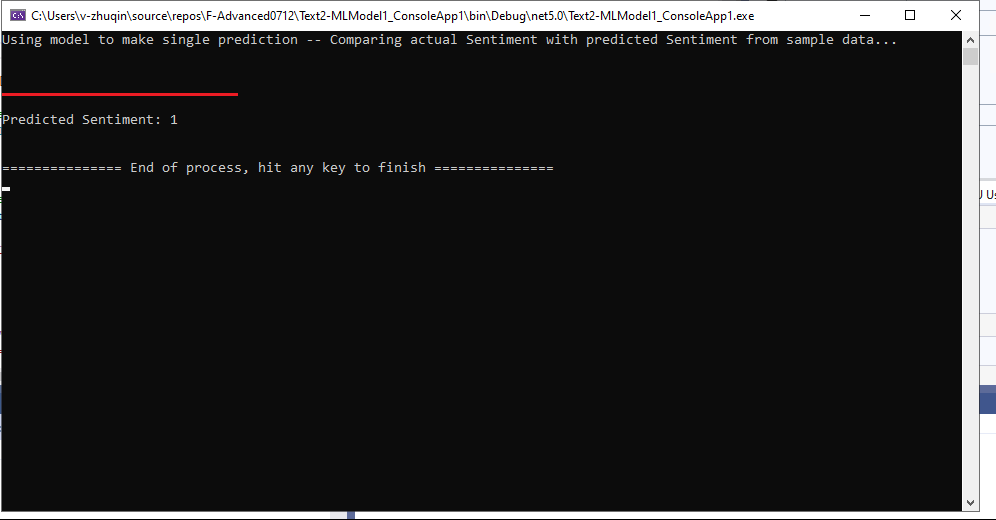
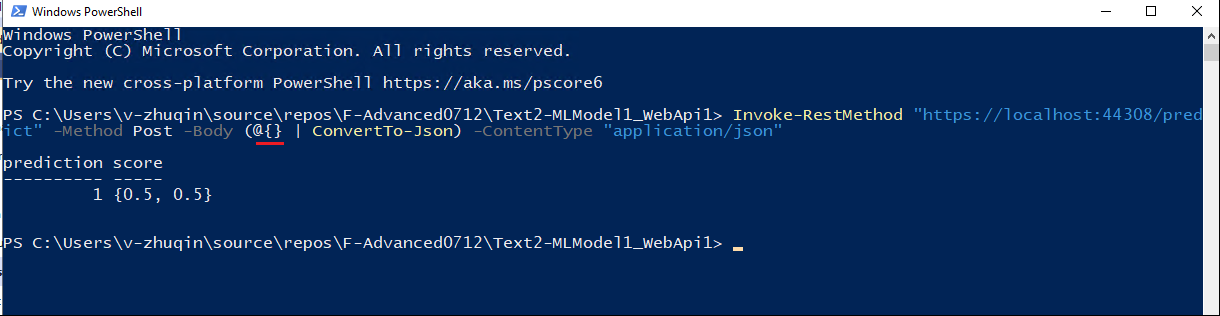
And find that can run the added ConsoleApp and WebApi projects without input:
Beitragsleitfaden
Für dieses Repository ist kein Beitragsleitfaden indexiert
Bewertung
Dieses Issue wurde noch nicht bewertet.