fail to reproduce the result of the Wikihop dataset
- 主要语言
- Python
- 星标
- 2.2k
- 派生
- 286
- PR 合并指标
- 30 天内没有已合并 PR
描述
Following the implementation detail in Longformer paper, as below, I tried to reproduce the Roberta result on wikihop dataset, but only got f1 66.47 (lr=3e-5, epoch15, bsz64), much lower than 72.4 (in paper).
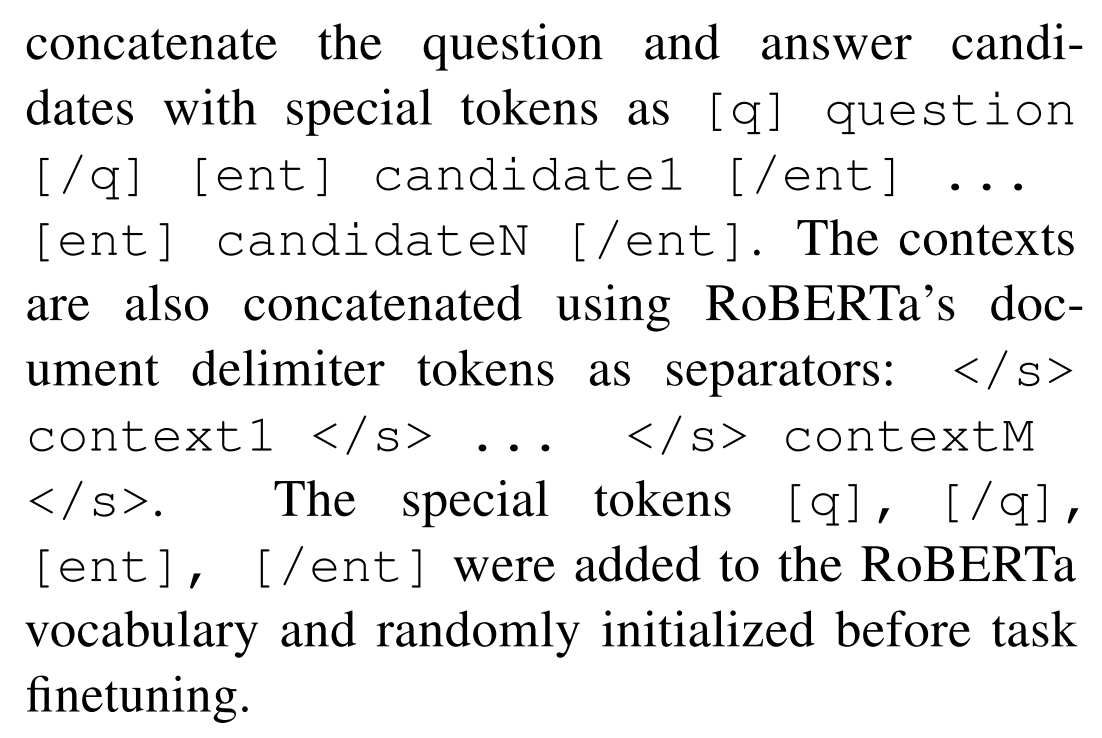
I want to check the way I implemented is correct.
1. There is only one sample in one batch, and each row of the batch stores one chunk of the sample.
2. Each chunk is represented as **[q] question [/q] [ent] cand1 [/ent] [ent] cand2 [/ent] ... [ent] candN [/ent] context1 **, always carried with **[q] question [/q] [ent] cand1 [/ent] [ent] cand2 [/ent] ... [ent] candN [/ent]** .
3. I found the question in wikihop dataset is composed by a property and an object, such as
> member_of_political_party thomas l. woolwine
so I replace the '_' with a whitespace.
4. do not shuffle multiple contexts (supports) in one sample
5. do not shuffle candidates in one chunk
Any suggestions and comments are welcomed. Thanks.
贡献指南
这个仓库没有索引到贡献指南
评估
这个 Issue 还没有评估数据。