akarnokd / akarnokd/akarnokd-misc
RxJava 1, 2 & Reactor comparison benchmarks 14-03-2018
- Linguagem predominante
- Java
- Estrelas
- 54
- Forks
- 20
- Merge médio
- 1h 20min
- PRs com merge (30d)
- 5
Descrição
## Environment
- i7 4790 stock settings
- Windows 10 x64 fully patched
- Java 8u162
- RxJava 1.3.6
- RxJava 2.1.10
- Reactor Core 3.2.0-M1 (53582aeb14ead1dc7b1f19a0f7f682b74287a6c7)
- [JMH Compare GUI](https://github.com/akarnokd/jmh-compare-gui/releases/tag/v1.3.2) workspace: [benchmarks_180314.xml](https://gist.github.com/akarnokd/20bb54cab8e6870fce86e90216f378a6)
### Memory usage
These tests check how much memory is allocated when working with 1,000,000 instances of varios flows and components (total megabytes, smaller is better, green is better):

Notes:
- I'm not aware of any Async- and Behavior-like processors in Reactor
- `Flowable.empty()` is surprisingly large
- Looks like reactor has some extra storage in various operators while others do benefit from having to no worry about atomic field updaters.
### Async throughput
This benchmark measures how many items can be transferred over a flow when work stealing is possible (async) or the source and consumers are pinned to a specific thread (pipeline):

The tests use `Executor`s wrapped into schedulers, not the built-in schedulers. Reactor is clearly winning in both situations. The likely reason for this is that by default, the RxJava wrappers for `Executor`s always trampoline while Reactor's default wrapper does not, saving on double trampolining.
### Blocking
These benchmarks measure the overhead of blocking for the first or last element of a 1,000,000 source or how much overhead presents itself when blocking for an empty source (ops/s, larger is better):

- Interesting to see why RxJava 1's last is so much faster than the others.
For the 0-1 types, there is only 0 or 1 element to wait for blockingly:


- Reactor's blocking method does contain optimizations for scalar and empty sources, bypassing the subscription and blocking entirely.
### Hot sources
These measure the throughput of various processor and subject types (ops/s, larger is better):

- Reactor has no equivalent of Async- and Behavior-type processor as of now
- It's interesting to see RxJava 1's Replay and Unicast subject perform better, worth investigating
- v2 BehaviorSubject and Processors have extra overhead due an additional lock per item to avoid latest-subscribe races.
### Subscribing
These measure the overhead of subscribing to various simple sources (ops/s, larger is better):

- The `Single` type sources would emit a pre-created exception instead of an item.
- Reactor is optimized for scalar and empty sources as well as it uses a weaker concurrency `just` implementation.
### Streaming
There are various sub-benchmarks measuring the multi-value behavior of various flows:
#### array
These measure the throughput when the source data is in an array, which minimizes GC due to autoboxing (see range below):
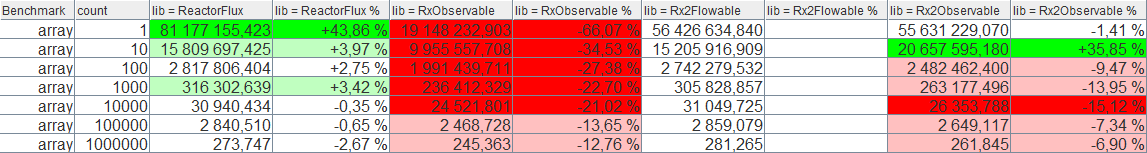
- Reactor uses a weaker concurrency `just` implementation (count == 1 case).
#### range
These measure the throughput when the source data is generated integers which get autoboxed, thus there is an additional GC overhead
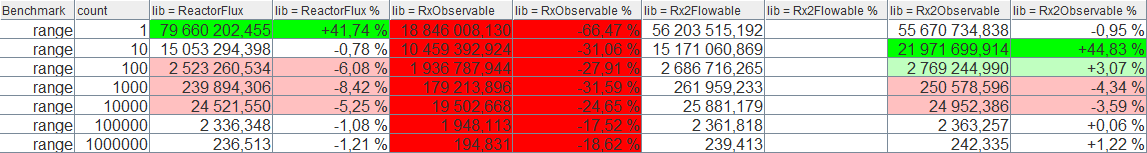
- Reactor uses a weaker concurrency `just` implementation (count == 1 case).
#### iterable
These measure the throughput when the source data is in an `Iterable`:

- It's odd how both Reactor and RxJava 2 `Observable` perform worse despite the presumably lower overhead on longer sequences.
#### concatMap onto just
These measure the throughput when a source sequence is mapped into plain `just` inner sources within `concatMap`:

- RxJava 2 `Observable.concatMap` is not optimized for scalar sources, thus the code goes through the regular subscription routine, adding a lot of overhead.
#### flatMap onto just
These measure the throughput when a source sequence is mapped into plain `just` inner sources within `flatMap`:
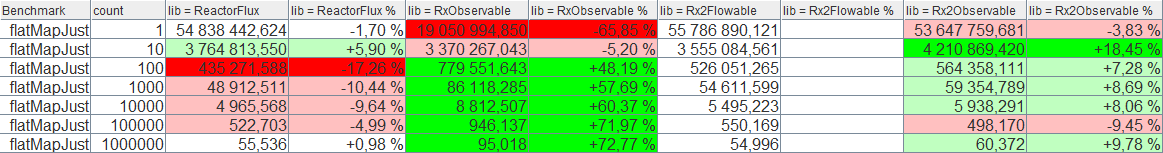
The reason v1 is faster is because it uses `synchronized` as the trampolining mechanic which gets optimized away by the JIT. The v2 version uses lock-free atomics which can't be optimized away but should have much better concurrent properties.
#### concatMap onto range
These measure the throughput when a source sequence is mapped onto a two element `range` within `concatMap`:

- The main overhead here is the request arbitration between subsequent inner sources, which doesn't happen in v2 `Observable`.
#### flatMap onto range
These measure the throughput when a source sequence is mapped onto a two element `range` within `concatMap`:
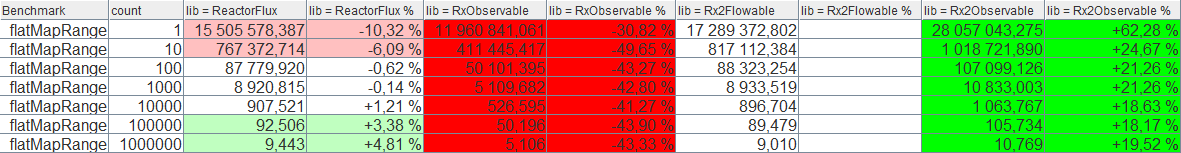
- The main overhead here is the request management with inner sources, which doesn't happen in v2 `Observable`.
#### concatMap cross-mapping
In these throughput measures, the total number of items is always 1,000,000, which is made out of the outer item `count` times the individual inner items: 10 x 100,000; 100 x 10,000 etc. It tells about if the `concatMap` prefers long outer sources or long inner sources:

#### flatMap cross-mapping
In these throughput measures, the total number of items is always 1,000,000, which is made out of the outer item `count` times the individual inner items: 10 x 100,000; 100 x 10,000 etc. It tells about if `flatMap` prefers long outer sources or long inner sources:

#### flatten onto scalar
These measure the `flatMapIterable` (`concatMapIterable` just an alias) performance which when mapped onto a singleton value. Unfortunately, there exist no standard way to detect an `Iterable` has a single value without trying to iterate through it.
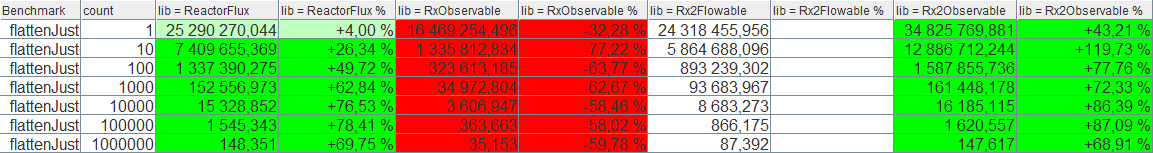
- Reactor is significantly faster here for some reason, as is the v2 `Observable`. It is worth investigating what causes the extra overhead in `Flowable`.
#### flatten onto a range
These measure the `flatMapIterable` (`concatMapIterable` just an alias) performance which when mapped onto a two element source.

#### flatten cross-mapping
In these throughput measures, the total number of items is always 1,000,000, which is made out of the outer item `count` times the individual inner items: 10 x 100,000; 100 x 10,000 etc. It tells about if `flatMapIterable` prefers long outer sources or long inner sources:

## Conclusion
Reactor core is sometimes better, sometimes worse than RxJava 2. At least they are mostly better than RxJava 1. There seems to be some opportunity for optimizing certain RxJava 2 operators further.
Guia de contribuição
Nenhum guia de contribuição indexado para este repositório
Avaliação
Esta issue ainda não foi avaliada.