Files downloaded in BatchRunner appear to be unnecessarily large
@tamuri is already working on this.
Since Jul 1, 2026.
- Dominant language
- Python
- Stars
- 35
- Forks
- 17
- PR merge metrics
- No merged PRs in 30d
Description
I note that the content of the folder for each run is duplicative and I wonder if there is an opportunity to reduce the size of the downloads, without incurring a heavy additional load for processing locally (which we definitely wouldn't want).
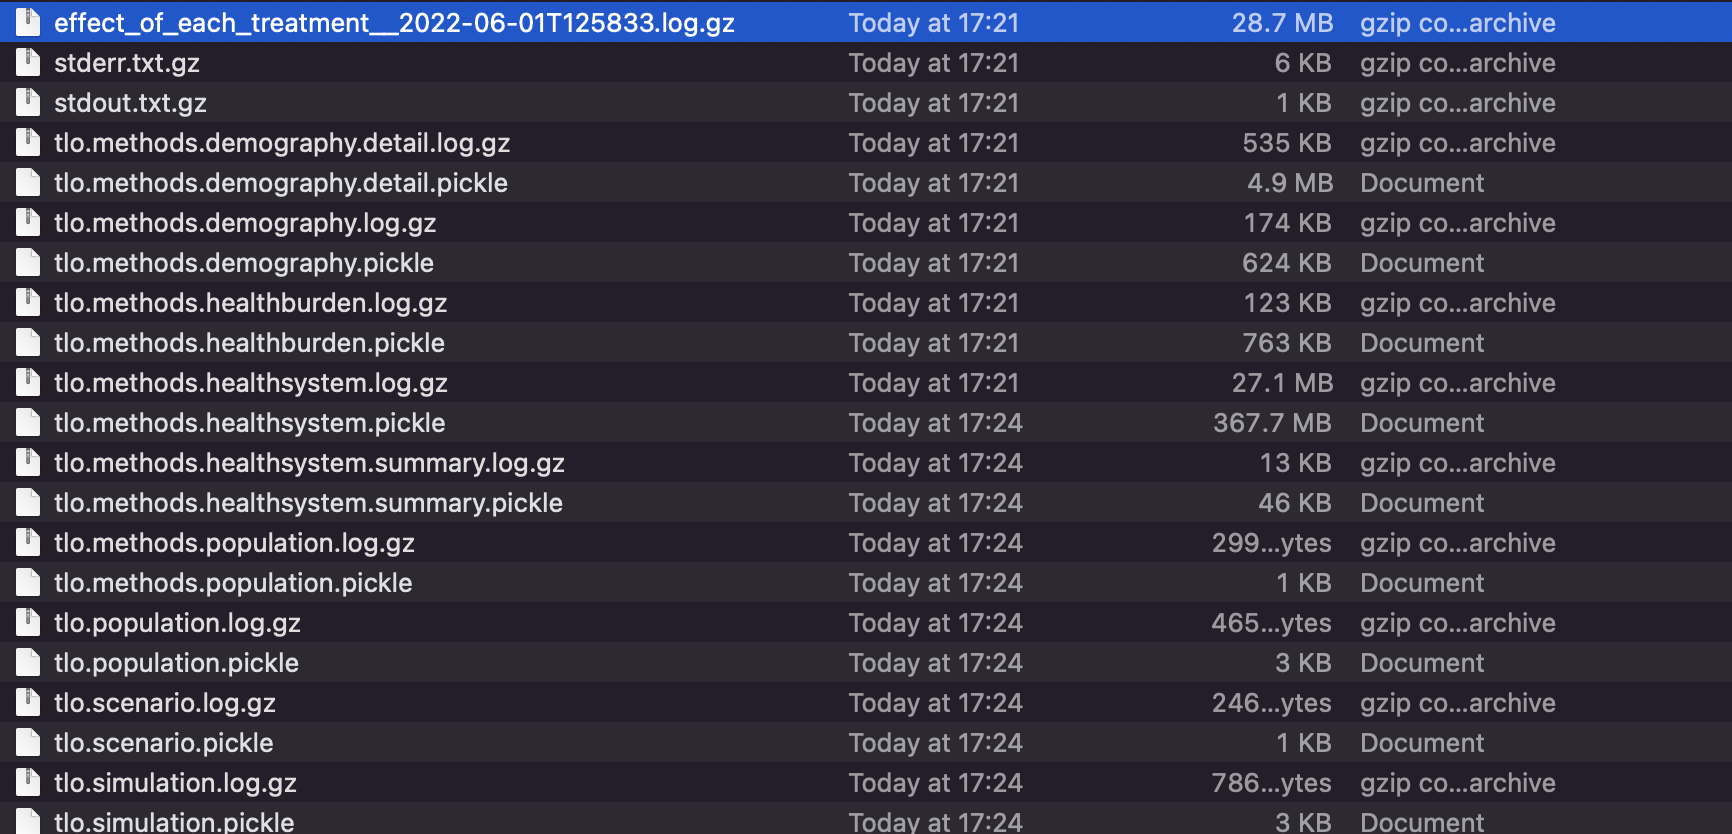
The folder for each run looks something like this (this is specially in the case of scenario_effect_of_each_treatment-2022-05-31T160914Z).
It appears to contain the same information 3 times:
- The complete simulation log (compressed): ~27MB
- The individual log files for each module (compressed): total ~27MB
- The pickles of the results of running
parse_logon each of the above: > 300MB
The result is that what is downloaded is about 10x bigger than what is strictly needed and the biggest files (the pickles) are not compressed.
(NB. I only notice on a set of runs that were very large and had probably too many logs included, and the download has taken many hours. This is probably an edge case, so this may not be a high priority).
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Assessment
This issue has not been assessed yet.