parJoin performance expectations
Open
Nobody has claimed this yet.
- Dominant language
- Scala
- Stars
- 2.5k
- Forks
- 636
- Avg merge
- 2d 4h
- Merged PRs (30d)
- 7
Description
Hi,
I've stumbled on an fs2 performance issue - parJoin is significantly slower than similar operations with Future or IO:
  private def isPrime(n: Long): (Long, Boolean) = n match {
    case 1 => (1, true)
    case n =>
      val sqn = Math.sqrt(n)
      var i = 2
      while (i <= sqn) {
        if (n % i == 0) return (n, false)
        i += 1
      }
      (n, true)
  }

  @tailrec
  private def isMonotonicallyIncreasing(ns: List[Long]): Boolean = ns match {
    case _ :: Nil => true
    case x1 :: x2 :: s if x1 <= x2 => isMonotonicallyIncreasing(x2 :: s)
    case _ => false
  }

  def concurrent7_parallel_future() = {

    val data = (9138000000L to 9139000000L).toList

    implicit val ec = ExecutionContext.fromExecutorService(Executors.newFixedThreadPool(8))

    println("starting futures")
    val start = System.nanoTime()
    val computation = Future.sequence(data.map(x => Future(isPrime(x))(ec)))
    val result = Await.result(computation, Duration.Inf)
    val end = System.nanoTime()
    println(s"ready in ${(end - start) / 1e9d}s ${result.count(_._2)}; monotonic: ${isMonotonicallyIncreasing(result.map(_._1))}")

    ec.shutdown()
  }


  def concurrent8_parallel_execution_io() = {


    val data = (9138000000L to 9139000000L).toList

    implicit val ec = ExecutionContext.fromExecutorService(Executors.newFixedThreadPool(8))
    implicit val cs = IO.contextShift(ec)

    val computation = for {
      fibers <- Traverse[List].sequence(data.map(x => IO(isPrime(x)).start))
      results <- Traverse[List].sequence(fibers.map(_.join))
    } yield results

    println("starting IOs")
    val start = System.nanoTime()
    val result = computation.unsafeRunSync()
    val end = System.nanoTime()
    println(s"ready in ${(end - start) / 1e9d}s, count: ${result.count(_._2)}; monotonic: ${isMonotonicallyIncreasing(result.map(_._1))}")

    ec.shutdown()

  }

  def concurrent9_parallel_execution_fs2() = {

    import fs2.Stream

    val data = Stream.emits(9138000000L to 9139000000L)

    implicit val ec = ExecutionContext.fromExecutorService(Executors.newFixedThreadPool(8))
    implicit val cs = IO.contextShift(ec)

    val computations: Stream[IO, Stream[IO, (Long, Boolean)]] = data.map(x => Stream.eval(IO(isPrime(x)))).covary[IO]
    val computation = computations.parJoin(8).compile.toList

    println("starting fs2")
    val start = System.nanoTime()
    val result = computation.unsafeRunSync()
    val end = System.nanoTime()
    println(s"ready in ${(end - start) / 1e9d}s, count: ${result.count(_._2)}; monotonic: ${isMonotonicallyIncreasing(result.map(_._1))}")

    ec.shutdown()
  }

  concurrent7_parallel_future()
  concurrent8_parallel_execution_io()
  concurrent9_parallel_execution_fs2()
results:
starting futures
ready in 12.813015021s 43573; monotonic: true
starting IOs
ready in 14.489046676s, count: 43573; monotonic: true
starting fs2
ready in 36.539095835s, count: 43573; monotonic: false
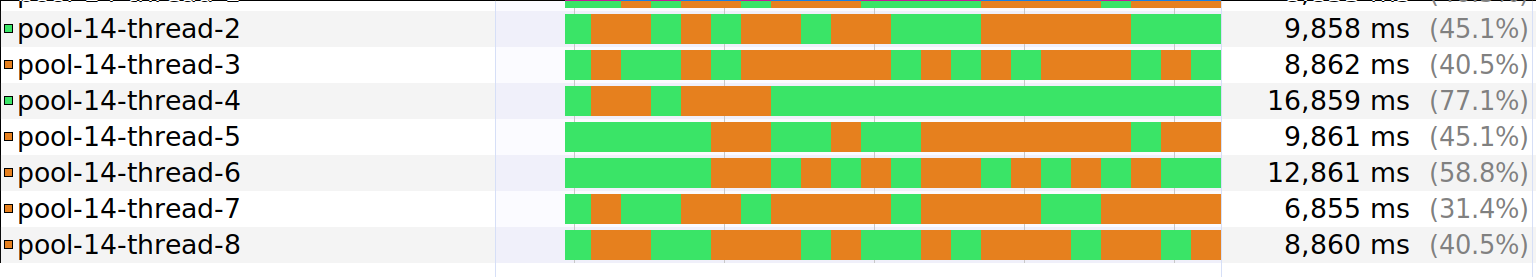
Also, I've noticed a difference how threads are (un)used.
with Futures or IO they are shown as always working in jvisualvm:
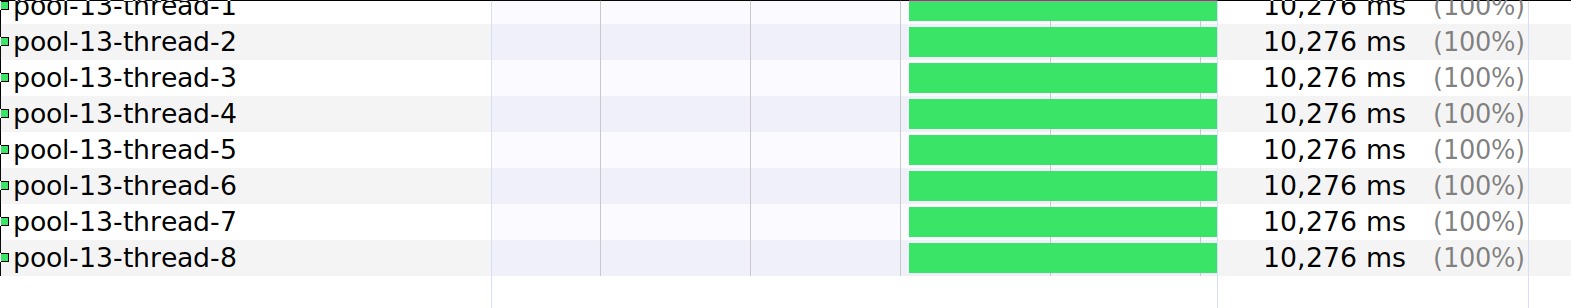
However, fs2 parJoin displays a vastly different view:
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
Start by reproducing the three benchmark methods in the issue, especially the fs2 computation using parJoin(8), and compare its timing and thread usage with the Future and IO versions. Check whether the slower runtime and non-monotonic output are expected for parJoin; done means explaining or correcting the behavior and validating the comparison.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- scala
- Domain
- performance, stream-processing
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Mostly clear
- Newbie friendliness
- 35/100