tensorflow / tensorflow/models
Tensorflow Object Detection Api Instance Segmentation takes up entire RAM (>32 GB)
@pkulzc is already working on this.
Since Jul 10, 2020.
- Dominant language
- Python
- Stars
- 77.7k
- Forks
- 44.8k
- PR merge metrics
- No merged PRs in 30d
Description
System information
- What is the top-level directory of the model you are using: mask_rcnn_resnet50_atrous_coco
- Have I written custom code (as opposed to using a stock example script provided in TensorFlow): No
- OS Platform and Distribution (e.g., Linux Ubuntu 16.04): Linux Ubuntu 16.04
- TensorFlow installed from (source or binary): binary
- TensorFlow version (use command below): 1.5.0
- Bazel version (if compiling from source): N/A
- CUDA/cuDNN version: Cuda 9.0 and CuDNN 7.0
- GPU model and memory: Gtx 1080 (8 GB)
- Exact command to reproduce: python object_detection/train.py --logtostderr --pipeline_config_path=/mask_rcnn_resent50_atrous_coco.config --train_dir=/train
Describe the problem
I'm trying to train instance segmentation model using Tensorflow Object Detection API (Mask RCNN) and have followed the instructions here.
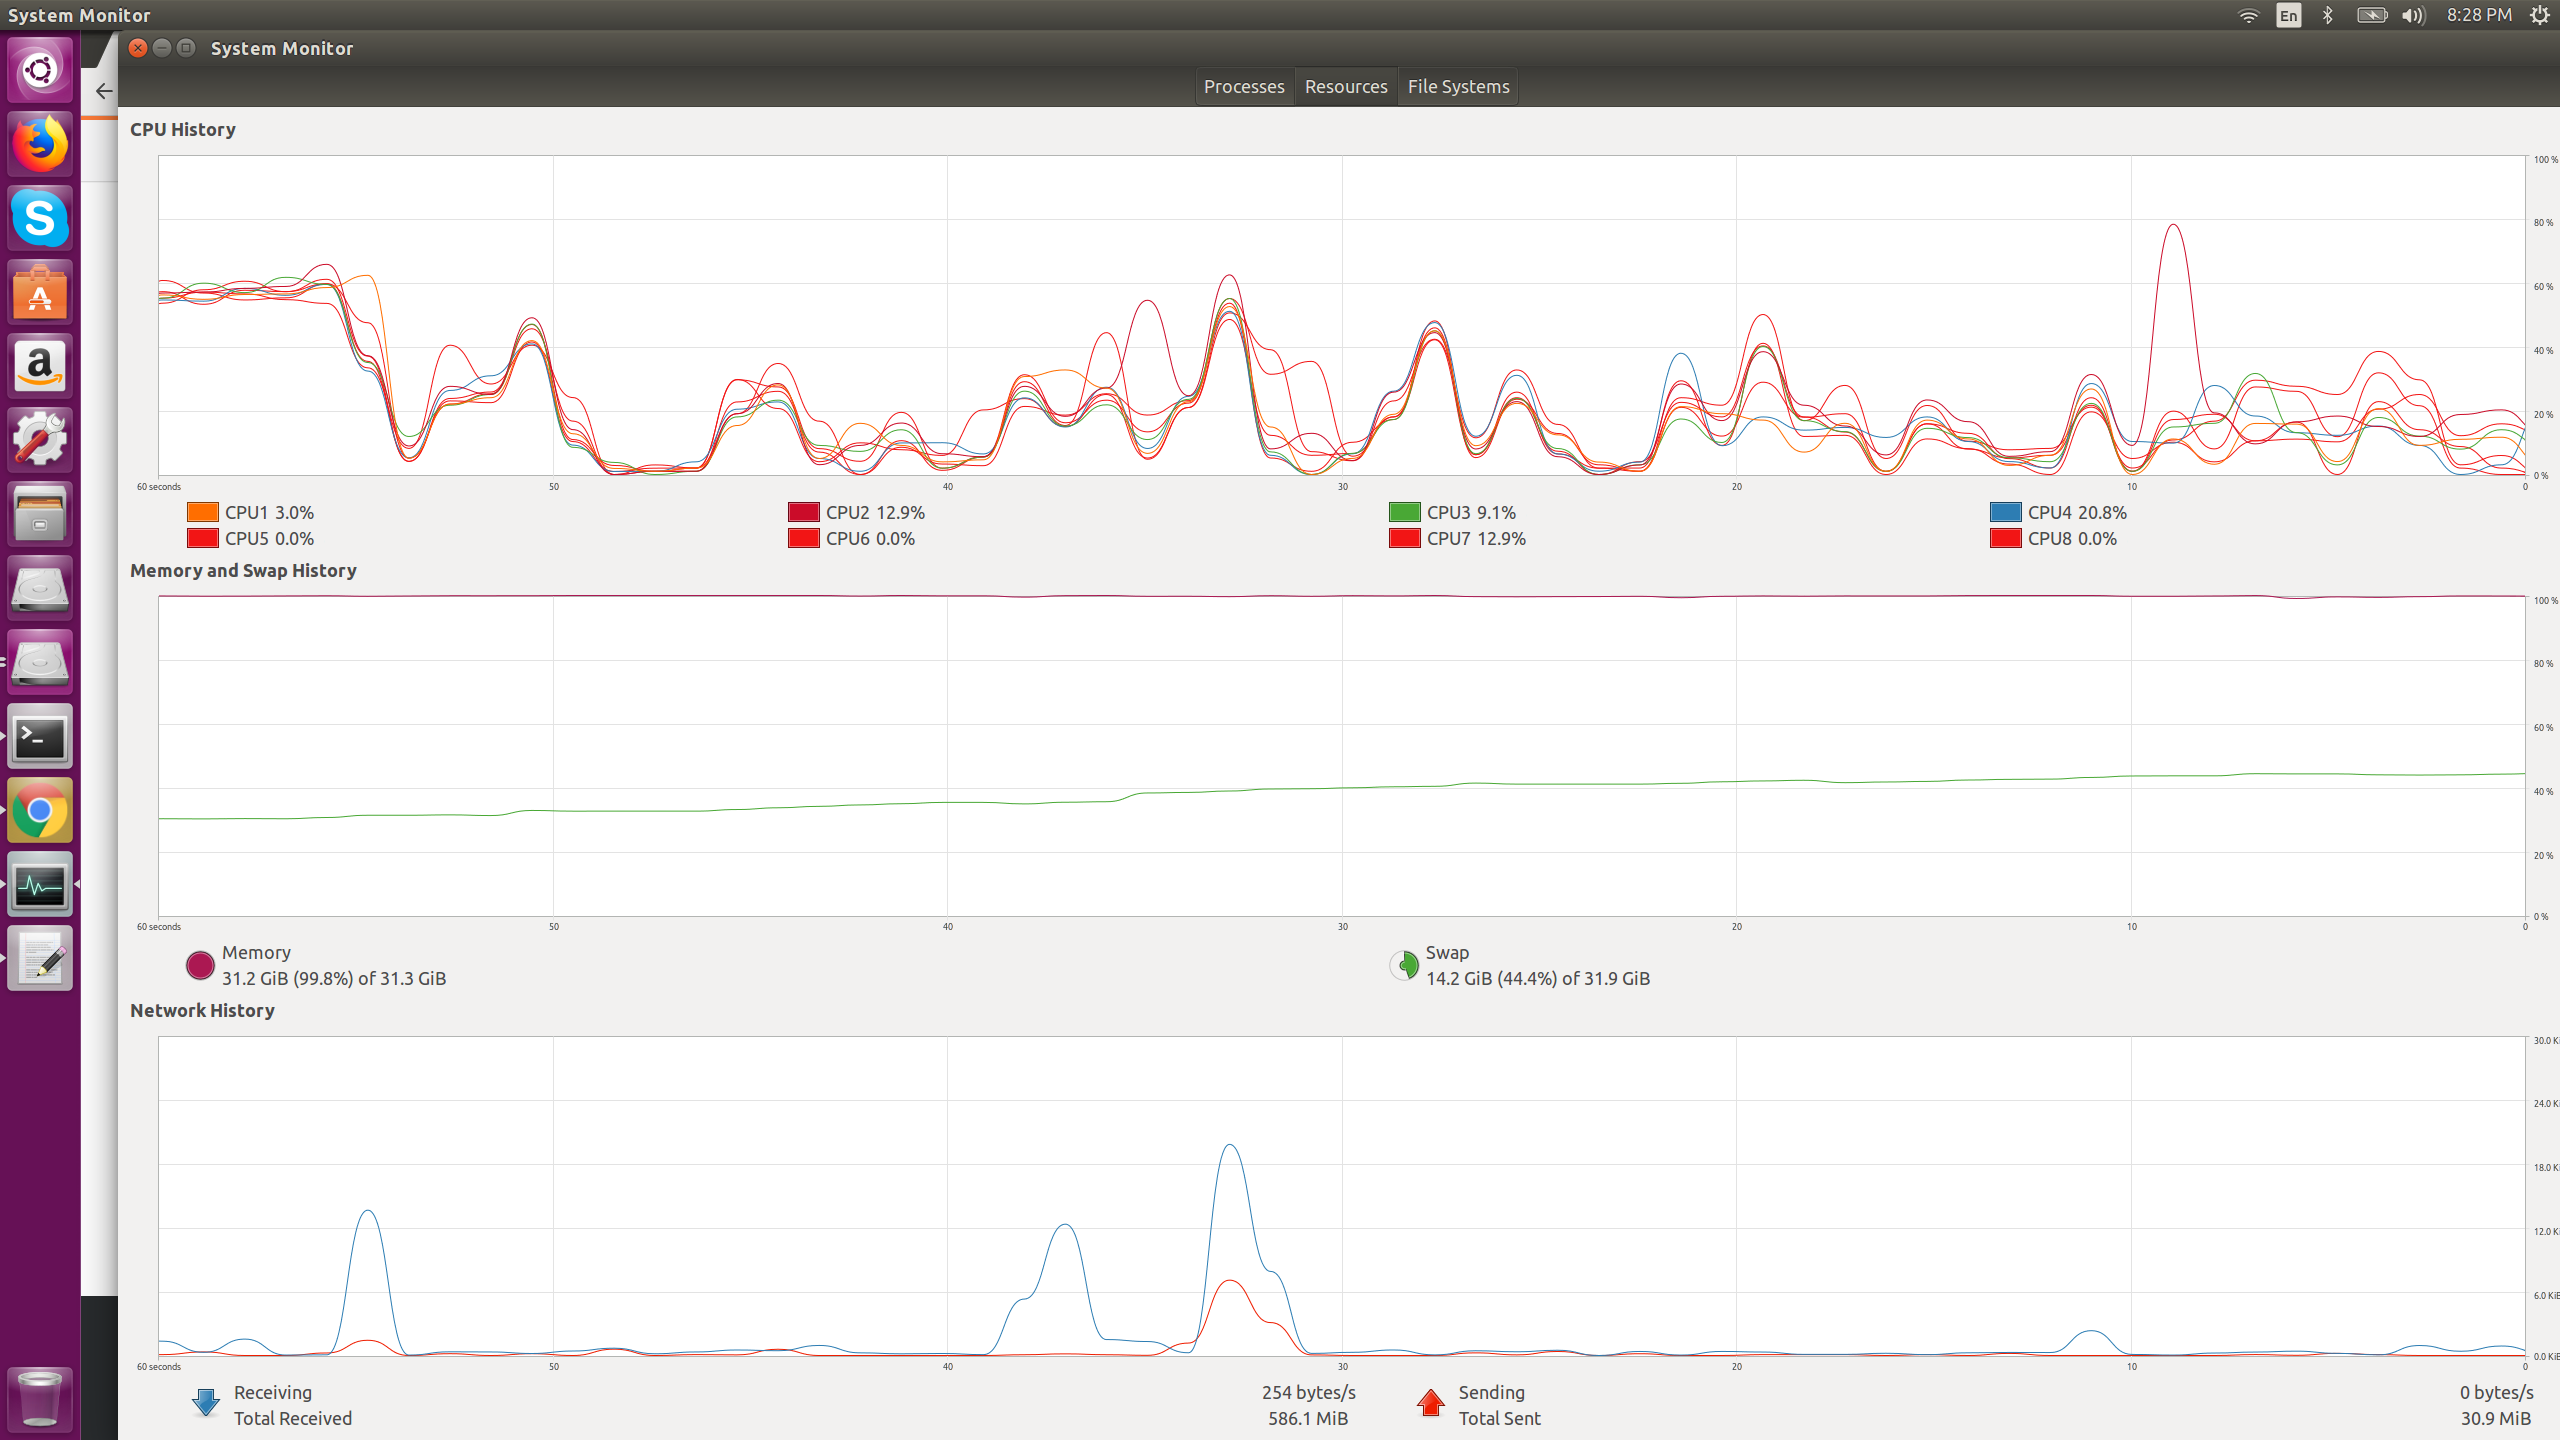
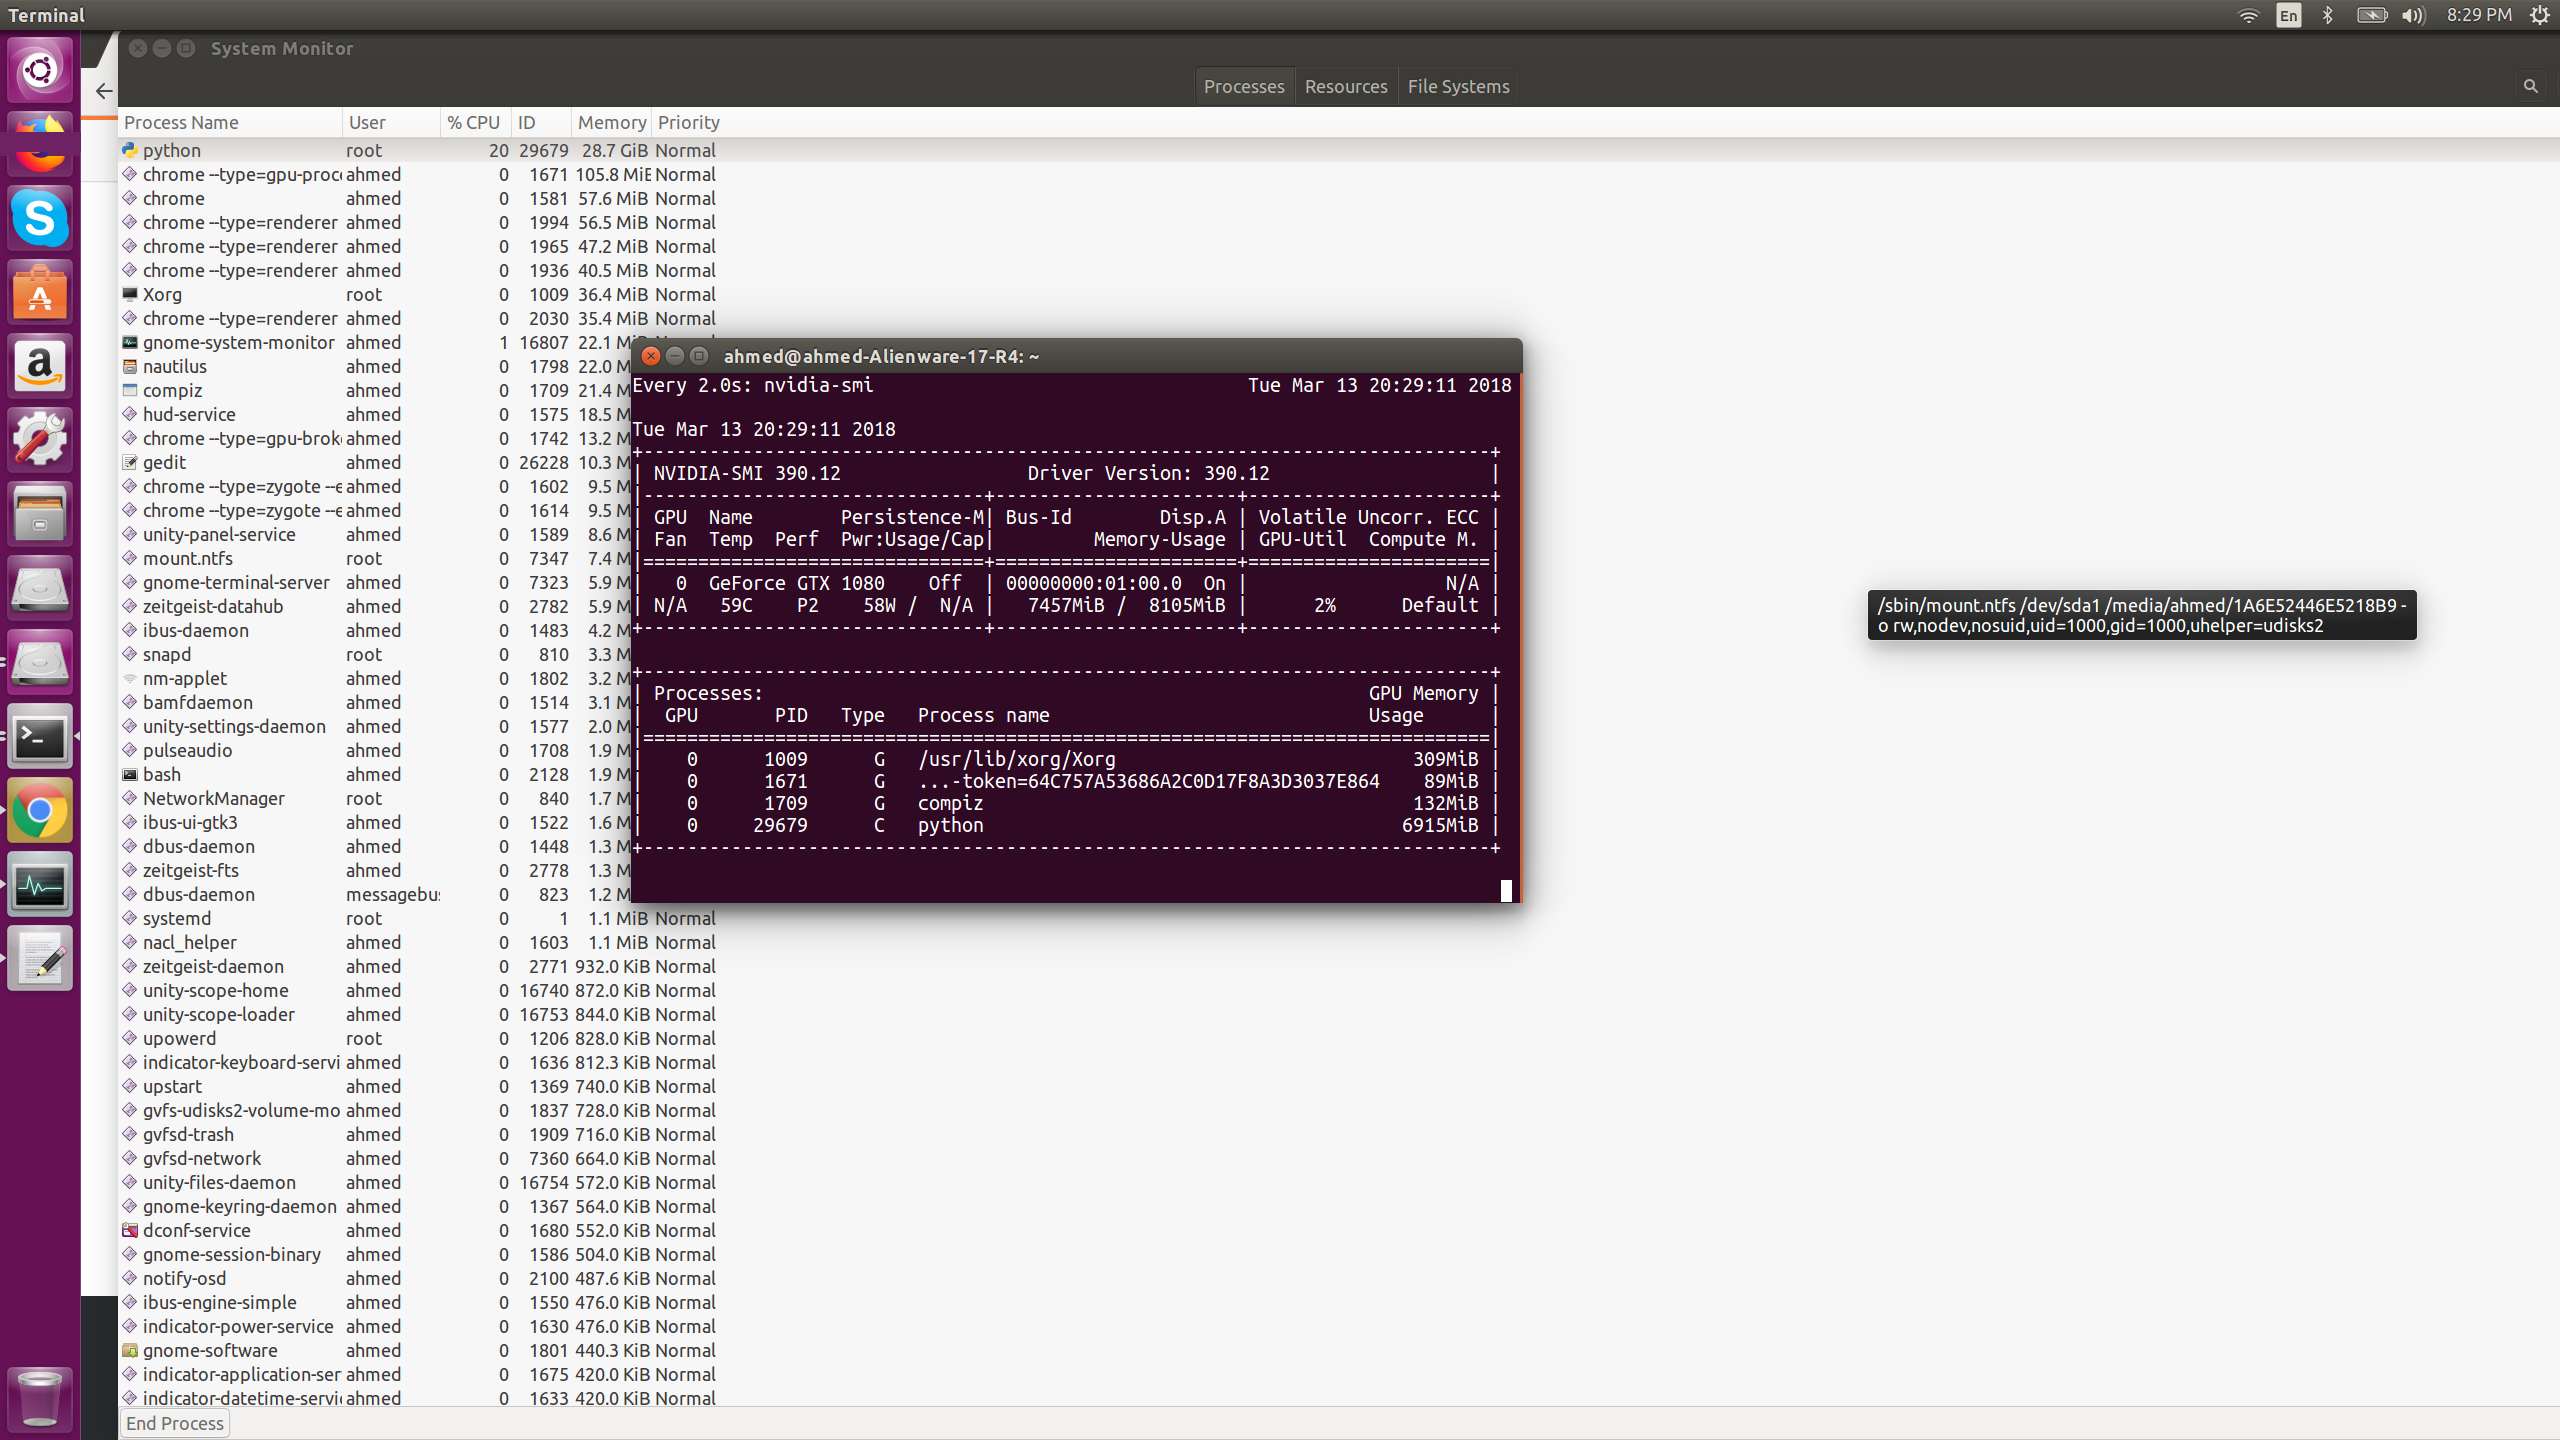
I'm using a pretrained mask_rcnn_resnet50_atrous_coco to initialize weights and adapted this sample config file for the said model. I've created my tfrecord files with masks for training and evaluation sets as per create_coco_tf_record.py. I'm able to run the training script successfully but the problem is, apart from GPU memory, it takes up around 45GB of my RAM. Apart from this everything runs fine and I'm able to finish training upto 10k steps after which it decides it needs more RAM and takes up around 60GB which crashes my system. Same thing happens when I run the evaluation script after training.
I'm not sure why tensorflow needs so much RAM when I'm running the model on GPU. I have only 1 foreground class and around 500 training samples with up to 50 objects/masks per image.
Note: I posted the issue on stackoverflow first and posting here because I didn't get any answer. Here's the question I asked.
Source code / logs
Here's my pipeline config file:
`# Mask R-CNN with Resnet-50 (v1), Atrous version
# Configured for MSCOCO Dataset.
# Users should configure the fine_tune_checkpoint field in the train config as
# well as the label_map_path and input_path fields in the train_input_reader and
# eval_input_reader. Search for "PATH_TO_BE_CONFIGURED" to find the fields that
# should be configured.
model {
faster_rcnn {
num_classes: 1
image_resizer {
keep_aspect_ratio_resizer {
min_dimension: 300
max_dimension: 400
}
}
number_of_stages: 3
feature_extractor {
type: 'faster_rcnn_resnet50'
first_stage_features_stride: 8
}
first_stage_anchor_generator {
grid_anchor_generator {
scales: [0.25, 0.5, 1.0, 2.0]
aspect_ratios: [0.5, 1.0, 2.0]
height_stride: 8
width_stride: 8
}
}
first_stage_atrous_rate: 2
first_stage_box_predictor_conv_hyperparams {
op: CONV
regularizer {
l2_regularizer {
weight: 0.0
}
}
initializer {
truncated_normal_initializer {
stddev: 0.01
}
}
}
first_stage_nms_score_threshold: 0.0
first_stage_nms_iou_threshold: 0.7
first_stage_max_proposals: 300
first_stage_localization_loss_weight: 2.0
first_stage_objectness_loss_weight: 1.0
initial_crop_size: 14
maxpool_kernel_size: 2
maxpool_stride: 2
second_stage_box_predictor {
mask_rcnn_box_predictor {
use_dropout: true
dropout_keep_probability: 0.5
predict_instance_masks: true
mask_height: 33
mask_width: 33
mask_prediction_conv_depth: 0
mask_prediction_num_conv_layers: 4
fc_hyperparams {
op: FC
regularizer {
l2_regularizer {
weight: 0.0
}
}
initializer {
variance_scaling_initializer {
factor: 1.0
uniform: true
mode: FAN_AVG
}
}
}
conv_hyperparams {
op: CONV
regularizer {
l2_regularizer {
weight: 0.0
}
}
initializer {
truncated_normal_initializer {
stddev: 0.01
}
}
}
}
}
second_stage_post_processing {
batch_non_max_suppression {
score_threshold: 0.0
iou_threshold: 0.6
max_detections_per_class: 100
max_total_detections: 300
}
score_converter: SOFTMAX
}
second_stage_localization_loss_weight: 2.0
second_stage_classification_loss_weight: 1.0
second_stage_mask_prediction_loss_weight: 4.0
second_stage_batch_size: 4
}
}
train_config: {
batch_size: 1
optimizer {
momentum_optimizer: {
learning_rate: {
manual_step_learning_rate {
initial_learning_rate: 0.0003
schedule {
step: 0
learning_rate: .0003
}
schedule {
step: 900000
learning_rate: .00003
}
schedule {
step: 1200000
learning_rate: .000003
}
}
}
momentum_optimizer_value: 0.9
}
use_moving_average: false
}
gradient_clipping_by_norm: 10.0
fine_tune_checkpoint: "/media/ahmed/1A6E52446E5218B9/Projects/TF/MaskRCNN/pretrained_models/mask_rcnn_resnet50_atrous_coco_2018_01_28/model.ckpt"
from_detection_checkpoint: true
# Note: The below line limits the training process to 200K steps, which we
# empirically found to be sufficient enough to train the pets dataset. This
# effectively bypasses the learning rate schedule (the learning rate will
# never decay). Remove the below line to train indefinitely.
num_steps: 50000
data_augmentation_options {
random_horizontal_flip {
}
}
}
train_input_reader: {
tf_record_input_reader {
input_path: "/media/ahmed/1A6E52446E5218B9/Projects/TF/MaskRCNN/train_mask.record"
}
label_map_path: "/media/ahmed/1A6E52446E5218B9/Projects/TF/label_map.pbtxt"
load_instance_masks: true
mask_type: PNG_MASKS
}
eval_config: {
num_examples: 200
num_visualizations : 200
# Note: The below line limits the evaluation process to 10 evaluations.
# Remove the below line to evaluate indefinitely.
max_evals: 10
}
eval_input_reader: {
tf_record_input_reader {
input_path: "/media/ahmed/1A6E52446E5218B9/Projects/TF/MaskRCNN/val_mask.record"
}
label_map_path: "/media/ahmed/1A6E52446E5218B9/Projects/TF/label_map.pbtxt"
load_instance_masks: true
mask_type: PNG_MASKS
shuffle: false
num_readers: 1
}`
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Assessment
This issue has not been assessed yet.