Question: Group text by Paragraphs?
Nobody has claimed this yet.
- Dominant language
- PHP
- Stars
- 2.7k
- Forks
- 579
- Avg merge
- 2m
- Merged PRs (30d)
- 1
Description
Hi, I'm trying to group each block/paragraph in a PDF as a oneliner in a textfile. Is this possible?
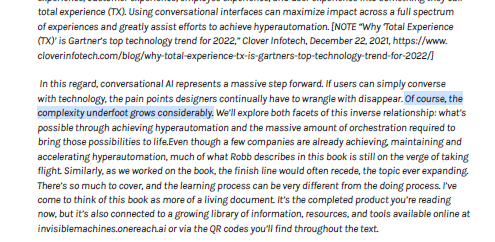
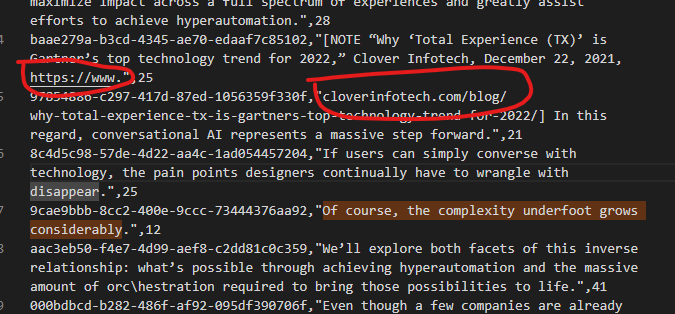
For some reason I get a funky result now on a test PDF, where text inside a paragraph block is exported as newlines, or even broken down in the middle (as with the URL).
Also, it is it possible to Skip parts? I'd love to not have the talke of contents as I want to use the scanned docs like in a Python vector seach. Hopefully there's some tips that arent in the docs (or maybe a link to extended docs if/where available?).
See image below:
I used this code:
            $parser        = new Parser();
            $pdf           = $parser->parseFile($file_info);
            $pdf_contents = $pdf->getText();
            $file_contents = preg_replace(array("/(\r\n|\r|\n)/", "/\s+/"), array(" ", " "), $pdf_contents);
            $fileAsArray   = array($file_contents);
Setting text by Chapters would be even cooler, so we can get CSVs with
1 Chatper name, Content
2 ..., ...
3 ..., ...
Thanks.
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
Start with the Parser::parseFile() and getText() entry points shown in the report, then review the available documentation for paragraph grouping, skipped regions, and chapter extraction. Done criteria are not defined: the project would first need to specify how paragraphs and chapters are detected and how table-of-contents content is excluded.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- php
- Domain
- backend
- Issue type
- Feature
- Difficulty
- 5/5
- Estimated time
- Over a week
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 20/100