Is there preferences, that detect this text as separate fragments?
Open
Nobody has claimed this yet.
parsing fail
question
- Dominant language
- PHP
- Stars
- 2.7k
- Forks
- 579
- Avg merge
- 2m
- Merged PRs (30d)
- 1
Description
http://www.eurasiancommission.org/ru/act/trade/catr/ett/Documents/ru.38_2022.pdf on 4th page
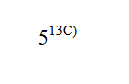
This great lib parse this fragment like 513C), but I need to parse it with some delimiter, like "5 13c)" or something like this.
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
Start with page 4 of the linked PDF and compare the extracted “513C)” fragment with the attached image. Investigate whether the parser exposes preferences for separating adjacent text fragments; done means the requested text is extracted with a meaningful delimiter without breaking other PDF text.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- php
- Domain
- backend
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 25/100