selfteaching / selfteaching/selfteaching-python-camp
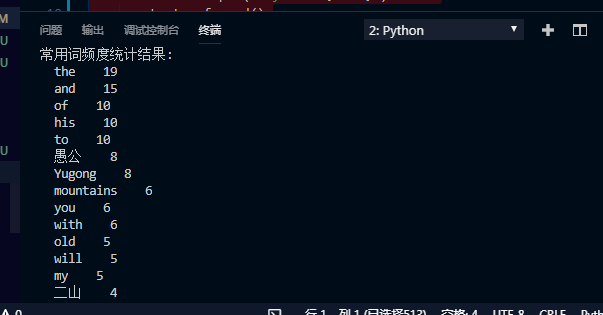
Day10 用jieba统计中文词频为什么英文也一起出来了
Open
Nobody has claimed this yet.
- Dominant language
- Python
- Stars
- 151
- Forks
- 875
- PR merge metrics
- No merged PRs in 30d
Description
import os, codecs
import jieba
from collections import Counter

def stats_text_cn(text):
    """统计参数中每个中文汉字出现的次数,最后返回一个按字频降序排列的数组"""
    seg_list = jieba.cut(text)
    c = Counter()
    for x in seg_list:
        if len(x)>1 and x != '\r\n':
            c[x] += 1
    print('常用词频度统计结果:')
    for (k,v) in c.most_common(100):
        print('%s%s %s  %d' % ('  ', k, ' ', v))

if __name__ == '__main__':
    with codecs.open('day7.txt', 'r', ) as f:
        text = f.read()

stats_text_cn(text)
Contributor guide
No contributing guide indexed for this repository
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
Start with stats_text_cn in the issue and inspect the contents of day7.txt alongside the tokens returned by jieba.cut(text). Reproduce the output and determine what filtering behavior is expected for the Chinese word-frequency report; done means the reported entries match that expectation.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- python
- Domain
- data
- Issue type
- Bug
- Difficulty
- 2/5
- Estimated time
- 1-3 hours
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 35/100