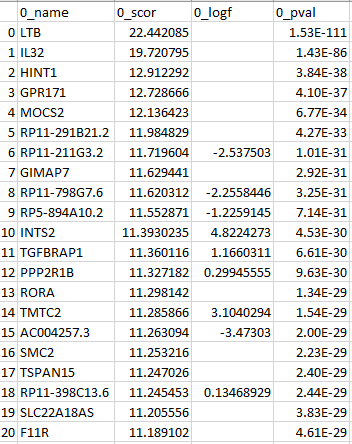
logFC becomes negative and disappear for the top ranked genes when use_raw=False
Nobody has claimed this yet.
- Dominant language
- Python
- Stars
- 2.6k
- Forks
- 779
- Avg merge
- 1d 4h
- Merged PRs (30d)
- 27
Description
- [✔ ] I have checked that this issue has not already been reported.
- [✔ ] I have confirmed this bug exists on the latest version of scanpy.
- (optional) I have confirmed this bug exists on the master branch of scanpy.
Note: Please read this guide detailing how to provide the necessary information for us to reproduce your bug.
Minimal code sample (that we can copy&paste without having any data)
# Your code here
```sc.tl.rank_genes_groups(adata, 'leiden', method='wilcoxon', use_raw=False)

```pytb
[Paste the error output produced by the above code here]
Versions
scanpy==1.8.2 anndata==0.7.8 umap==0.5.2 numpy==1.20.3 scipy==1.7.2 pandas==1.3.4 scikit-learn==1.0.1 statsmodels==0.13.1 python-igraph==0.9.8 pynndescent==0.5.5
Hello Scanpy,
Because the scRNA-seq data usually have mitochondrial gene contamination, it's reasonable to regress out mito genes by sc.pp.regress_out(adata, ['total_counts', 'pct_counts_mt']) and do scaling, and use this 'clear' data for determining the marker genes of each cluster by setting use_raw=False in sc.tl.rank_genes_groups().
However, I found that
-
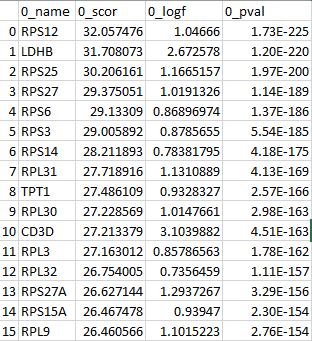
if using unregressed data by sc.tl.rank_genes_groups(adata, 'leiden', method='wilcoxon', use_raw=True), the top marker genes have positive logFC, which is reasonable because these are top upregulated genes helping us to determine the annotations of clusters.
-
the weird thing is, if using regressed data by sc.tl.rank_genes_groups(adata, 'leiden', method='wilcoxon', use_raw=False), the logFC of top marker genes will become negative and even disappear, which means the downregulated genes and genes with unknown logFC (why no logFC?) becomes the marker genes, which doesn't make sense.

This bug comes from the official jupyter notebook of pbmc by setting use_raw=False in sc.tl.rank_genes_groups().
Could you please help us to solve this issue?
Thanks!
Best,
YJ
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
Start at sc.tl.rank_genes_groups(...), comparing use_raw=True and use_raw=False with the versions listed in the report. The issue provides no data, failing test, or source file, so first establish a reproducible example for the negative or missing logFC behavior. Done means the ranking and logFC output are correct for regressed data.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- python
- Domain
- bioinformatics
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 25/100