Profiler doesn't capture PyTorch op events in multithreads
Open
Nobody has claimed this yet.
enhancement
- Dominant language
- C++
- Stars
- 992
- Forks
- 270
- Avg merge
- 2d 11h
- Merged PRs (30d)
- 12
Description
Hi, as the title said. Here's the code I used to reproduce the bug on 2 GPUs. In the trace file we can only see cudaKernelLaunch and the GPU kernel calls, but none of the add and mul ops are captured. Anyone could help?
cc: @louisfeng
import threading
import torch

def torch_adds(id):
    d = torch.device("cuda:" + str(id))
    for _ in range(100):
        a = torch.rand(1).to(d, non_blocking=True)
        b = torch.rand(1).to(d, non_blocking=True)
        c = torch.add(a, b)
    return c
def torch_mul(id):
    d = torch.device("cuda:" + str(id))
    for _ in range(100):
        a = torch.rand(1).to(d, non_blocking=True)
        b = torch.rand(1).to(d, non_blocking=True)
        c = torch.mul(a, b)
    return c

id = 2
with torch.autograd.profiler.profile(use_cuda=True, use_kineto=True) as prof:
    t1 = threading.Thread(target=torch_adds, args=(0,))
    t2 = threading.Thread(target=torch_mul, args=(1,))
    t1.start() ; t2.start()
    t1.join() ; t2.join()

with open("{}.prof".format(id), "w") as prof_f:
    prof_f.write(prof.key_averages().table(sort_by="self_cpu_time_total"))
prof.export_chrome_trace("{}.json".format(id))
Trace:
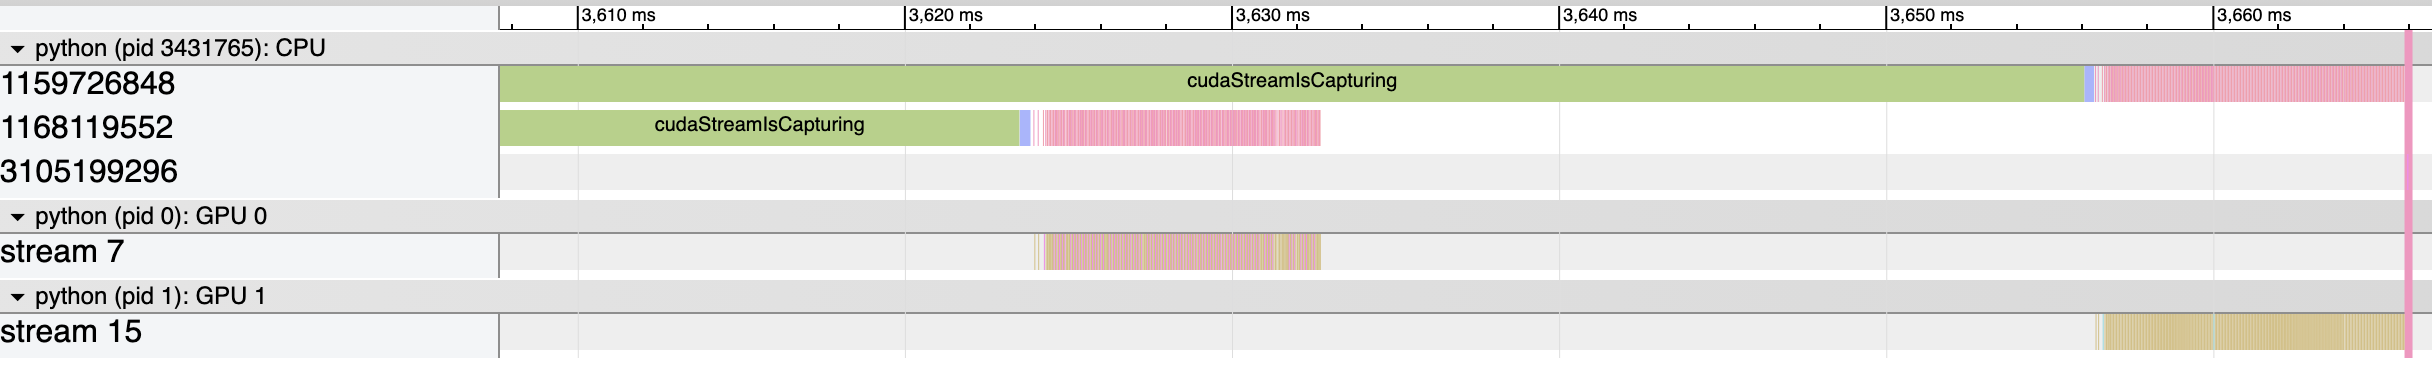
Zoomed in:

Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
Start with the provided Python reproducer, especially torch.autograd.profiler.profile with use_cuda=True and use_kineto=True, and inspect the exported Chrome trace. Compare the multithreaded trace with the expected add and mul operations; done means those PyTorch op events are captured alongside the CUDA kernel events.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- cpp, python
- Domain
- observability-sre, performance
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 35/100