pingcap / pingcap/tidb-operator
There are too many DNS queries if a TiKV pod can't started
Nobody has claimed this yet.
- Dominant language
- Go
- Stars
- 1.3k
- Forks
- 540
- Avg merge
- 3d 2h
- Merged PRs (30d)
- 18
Description
I deployed a tidb cluster with 3xpd, 3xtikv and 2 tidb. We create 1000 tables.
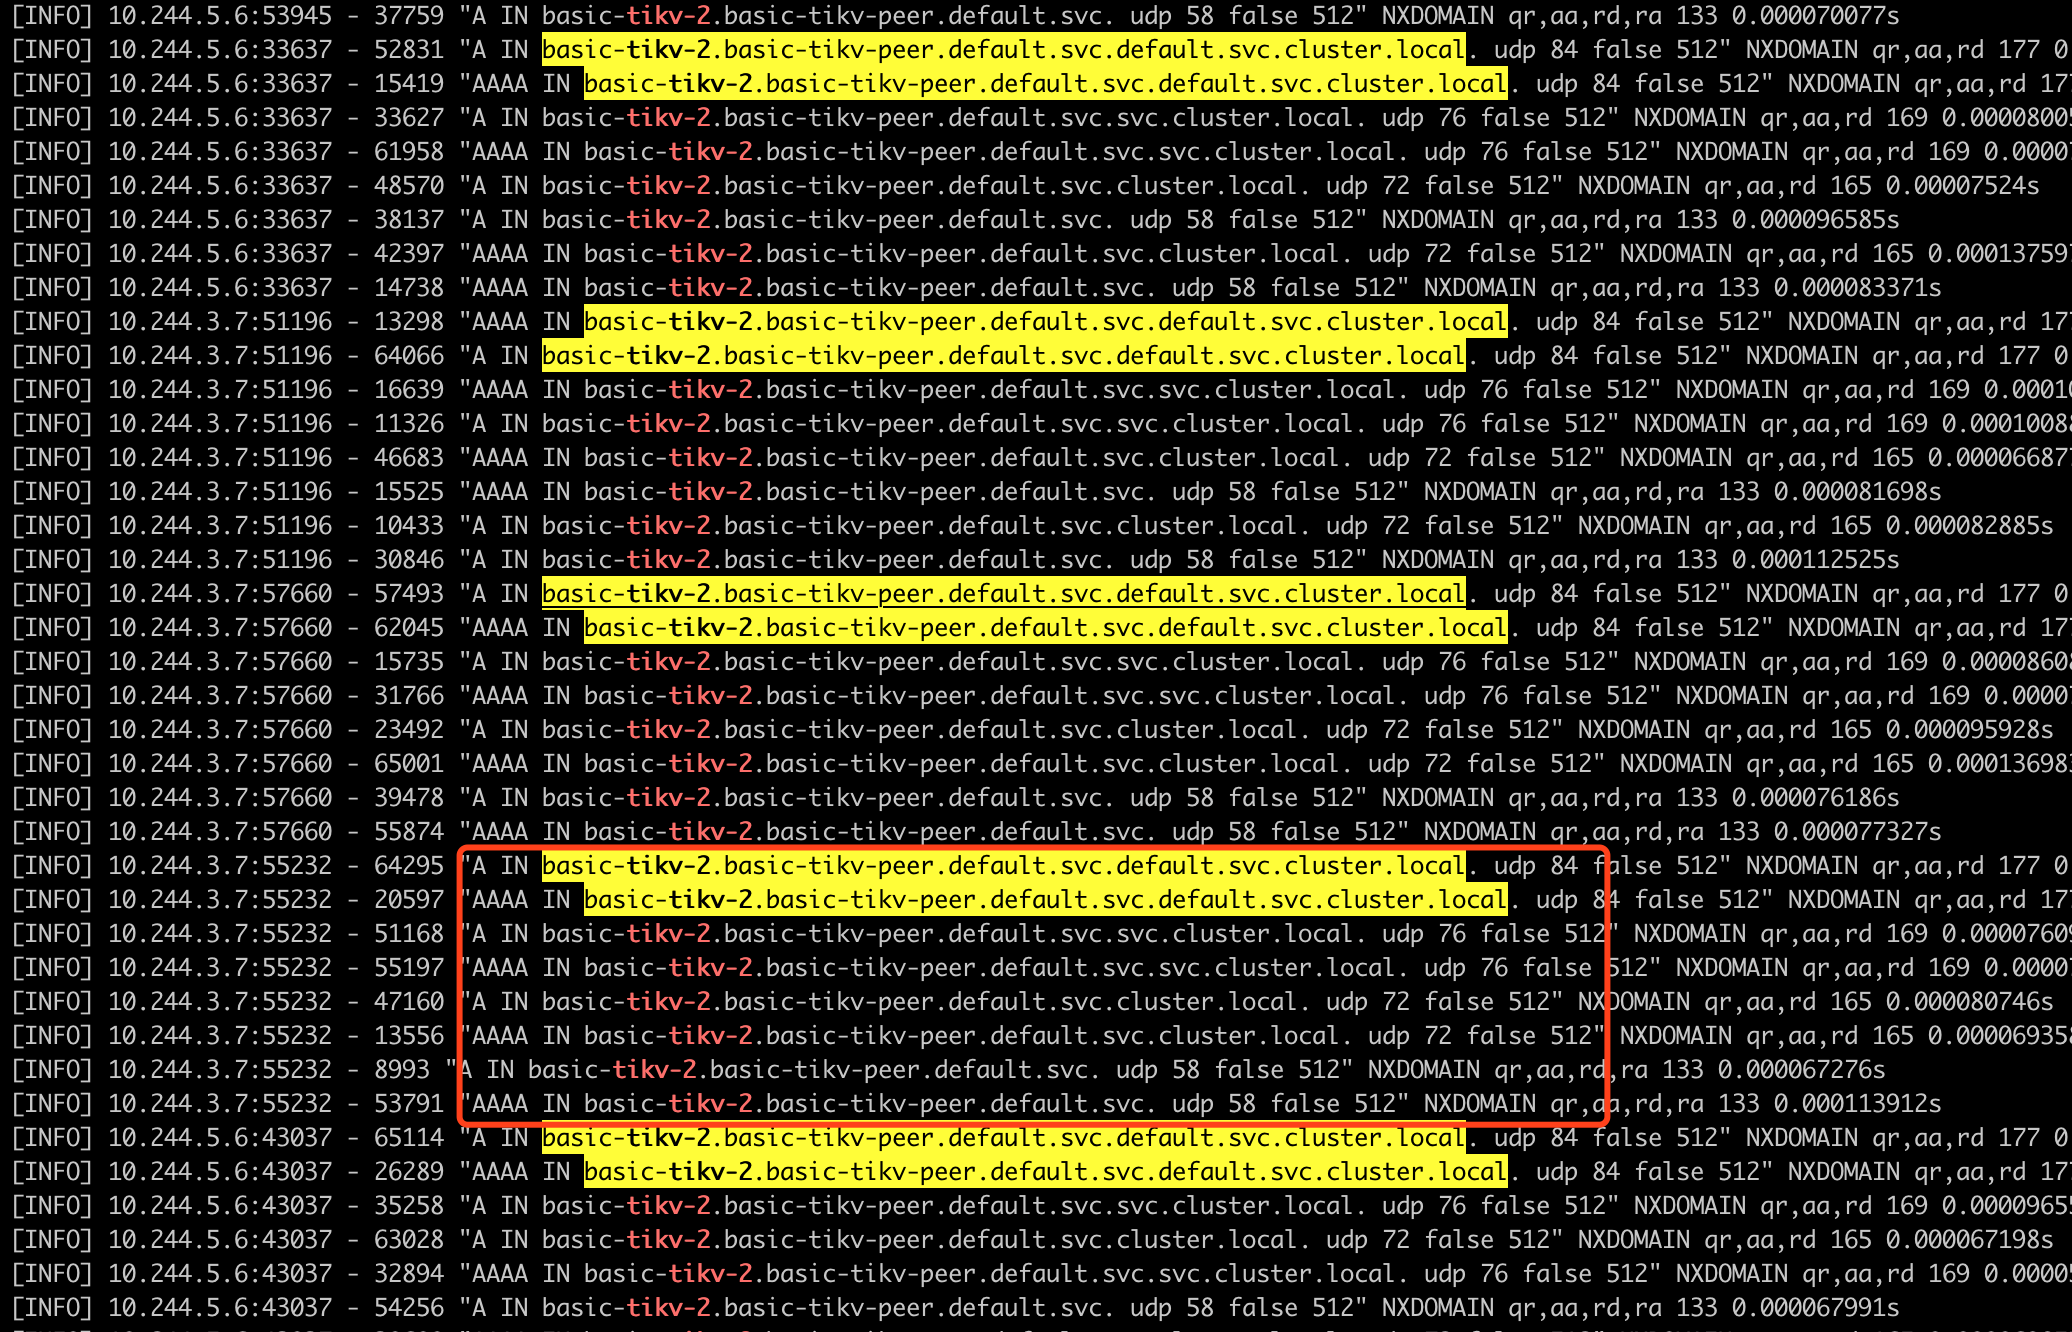
When i killed a tikv pod, other tikv pods will query tikv-2 many times, for example, 100 queries per second. Two tikv pods as 200 queries per second.
Because the /etc/resolv.conf file has search section:
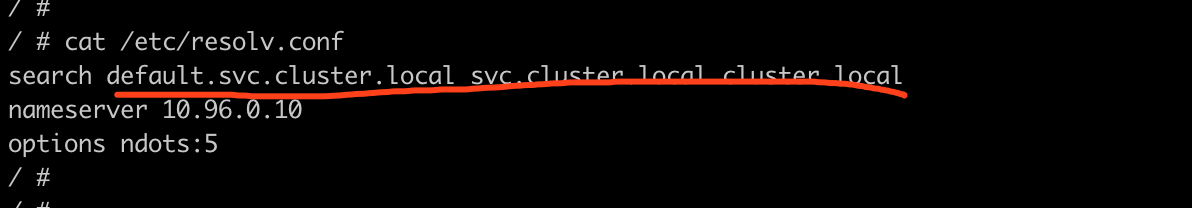
So a failed dns query will be 8 times, so the total DNS queries will be 8 x 200 = 1600 queries per second.
Well, I think there are two methods to optimize:
- For TiDB Operator, let’s see if we can reduce(or remove) the
searchitem in the /etc/resolv.conf file so that the enlargement can be removed; - TiKV should optimize the backoff mechanism to reduce the DNS queries.
What do you think? @cofyc @DanielZhangQD @lichunzhu
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
Start by reproducing the reported 3 PD, 3 TiKV, 2 TiDB deployment with 1,000 tables, then inspect /etc/resolv.conf and DNS traffic after a TiKV pod is killed. Compare whether the excessive queries originate in TiDB Operator's Kubernetes configuration or TiKV's backoff behavior; the work is done when the chosen cause and an objectively reduced query rate are verified.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- go, kubernetes
- Domain
- infrastructure, networking
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 30/100