opensearch-project / opensearch-project/data-prepper
[BUG] Performance with one data-prepper instance is better than with two
@dlvenable is already working on this.
Since Jan 13, 2023.
- Dominant language
- Java
- Stars
- 374
- Forks
- 354
- Avg merge
- 3d 18h
- Merged PRs (30d)
- 8
Description
Describe the bug
When sending load to data-prepper (2 instances) we can see a huge performance difference compared to if we only would have 1 instance of data-prepper with the same configuration (but without the Core Peer Forwarder).
To Reproduce
Steps to reproduce the behavior:
- Run data-prepper with the following configuration:
Note: We are running data-prepper within Kubernetes and using a headless service for the peer forwarder. Like documented here in the examples/dev/k8s folder.
data-prepper-config.yaml:
     ssl: false
     peer_forwarder:
       ssl: false
       discovery_mode: "dns"
       domain_name: "data-prepper-headless"
       buffer_size: 512
       batch_size: 48
entry-pipeline:
  workers: 8
  delay: "100"
  source:
    otel_trace_source:
      ssl: false
  buffer:
    bounded_blocking:
      buffer_size: 512
      batch_size: 8
  processor:
  sink:
    - pipeline:
        name: "raw-pipeline"
    - pipeline:
        name: "service-map-pipeline"
raw-pipeline:
  workers: 8
  buffer:
    bounded_blocking:
      buffer_size: 512
      batch_size: 64
  source:
    pipeline:
      name: "entry-pipeline"
  processor:
    - otel_trace_raw:
  sink:
    - opensearch:
        hosts: [ <opensearch endpoint> ]
        insecure: true
        username: <user>
        password: <pwd>
        index_type: trace-analytics-raw
service-map-pipeline:
  workers: 8
  delay: "100"
  buffer:
    bounded_blocking:
      buffer_size: 512
      batch_size: 8
  source:
    pipeline:
      name: "entry-pipeline"
  processor:
    - service_map_stateful:
  sink:
    - opensearch:
        hosts: [<opensearch endpoint>]
        insecure: true
        username: <user>
        password: <pwd>
        index_type: trace-analytics-service-map
- Prepare an otel-collector docker image, e.g. docker pull otel/opentelemetry-collector:0.67.0 and point it to the DataPrepper instance using the following configuration:
receivers:
  otlp:
    protocols:
      grpc:
      http:
        cors:
          allowed_origins:
            - "*"

processors:
  batch:
    send_batch_size: 50
    timeout: 1s

exporters:
  logging:
    logLevel: debug
  otlp/traces:
    endpoint: "<DataPrepper Endpoint>"
    tls:
      insecure_skip_verify: true
service:
  pipelines:
    traces:
      receivers: [otlp]
      processors: [batch]
      exporters: [logging, otlp/traces]
-
Run the otel-collector:
docker run -v "${PWD}/otelcol-config-sample.yaml":/otelcol-config-sample.yaml -p 4318:4318 otel/opentelemetry-collector:0.67.0 --config otelcol-config-sample.yaml -
Get tracegen as simple load generation tool:
go install github.com/open-telemetry/opentelemetry-collector-contrib/cmd/tracegen@latest -
Run tracegen to send trace spans to the otel-collector (here 500 requests per second, each request having two spans). The otel-collector will export those to data-prepper.
tracegen -otlp-http -otlp-endpoint localhost:4318 -otlp-insecure -duration 300s -rate 500
After a few seconds I can see logs like the following:
2023-01-13T16:40:04,634 [pool-7-thread-6] ERROR org.opensearch.dataprepper.plugins.source.oteltrace.OTelTraceGrpcService - Failed to write the request content [
<here are all the spans, too many to paste them>
] due to:
java.util.concurrent.TimeoutException: Pipeline [entry-pipeline] - Buffer does not have enough capacity left for the size of records: 512, timed out waiting for slots.
	at org.opensearch.dataprepper.plugins.buffer.blockingbuffer.BlockingBuffer.doWriteAll(BlockingBuffer.java:123) ~[blocking-buffer-2.0.1.jar:?]
	at org.opensearch.dataprepper.model.buffer.AbstractBuffer.writeAll(AbstractBuffer.java:97) ~[data-prepper-api-2.0.1.jar:?]
	at org.opensearch.dataprepper.plugins.MultiBufferDecorator.writeAll(MultiBufferDecorator.java:39) ~[data-prepper-core-2.0.1.jar:?]
	at org.opensearch.dataprepper.plugins.source.oteltrace.OTelTraceGrpcService.processRequest(OTelTraceGrpcService.java:106) ~[otel-trace-source-2.0.1.jar:?]
	at org.opensearch.dataprepper.plugins.source.oteltrace.OTelTraceGrpcService.lambda$export$0(OTelTraceGrpcService.java:78) ~[otel-trace-source-2.0.1.jar:?]
	at io.micrometer.core.instrument.composite.CompositeTimer.record(CompositeTimer.java:89) ~[micrometer-core-1.9.4.jar:1.9.4]
	at org.opensearch.dataprepper.plugins.source.oteltrace.OTelTraceGrpcService.export(OTelTraceGrpcService.java:78) ~[otel-trace-source-2.0.1.jar:?]
	at io.opentelemetry.proto.collector.trace.v1.TraceServiceGrpc$MethodHandlers.invoke(TraceServiceGrpc.java:246) ~[opentelemetry-proto-1.7.1-alpha.jar:1.7.1]
	at io.grpc.stub.ServerCalls$UnaryServerCallHandler$UnaryServerCallListener.onHalfClose(ServerCalls.java:182) ~[grpc-stub-1.49.0.jar:1.49.0]
	at com.linecorp.armeria.server.grpc.AbstractServerCall.invokeOnMessage(AbstractServerCall.java:374) ~[armeria-grpc-1.19.0.jar:?]
	at com.linecorp.armeria.server.grpc.AbstractServerCall.lambda$onRequestMessage$2(AbstractServerCall.java:338) ~[armeria-grpc-1.19.0.jar:?]
	at com.linecorp.armeria.internal.shaded.guava.util.concurrent.SequentialExecutor$1.run(SequentialExecutor.java:123) ~[armeria-1.19.0.jar:?]
	at com.linecorp.armeria.internal.shaded.guava.util.concurrent.SequentialExecutor$QueueWorker.workOnQueue(SequentialExecutor.java:235) ~[armeria-1.19.0.jar:?]
	at com.linecorp.armeria.internal.shaded.guava.util.concurrent.SequentialExecutor$QueueWorker.run(SequentialExecutor.java:180) ~[armeria-1.19.0.jar:?]
	at com.linecorp.armeria.common.RequestContext.lambda$makeContextAware$3(RequestContext.java:566) ~[armeria-1.19.0.jar:?]
	at java.util.concurrent.Executors$RunnableAdapter.call(Executors.java:539) ~[?:?]
	at java.util.concurrent.FutureTask.run(FutureTask.java:264) ~[?:?]
	at java.util.concurrent.ScheduledThreadPoolExecutor$ScheduledFutureTask.run(ScheduledThreadPoolExecutor.java:304) ~[?:?]
	at java.util.concurrent.ThreadPoolExecutor.runWorker(ThreadPoolExecutor.java:1136) ~[?:?]
	at java.util.concurrent.ThreadPoolExecutor$Worker.run(ThreadPoolExecutor.java:635) ~[?:?]
	at java.lang.Thread.run(Thread.java:833) ~[?:?]
Expected behavior
I expect that increasing the instances of data-prepper will improve the performance and not make it worse.
Screenshots
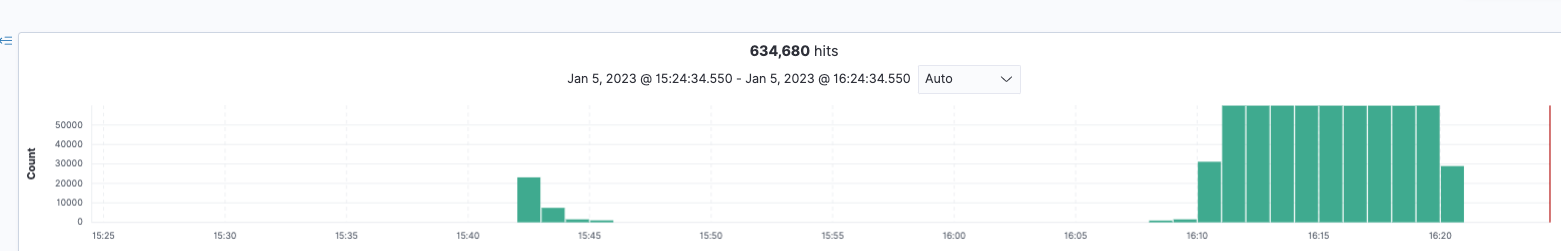
In this screenshot we can see how many spans got ingested into OpenSearch. On the left we have the load generation for 2 data-prepper instances and on the right for 1 instance. On the right we can see that no traces are lost and on the left only a few will get through.
Environment (please complete the following information):
- Tested with data-prepper 2.0.1. Having the same configuration, for 1.5.0 it could support the same load rate without problems.
Additional context
The pipeline definition uses values for the buffer and batch sizes and workers like documented here. We noticed that the default sizes for buffer and batch size (512 & 8) changed with data-prepper version 2.0 to 12800 & 200. This also helps to deal with this issue and data-prepper can handle much more load this way. Also, by increasing the buffer and batch size for the peer forwarder we can improve the performance so that it will be close to look like the result when we just are using 1 data-prepper instance.
However, it still seems to be better when just having one instance compared to having two. The "outdated" values for the buffer and batch size are used here to show that we get a worse performance for two data-prepper instances.
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Assessment
This issue has not been assessed yet.