networkdb stuck thinking healthy nodes are failed or left
Nobody has claimed this yet.
- Dominant language
- Go
- Stars
- 2.2k
- Forks
- 875
- PR merge metrics
- No merged PRs in 30d
Description
On a 600-node test cluster, we sometimes see networkdb getting stuck thinking that some nodes are failed or left, even when its own memberlist thinks the same nodes are up.
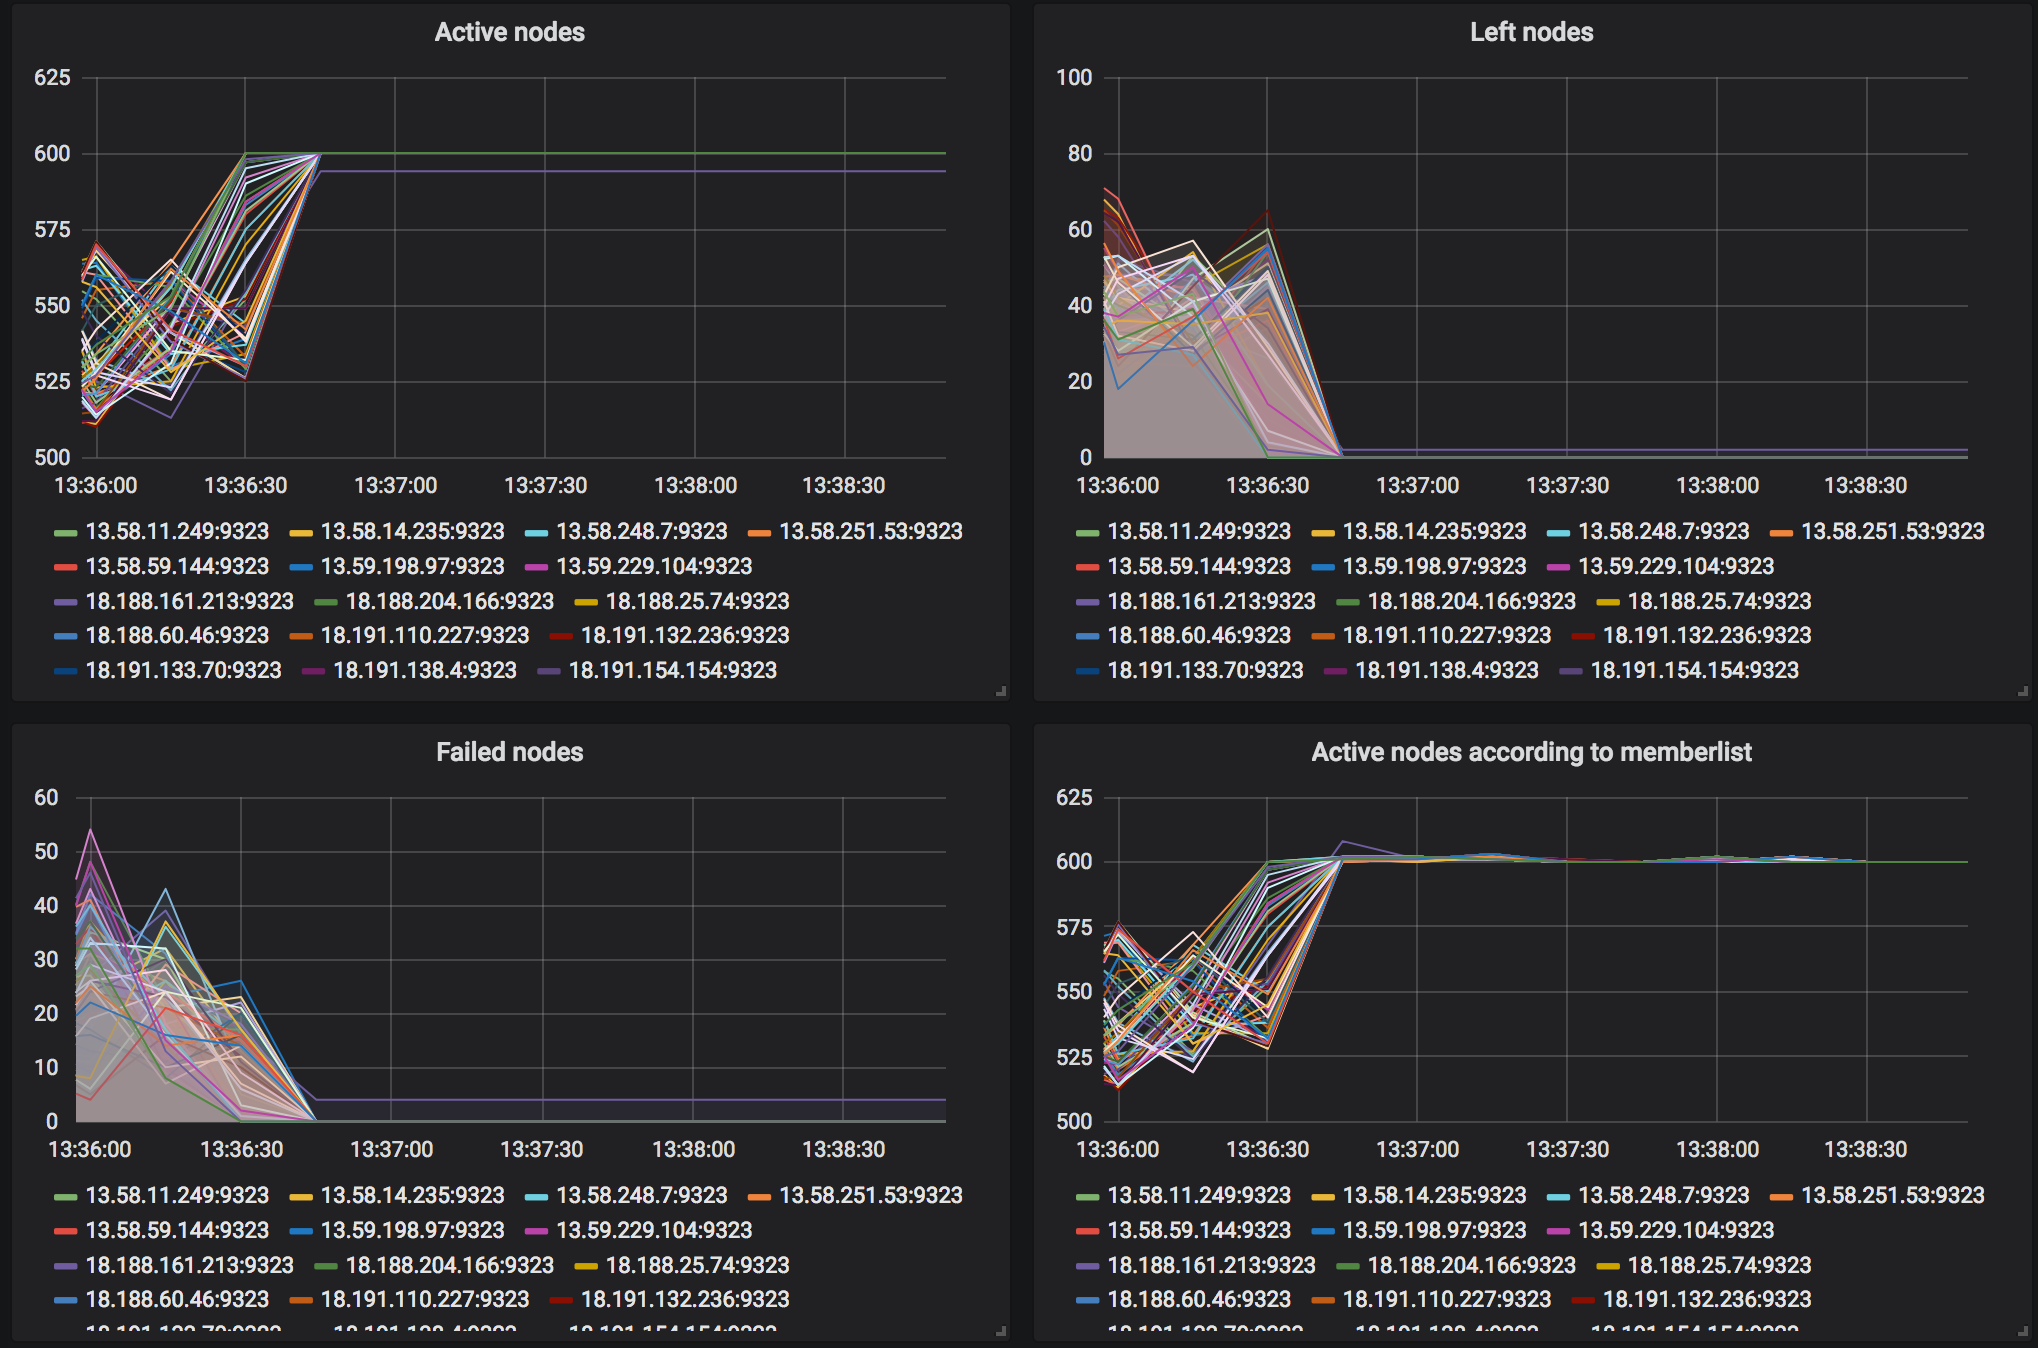
The above graph shows the node states reported as all the worker nodes in the cluster are restarted. All nodes except one return to thinking that all 600 nodes are up.
Active nodes according to memberlist is an extra metric that I added. It increments whenever memberlist calls our NotifyJoin and decrements on NotifyLeave. Note that this number can go above 600. I believe this happens when memberlist finds out about a node's replacement before learning about the previous incarnation's death.
Grepping the logs on a confused node, we see things like this:
docker@ip-172-31-45-234:~$ egrep '172.31.18.196.*(joined|left) gossip' log
Aug 21 05:35:21 ip-172-31-45-234 dockerd[19604]: time="2018-08-21T05:35:21.730419235-07:00" level=info msg="Node 425b3a36483a/172.31.18.196, joined gossip cluster"
Aug 21 05:35:21 ip-172-31-45-234 dockerd[19604]: time="2018-08-21T05:35:21.951832164-07:00" level=info msg="Node a0bd089a322a/172.31.18.196, joined gossip cluster"
Aug 21 05:35:22 ip-172-31-45-234 dockerd[19604]: time="2018-08-21T05:35:22.102242802-07:00" level=info msg="Node a0bd089a322a/172.31.18.196, left gossip cluster"
I think this is what is happening:
- a0bd089a322a joins the cluster.
- a0bd089a322a crashes and rejoins as 425b3a36483a.
- We hear that 425b3a36483a has joined and mark it as active.
- We hear that a0bd089a322a has joined. We mark it as active, and forget about 425b3a36483a, incorrectly thinking that a0bd089a322a is the new instance of it.
- We hear that 425b3a36483a has left the cluster and mark it as failed.
The result is that networkdb thinks that 172.31.18.196 isn't in the cluster. However, memberlist thinks it is in the cluster, and therefore doesn't send us any more events about it.
The version we are testing is @fcrisciani's backport of the current networkdb from master to 17.06.2-ee16 (https://github.com/fcrisciani/libnetwork/tree/bump_17.06-performance).
However, I think the code in master will have the same problem. https://github.com/docker/libnetwork/blob/master/networkdb/event_delegate.go:
	// Every node has a unique ID
	// Check on the base of the IP address if the new node that joined is actually a new incarnation of a previous
	// failed or shutdown one
	e.nDB.purgeReincarnation(mn)
purgeReincarnation only checks the IP address and port (that's all it has, anyway) so I don't think it has any way to know which of the two joiners is replacing the other.
Contributor guide
No contributing guide indexed for this repository
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
Start with networkdb/event_delegate.go and the purgeReincarnation path, then trace how memberlist NotifyJoin and NotifyLeave events update networkdb state. Use the reported join/leave ordering and node-restart scenario as the reproduction case. Done means networkdb remains consistent with memberlist when node incarnations reuse an IP and port.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- go
- Domain
- distributed-systems, networking
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Mostly clear
- Newbie friendliness
- 30/100