microsoft / microsoft/onnxruntime
ONNX Runtime on Nvidia Jetson only 2FPS
@jywu-mysoft is already working on this.
Since Feb 16, 2021.
- Dominant language
- C++
- Stars
- 21.9k
- Forks
- 4.2k
- Avg merge
- 4d 11h
- Merged PRs (30d)
- 184
Description
The Inference of custom trained SSD_MobileNetv2 on Nvidia Jetson Nano is too slow.
Workflow:
Trained Model:
[frozen_graph_infer.zip](https://github.com/microsoft/onnxruntime/files/5956619/frozen_graph_infer.zip)
Convert it to ONNX-Format with tf2onnx tool:
[inference.zip](https://github.com/microsoft/onnxruntime/files/5956621/inference.zip)
Run Inference Script:
[solectrix_inference.zip](https://github.com/microsoft/onnxruntime/files/5956628/solectrix_inference.zip)
Expected Behaviour:
at least 10 FPS (onnxRT call should take >100ms)
Real Behaviour:
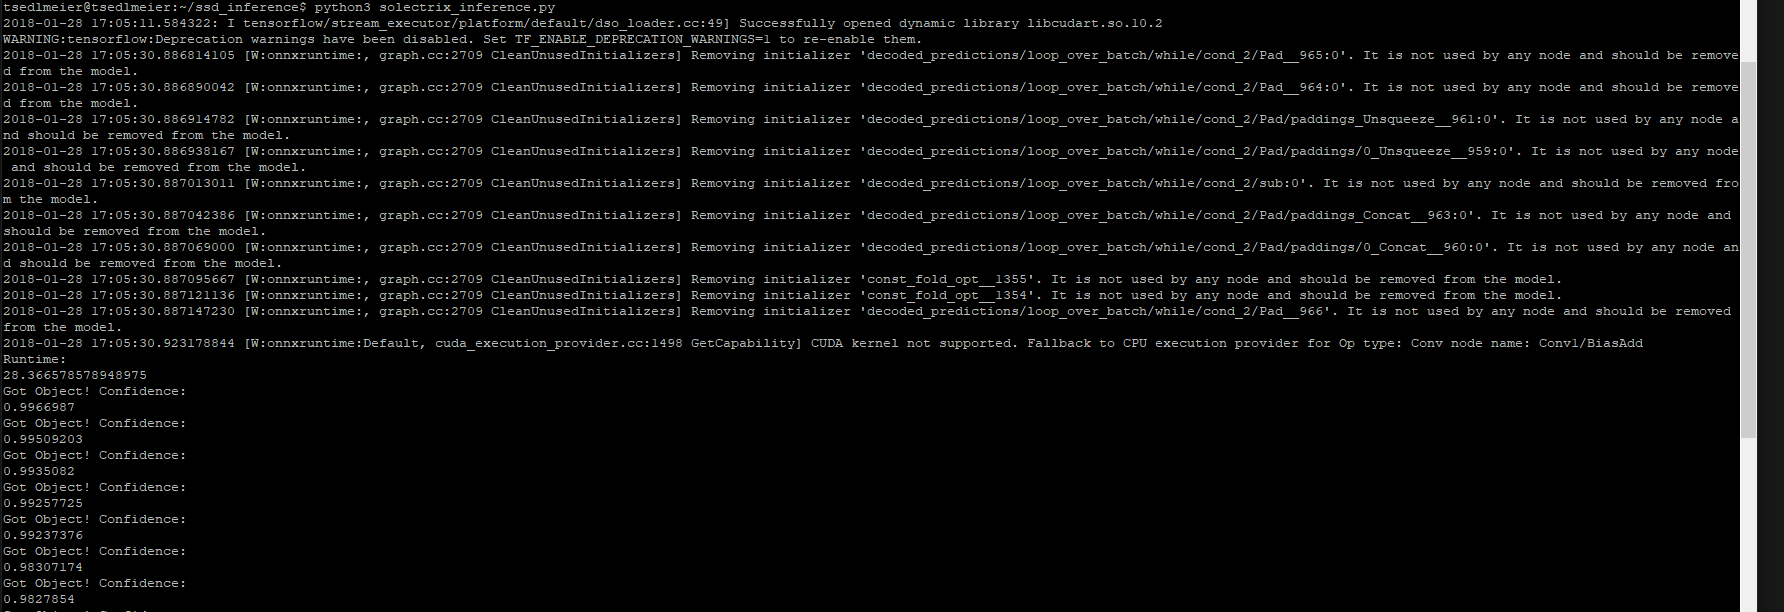
Runtime of function call session.run() takes ~ 500ms
**System information**
Inference on Nvidia Jetson Nano
- ONNX Runtime version: onnxruntime_gpu-1.4.0
- Python version: 3.6
- JetPack 4.4: (based on Ubuntu 18)
- TensorRT 7.1.3
- CUDA 10.2
- cuDNN 8.0
Thank you guy and have a great day!
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Assessment
This issue has not been assessed yet.