max-mapper / max-mapper/zimmer
zimmer misses ~50% of articles
Nobody has claimed this yet.
- Dominant language
- JavaScript
- Stars
- 14
- Forks
- 2
- PR merge metrics
- No merged PRs in 30d
Description
so extracting Simple English Wikipedia runs without error, taking about about ~3h on an EC2 server:
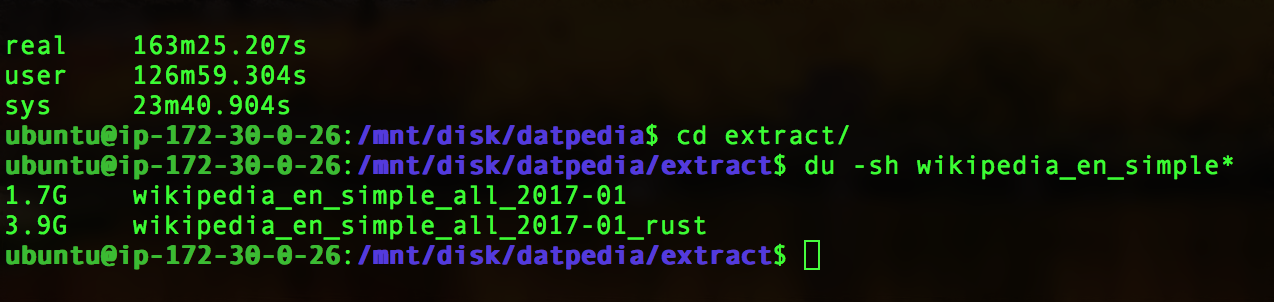
however, only about half the files are present.
i'm comparing zimmer's output to that of the following Zim extractor, written in Rust: https://github.com/dignifiedquire/zim
you can see from the screenshot above that Rust extracts 3.9G of HTML and images, while zimmer extracts 1.7G from the same dump file
spot checking a few specific articles:
the Rust extractor extracts five articles that start with "Hyperte", while zimmer extracts three:
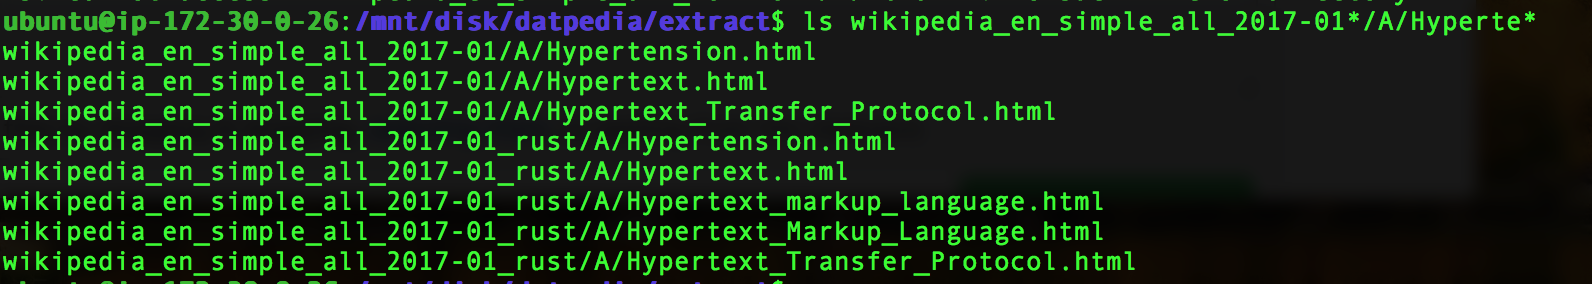
in this case, the two Hypertext_Markup_Language articles are missing
Contributor guide
No contributing guide indexed for this repository
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
Reproduce extraction of the Simple English Wikipedia dump with zimmer and compare its output with the Rust ZIM extractor linked in the issue. Inspect zimmer's ZIM parsing and extraction entry points, focusing on why the two Hypertext_Markup_Language articles and other files are omitted; done means the missing articles are extracted.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- javascript
- Domain
- backend
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Mostly clear
- Newbie friendliness
- 35/100