Huge Overfitting when doing supervised UMAP
Nobody has claimed this yet.
- Dominant language
- Python
- Stars
- 8.3k
- Forks
- 871
- Avg merge
- 1d 13h
- Merged PRs (30d)
- 5
Description
Hi,
When doing a supervised UMAP.fit(X_train, y_train), and then UMAP.transform(X_test), there seem to have a huge overfitting situation:
fit_transform on train set:
(parameters used: UMAP(n_components=2, random_state= 0, n_neighbors = 15, metric = 'jaccard')
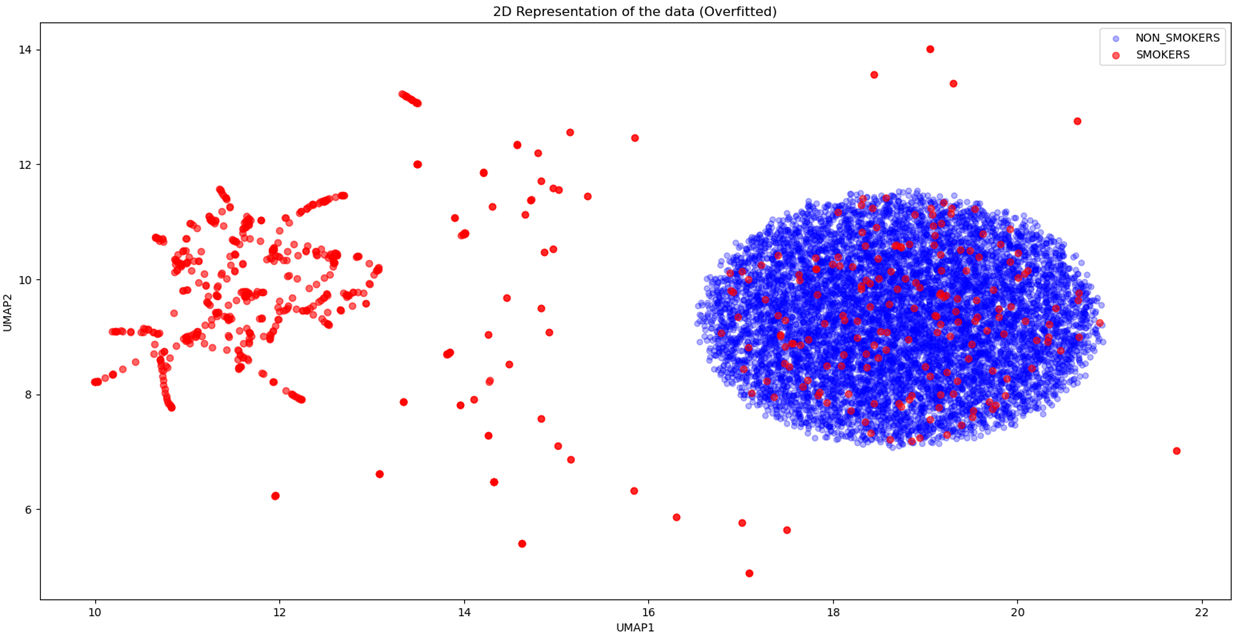
transform on test set:

That's sad because the fit_transform did a really impressive job! Hope it can be fixed one day !
Thanks!
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
Start by reproducing the supervised UMAP example with UMAP(n_components=2, random_state=0, n_neighbors=15, metric='jaccard'), comparing fit_transform(X_train, y_train) with fit(X_train, y_train) followed by transform(X_test). Trace the fitting and transformation entry points; done means explaining or correcting the train/test behavior and covering it with a regression test.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- python
- Domain
- machine-learning
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 25/100