the formula for layout optimization is slightly different from that in UMAP paper?
Nobody has claimed this yet.
- Dominant language
- Python
- Stars
- 8.3k
- Forks
- 871
- Avg merge
- 1d 13h
- Merged PRs (30d)
- 5
Description
Hi,
Just trying to understand the layout optimization part of code, I find that the formula for positive edges here:
` if dist_squared > 0.0:
grad_coeff = -2.0 * a * b * pow(dist_squared, b - 1.0)
grad_coeff /= a * pow(dist_squared, b) + 1.0
else:
grad_coeff = 0.0`
is different from what explained in https://arxiv.org/pdf/1802.03426.pdf chapter 3.2:
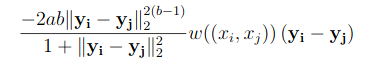
I understand the W is missing because we are doing importance sampling, but the denominator is also slightly different.
Also for negative edges, we do something like this:
` if dist_squared > 0.0:
grad_coeff = 2.0 * gamma * b
grad_coeff /= (0.001 + dist_squared) * (
a * pow(dist_squared, b) + 1
)
elif j == k:
continue
else:
grad_coeff = 0.0`
but in the paper, it is:
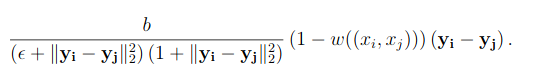
Am I missing something? Or perhaps the version in the code works better?
Thanks a lot in advance
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
Start by locating the positive- and negative-edge layout optimization code shown in the issue, then compare both gradient formulas with chapter 3.2 of the UMAP paper. Determine whether the denominator differences are intentional consequences of importance sampling or an implementation error; done means the discrepancy is explained or corrected with supporting validation.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- python
- Domain
- machine-learning
- Issue type
- Bug
- Difficulty
- 5/5
- Estimated time
- Over a week
- Activity status
- Stale
- Clarity
- Mostly clear
- Newbie friendliness
- 25/100