Weird behaviour when using transform on new data
Nobody has claimed this yet.
- Dominant language
- Python
- Stars
- 8.3k
- Forks
- 871
- Avg merge
- 1d 13h
- Merged PRs (30d)
- 5
Description
I have encountered a very strange behaviour when trying to use UMAP for a fairly simple feature learning scenario.
As a minimal example, I took the digits code from the tutorial and modified it a little in the following way instead of the usual split:
- The training points are now those whose labels are < 9.
- The test points are those with label 9.
This is the code:
```python
import numpy as np
from sklearn.datasets import load_digits
from sklearn.model_selection import train_test_split, cross_val_score
from sklearn.neighbors import KNeighborsClassifier
from sklearn.svm import SVC
import matplotlib.pyplot as plt
import seaborn as sns
%matplotlib inline
import umap
sns.set(context='notebook', style='white', rc={'figure.figsize':(14,10)})
digits = load_digits()
X_train, X_test, y_train, y_test = train_test_split(digits.data,
digits.target,
stratify=digits.target,
random_state=42)
print(X_train.shape, X_test.shape)
i1 = np.where(digits.target<9)[0]
i2 = np.where(digits.target==9)[0]
X_train = digits.data[i1,:]
y_train = digits.target[i1]
X_test = digits.data[i2,:]
y_test = digits.target[i2]
print(X_train.shape, X_test.shape)
trans = umap.UMAP(n_neighbors=15, random_state=42).fit(X_train, y_train)
plt.scatter(trans.embedding_[:, 0], trans.embedding_[:, 1], s= 5, c=y_train, cmap='Spectral')
plt.title('Embedding of the training set by UMAP', fontsize=24);
test_embedding = trans.transform(X_test)
alldata = np.concatenate((trans.embedding_, test_embedding))
yy = np.concatenate((y_train, y_test))
plt.scatter(alldata[:, 0], alldata[:, 1], s= 5, c=yy, cmap='Spectral')
plt.title('Now apply the transform to the test and plot all together:', fontsize=24);
```
The result is very strange:
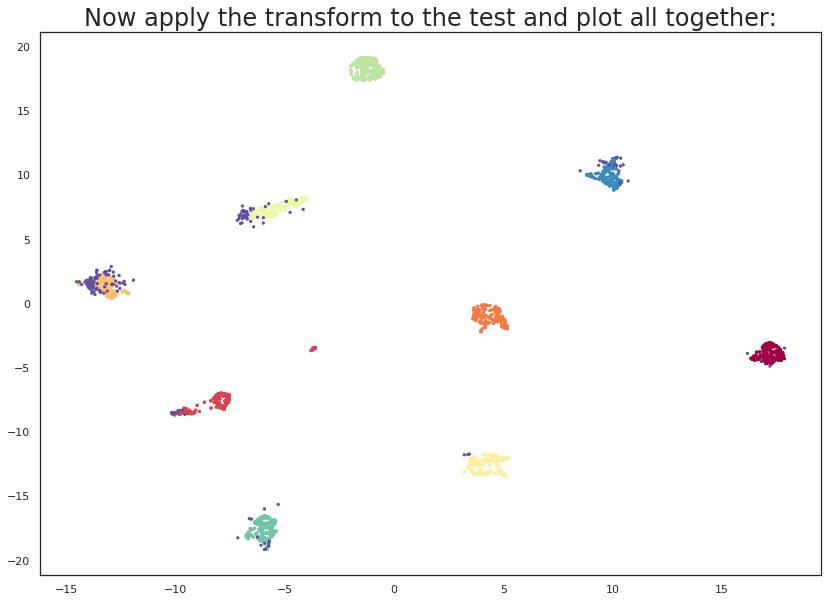
It seems as if the training data is somehow mixed up with the transformation of the completely unrelated test data. The same thing happens with other data as well.
Is this a bug?
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
Start by running the provided Python digits example, focusing on UMAP(...).fit(X_train, y_train) and trans.transform(X_test). Compare the training embedding and transformed test points in the separate and combined plots. Done means determining whether the observed mixing is expected behavior or a reproducible transform bug.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- numpy, python, scikit-learn
- Domain
- machine-learning
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 35/100