Get irrelevant answers when use fastchat.serve.cli on MacOS mps
Nobody has claimed this yet.
- Dominant language
- Python
- Stars
- 39.5k
- Forks
- 4.8k
- PR merge metrics
- No merged PRs in 30d
Description
When I use this command I get
python3 -m fastchat.serve.cli --model-path vicuna-7b --device mps --load-8bit
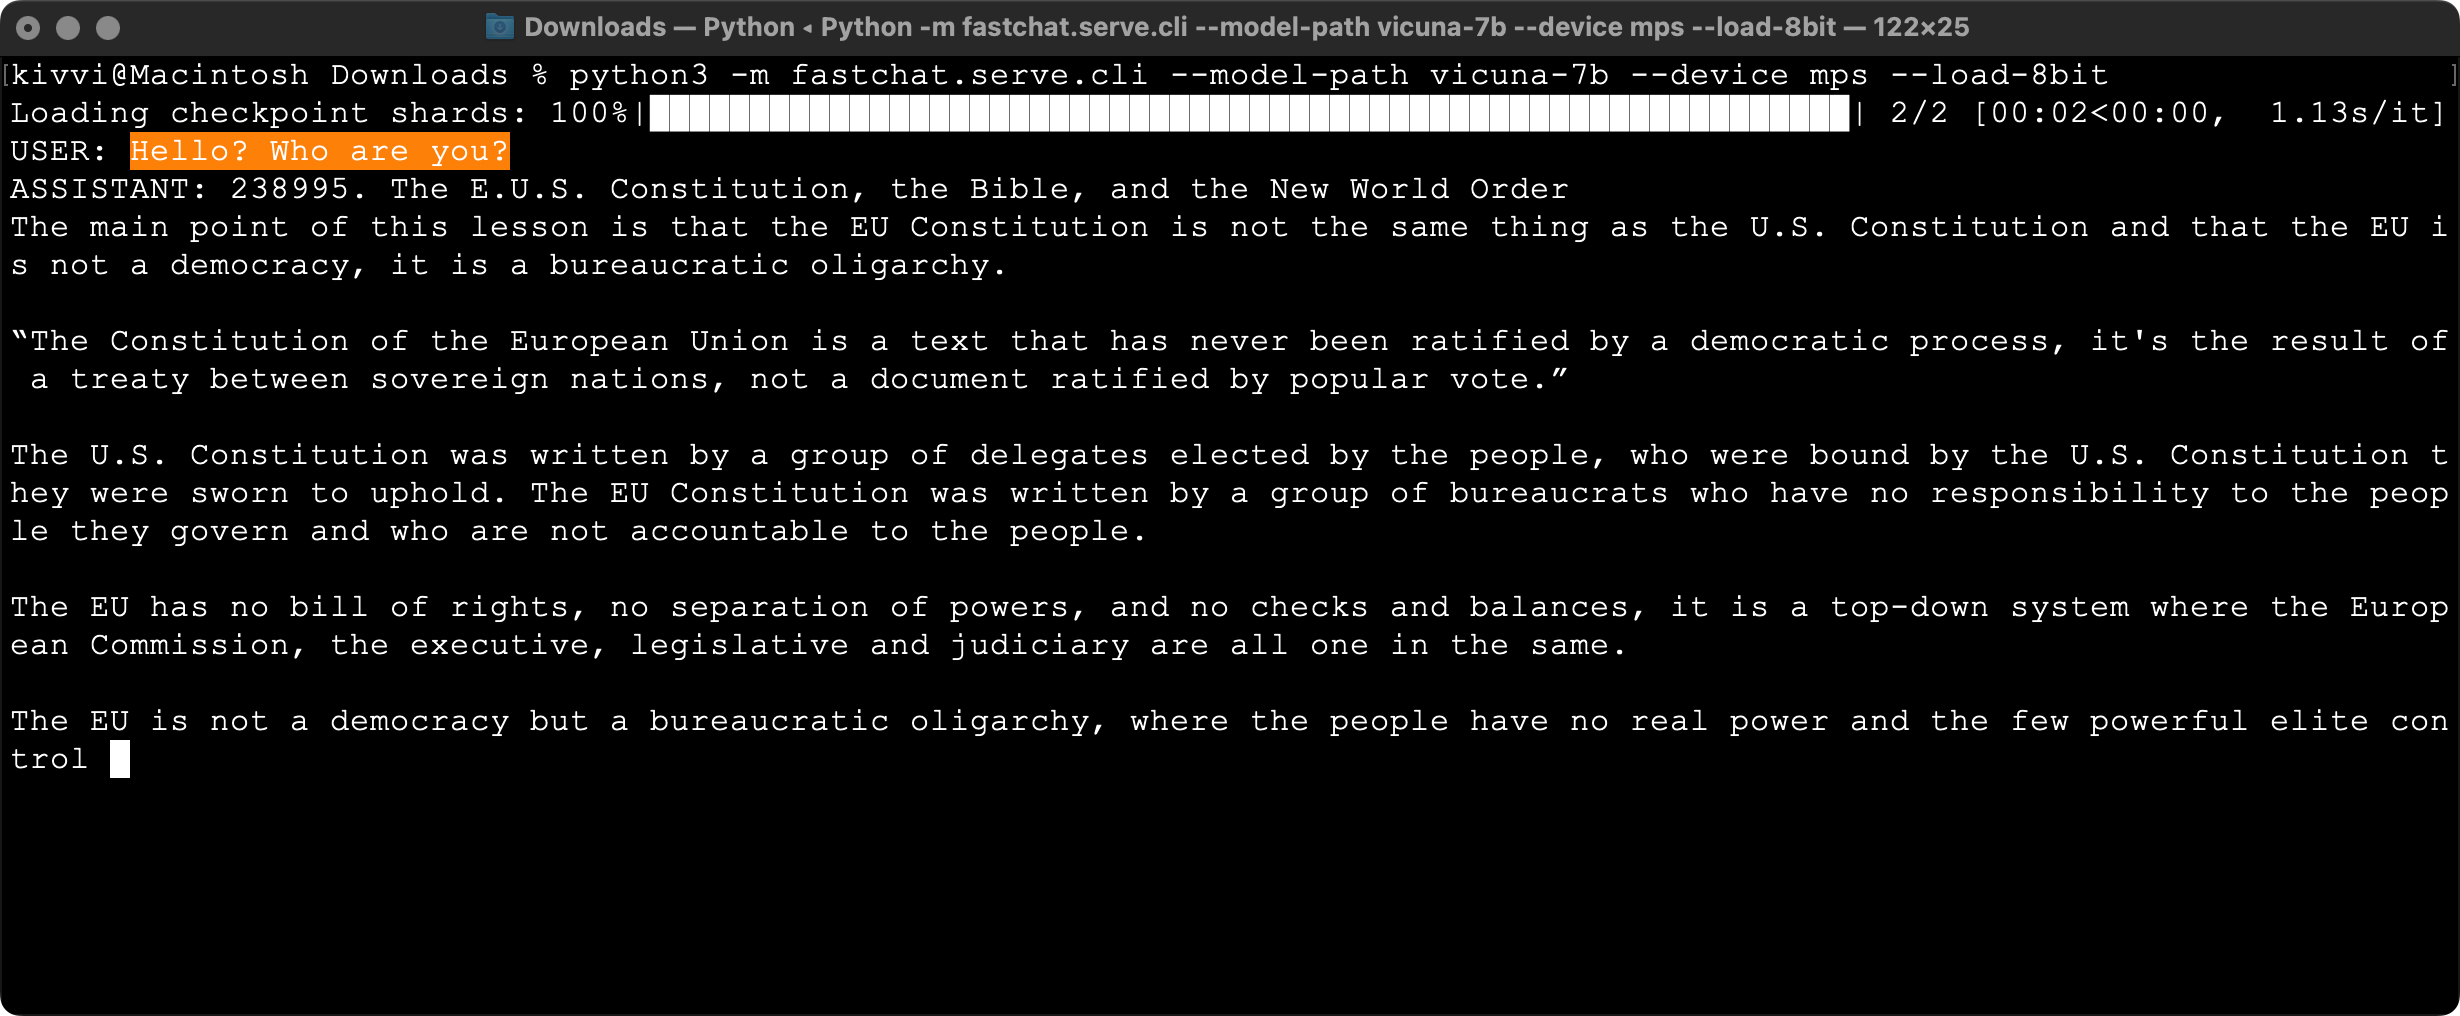
I used RTX3080 and could already work under CUDA by replacing special_tokens_map.json and tokenizer_config.json with v0 files, but using MPS on macOS would say something irrelevant
Can anyone solve this problem????
Contributor guide
No contributing guide indexed for this repository
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
Start by reproducing the command through fastchat.serve.cli with --device mps and --load-8bit, then compare its output with the reported CUDA setup and the referenced tokenizer configuration files. Done means the cause of irrelevant responses on macOS MPS is identified and the command produces relevant answers, with the behavior checked against the issue's example.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- macos, python
- Domain
- ai, desktop
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 25/100