CRC performance on Skylake (prefetching tweaks)
- Dominant language
- C
- Stars
- 1.1k
- Forks
- 346
- PR merge metrics
- No merged PRs in 30d
Description
I've been investigating performance of CRCs on a few intel microarchitectures, and I am seeing some interesting gaps for Skylake related to prefetching.
The top line is that the current non-temporal prefetches in the inner loop of the `crc64_refl_by8` implementations seems to be hindering the potential throughput for my Skylake machine for larger inputs. My experimentation took place on a Xeon W-2155.
I tried 3 different variants on the existing `crc64_refl_by8` asm:
1) CRC64 unchanged
2) CRC64 prefetch tweak: Remove half of the prefetchnta instructions (so the density is every 64B rather than every 32B), and increase the prefetch distance from 1024B to 4096B
3) CRC64 no prefetch: Remove all of the prefetchnta instructions from the inner loop
I then modified the `crc64_funcs_perf` binary to test for sizes from 8KiB to 1MiB and output the measured throughput over 3 seconds - and generated the following figures:
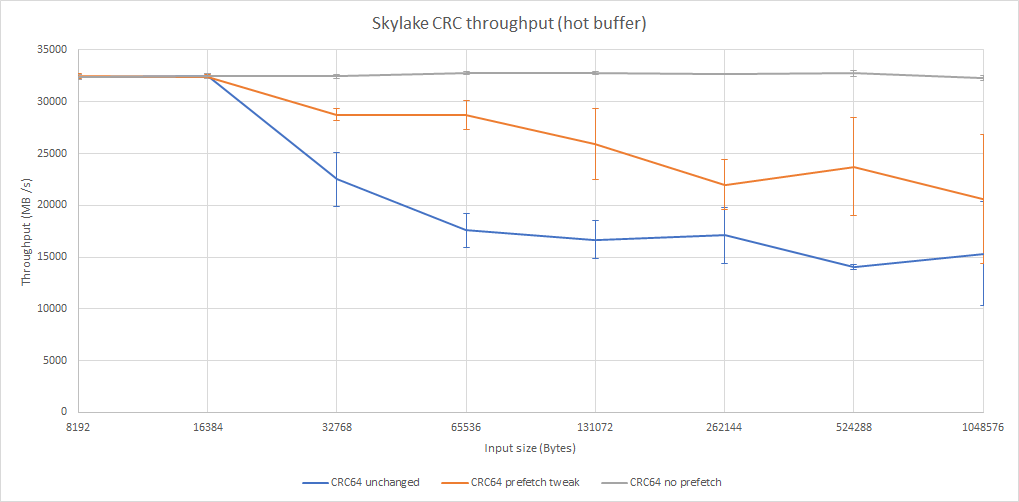
(I ran the binaries 5 times each and plot the average throughput, with the error bars showing the standard deviation)
I also generated figures when performing CRCs on small chunks out of a 1GiB buffer (so the data should not already be in any level cache). Between each call to a CRC function, the pointer is incremented by the test buffer size + 128KiB (looping back to the beginning on overflow). This should mean we shouldn't be speculatively hitting SW prefetches for the next buffer ahead of time (and experimentally seems not to be _trivial_ for the HW prefetcher in the absence of SW prefetches):
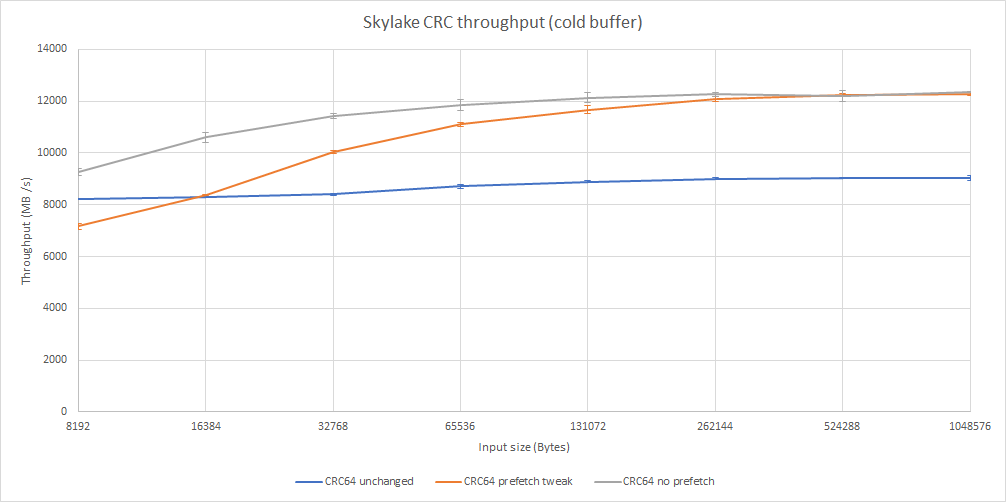
To me it seems that on Skylake, the current asm is suboptimal - if we _must_ use non-temporal prefetches to avoid cache pollution (they notably aren't being used in the `crc64_refl_by16` versions!), a larger prefetch distance seems to be worth doing.
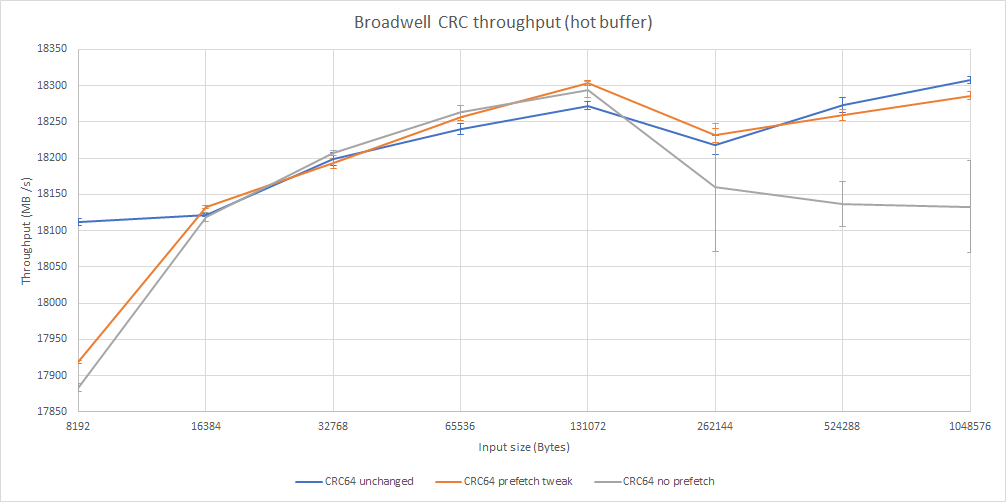
I also briefly ran the same hot buffer test on an available Broadwell machine, and the prefetching makes not much difference one way or another - but the current asm does seem to be _marginally_ better than the alternatives I tried at 8KiB size and for large sizes:
I would be interested if these results can be reproduced on other Skylake systems, and if so I am curious as to what you think is the best way to balance library complexity with the performance here!
(I am considering making a PR to share the changes to the `crc64_funcs_perf` binary, but my changes are currently a bit hacky!)
Contributor guide
Assessment
This issue has not been assessed yet.