huggingface / huggingface/datasets
Profiling for HF Filesystem shows there are easy performance gains to be made
- Dominant language
- Python
- Stars
- 22k
- Forks
- 3.4k
- Avg merge
- 5d 7h
- Merged PRs (30d)
- 17
Description
### Describe the bug
# Let's make it faster
First, an evidence...

Figure 1: CProfile for loading 3 files from cerebras/SlimPajama-627B train split, and 3 files from test split using streaming=True. X axis is 1106 seconds long.
See? It's pretty slow.
What is resolve pattern doing?
```
resolve_pattern called with **/train/** and hf://datasets/cerebras/SlimPajama-627B@2d0accdd58c5d5511943ca1f5ff0e3eb5e293543
resolve_pattern took 20.815081119537354 seconds
```
Makes sense. How to improve it?
## Bigger project, biggest payoff
Databricks (and consequently, spark) store a compressed manifest file of the files contained in the remote filesystem.
Then, you download one tiny file, decompress it, and all the operations are local instead of this shenanigans.
It seems pretty straightforward to make dataset uploads compute a manifest and upload it alongside their data.
This would make resolution time so fast that nobody would ever think about it again.
It also means you either need to have the uploader compute it _every time_, or have a hook that computes it.
## Smaller project, immediate payoff: Be diligent in avoiding deepcopy
Revise the _ls_tree method to avoid deepcopy:
```
def _ls_tree(
self,
path: str,
recursive: bool = False,
refresh: bool = False,
revision: Optional[str] = None,
expand_info: bool = True,
):
..... omitted .....
for path_info in tree:
if isinstance(path_info, RepoFile):
cache_path_info = {
"name": root_path + "/" + path_info.path,
"size": path_info.size,
"type": "file",
"blob_id": path_info.blob_id,
"lfs": path_info.lfs,
"last_commit": path_info.last_commit,
"security": path_info.security,
}
else:
cache_path_info = {
"name": root_path + "/" + path_info.path,
"size": 0,
"type": "directory",
"tree_id": path_info.tree_id,
"last_commit": path_info.last_commit,
}
parent_path = self._parent(cache_path_info["name"])
self.dircache.setdefault(parent_path, []).append(cache_path_info)
out.append(cache_path_info)
return copy.deepcopy(out) # copy to not let users modify the dircache
```
Observe this deepcopy at the end. It is making a copy of a very simple data structure. We do not need to copy. We can simply generate the data structure twice instead. It will be much faster.
```
def _ls_tree(
self,
path: str,
recursive: bool = False,
refresh: bool = False,
revision: Optional[str] = None,
expand_info: bool = True,
):
..... omitted .....
def make_cache_path_info(path_info):
if isinstance(path_info, RepoFile):
return {
"name": root_path + "/" + path_info.path,
"size": path_info.size,
"type": "file",
"blob_id": path_info.blob_id,
"lfs": path_info.lfs,
"last_commit": path_info.last_commit,
"security": path_info.security,
}
else:
return {
"name": root_path + "/" + path_info.path,
"size": 0,
"type": "directory",
"tree_id": path_info.tree_id,
"last_commit": path_info.last_commit,
}
for path_info in tree:
cache_path_info = make_cache_path_info(path_info)
out_cache_path_info = make_cache_path_info(path_info) # copy to not let users modify the dircache
parent_path = self._parent(cache_path_info["name"])
self.dircache.setdefault(parent_path, []).append(cache_path_info)
out.append(out_cache_path_info)
return out
```
Note there is no longer a deepcopy in this method. We have replaced it with generating the output twice. This is substantially faster. For me, the entire resolution went from 1100s to 360s.
## Medium project, medium payoff
After the above change, we have this profile:
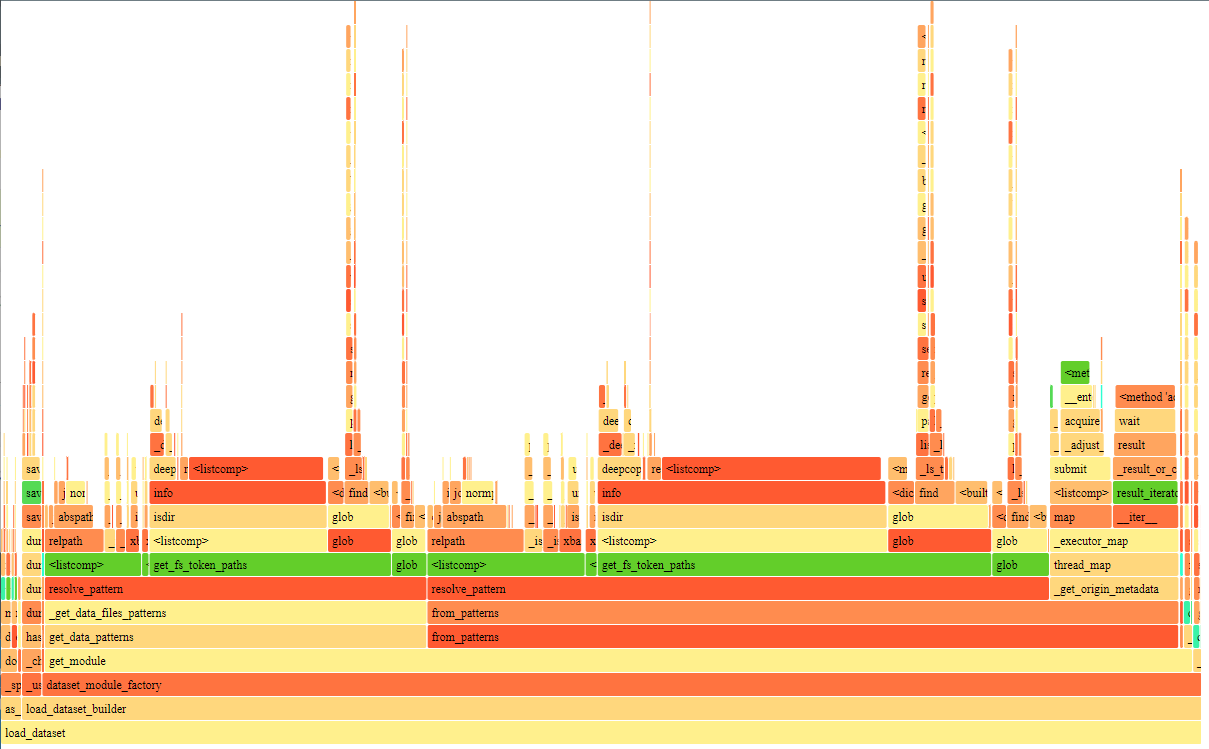
Figure 2: x-axis is 355 seconds. Note that globbing and _ls_tree deep copy is gone. No surprise there. It's much faster now, but we still spend ~187seconds in get_fs_token_paths.
Well get_fs_token_paths is part of fsspec. We don't need to fix that because we can trust their developers to write high performance code. Probably the caller has misconfigured something. Let's take a look at the storage_options being provided to the filesystem that is constructed during this call.
Ah yes, streaming_download_manager::_prepare_single_hop_path_and_storage_options. We know streaming download manager is not compatible with async right now, but we really need this specific part of the code to be async. We're spending so much time checking isDir on the remote filesystem, it's a huge waste.
We can make the call easily 20-30x faster by using async, removing this performance bottleneck almost entirely (and reducing the total time of this part of the code to <30s. There is no reason to block async isDir calls for streaming.
I'm not going to mess w/ this one myself; I didn't write the streaming impl, and I don't know how it works, but I know the isDir check can be async.
### Steps to reproduce the bug
```
with cProfile.Profile() as pr:
pr.enable()
# Begin Data
if not os.path.exists(data_cache_dir):
os.makedirs(data_cache_dir, exist_ok=True)
training_dataset = load_dataset(training_dataset_name, split=training_split, cache_dir=data_cache_dir, streaming=True).take(training_slice)
eval_dataset = load_dataset(eval_dataset_name, split=eval_split, cache_dir=data_cache_dir, streaming=True).take(eval_slice)
# End Data
pr.disable()
pr.create_stats()
if not os.path.exists(profiling_path):
os.makedirs(profiling_path, exist_ok=True)
pr.dump_stats(os.path.join(profiling_path, "cprofile.prof"))
```
run this code for "cerebras/SlimPajama-627B" and whatever other params
### Expected behavior
Something better.
### Environment info
- `datasets` version: 2.18.0
- Platform: Linux-5.15.146.1-microsoft-standard-WSL2-x86_64-with-glibc2.35
- Python version: 3.10.13
- `huggingface_hub` version: 0.21.3
- PyArrow version: 15.0.0
- Pandas version: 2.2.1
- `fsspec` version: 2024.2.0
Contributor guide
Assessment
This issue has not been assessed yet.