huggingface / huggingface/datasets
Identify which shard data belongs to
- Dominant language
- Python
- Stars
- 22k
- Forks
- 3.4k
- Avg merge
- 5d 7h
- Merged PRs (30d)
- 17
Description
**Is your feature request related to a problem? Please describe.**
I'm training on a large dataset made of multiple sub-datasets.
During training I can observe some jumps in loss which may correspond to different shards.
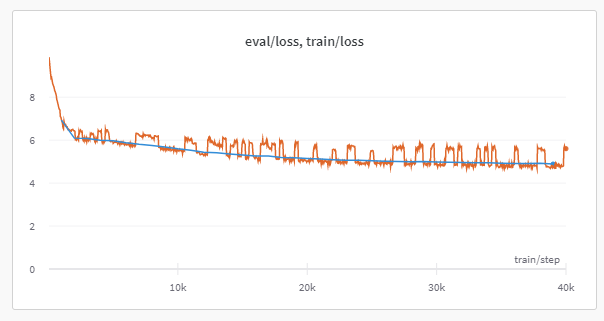
My suspicion is that either:
* some of the sub-datasets are harder for the model than others
* some of the sub-datasets are not formatted properly
I'd like to identify which shards correspond to those jumps.
**Describe the solution you'd like**
It would be nice to have a key associated to each data sample or data batch containing details on where the data comes from (shard idx + item idx within the shard).
This should be supported both in local and streaming mode.
**Describe alternatives you've considered**
A fix would be for me to add myself details (shard id, sample id) as part of each data sample.
The inconvenient is that it requires users to process/reupload every dataset when they need this feature.
Contributor guide
Assessment
This issue has not been assessed yet.