huggingface / huggingface/datasets
`datasets.map` multi processing much slower than single processing
- Dominant language
- Python
- Stars
- 22k
- Forks
- 3.4k
- Avg merge
- 5d 7h
- Merged PRs (30d)
- 17
Description
Hi, thank you for the great library.
I've been using datasets to pretrain language models, and it often involves datasets as large as ~70G.
My data preparation step is roughly two steps: `load_dataset` which splits corpora into a table of sentences, and `map` converts a sentence into a list of integers, using a tokenizer.
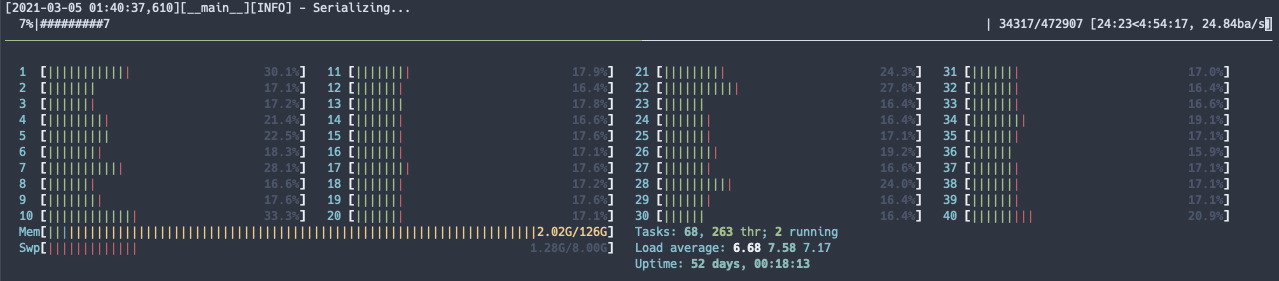
I noticed that `map` function with `num_proc=mp.cpu_count() //2` takes more than 20 hours to finish the job where as `num_proc=1` gets the job done in about 5 hours. The machine I used has 40 cores, with 126G of RAM. There were no other jobs when `map` function was running.
What could be the reason? I would be happy to provide information necessary to spot the reason.
p.s. I was experiencing the imbalance issue mentioned in [here](https://github.com/huggingface/datasets/issues/610#issuecomment-705177036) when I was using multi processing.
p.s.2 When I run `map` with `num_proc=1`, I see one tqdm bar but all the cores are working. When `num_proc=20`, only 20 cores work.
Contributor guide
Assessment
This issue has not been assessed yet.