Non-leader task in taskgroup not being sent interrupt
- Dominant language
- Go
- Stars
- 17k
- Forks
- 2.1k
- Avg merge
- 1d 9h
- Merged PRs (30d)
- 105
Description
### Nomad version
Nomad v0.9.3 (c5e8b66c3789e4e7f9a83b4e188e9a937eea43ce)
### Operating system and Environment details
Amazon Linux 2
### Issue
Non-leader task in taskgroup receives no interrupt when Nomad decides an allocation should be stopped, say, from a count decrement.
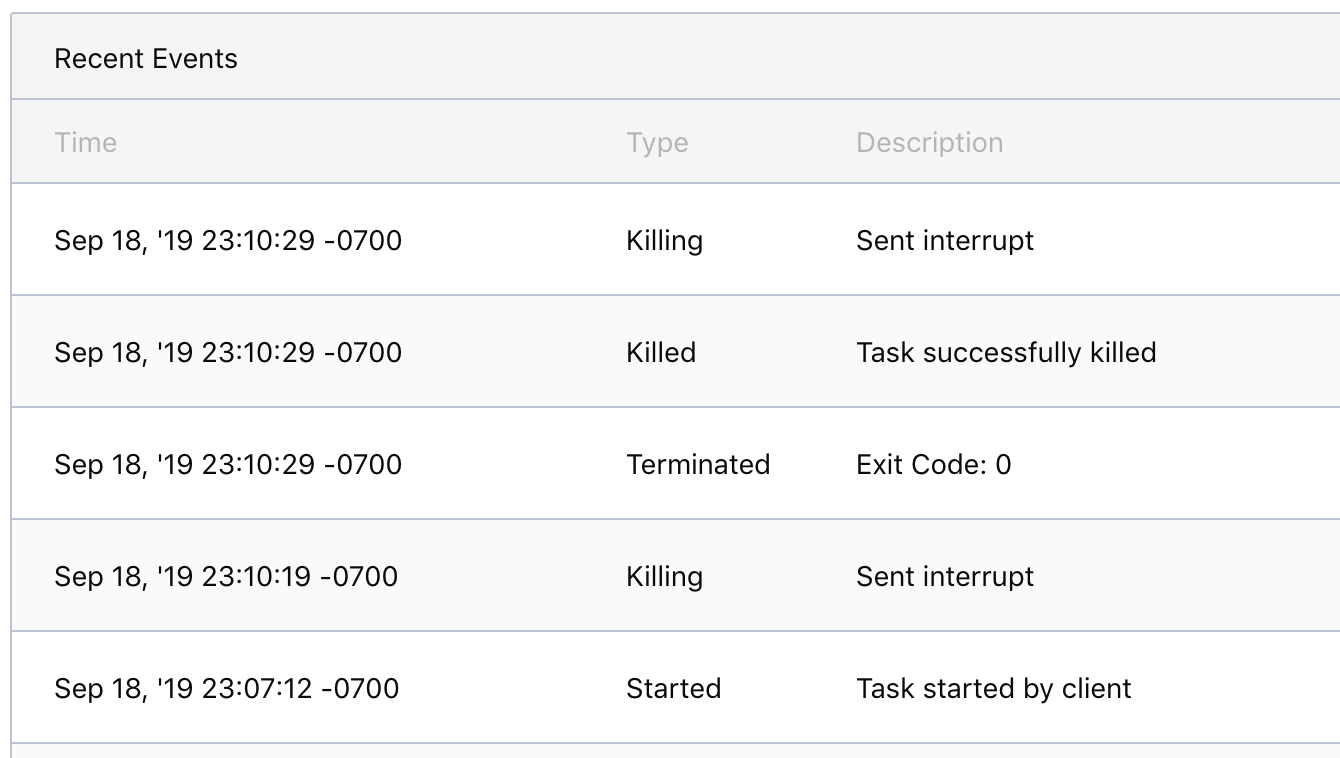
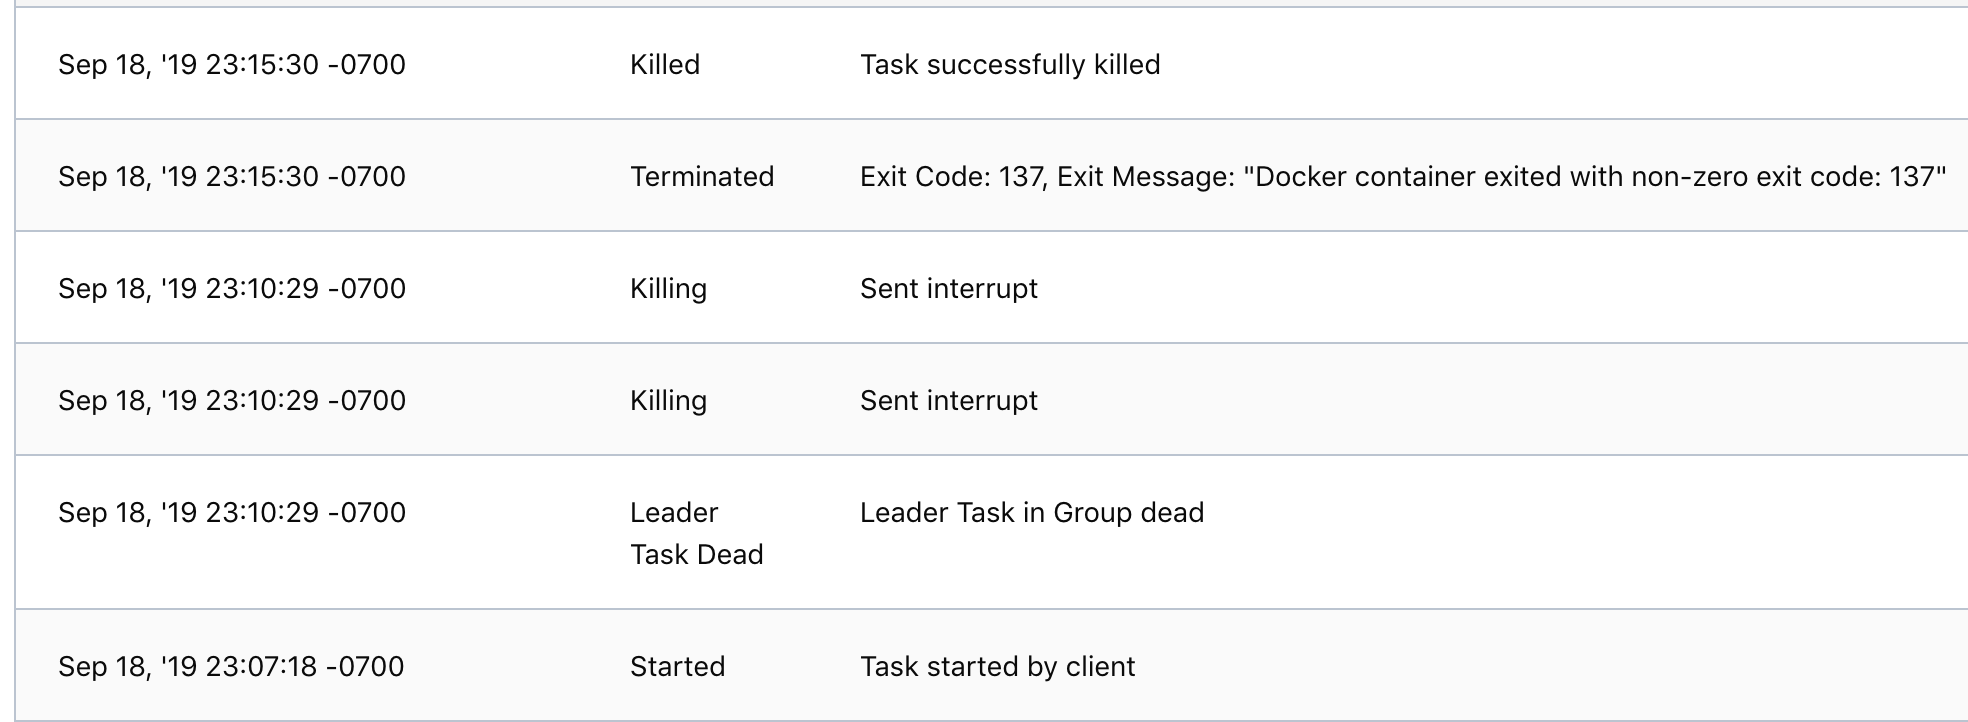
The leader task, which is the task where all the services are registered to Consul, properly handles the `shutdown_delay` and `kill_timeout`, but the secondary task receives no interrupt _until_ the leader task dies. Then it receives an interrupt _because_ the leader task is dead.
This is a problem because the leader task is the sidecar proxy which is the source network for the secondary task, the app itself. Since it receives no interrupts, it is unable to perform graceful shutdown actions until it receives its interrupt, which is when the network is gone since it was attached to the leader task.
### Reproduction steps
1. Create a TaskGroup with two tasks, both using the docker driver
2. Set one task as `leader`
3. Set `"network_mode": "container:-${NOMAD_ALLOC_ID}"` for the secondary
4. Register the healthchecks on the leader
5. Submit the job
6. Reduce the count of the job
7. Verify the leader task gets an interrupt, verify the secondary task gets no interrupt
8. After the `shutdown_delay` and leader terminates, verify the secondary task detects leader is gone
9. Verify the secondary task is sent its interrupt
Leader Task/Proxy:
Secondary Task/App
I believe the expected behavior is every task in a taskgroup should receive an interrupt at the same time.
Contributor guide
No contributing guide indexed for this repository
Research direction
Reproduce the two-task Docker task group described in the issue, including the leader task, Consul health checks, container network mode, and a reduced job count. Trace the allocation shutdown path for task groups and compare interrupt delivery to the leader and secondary tasks. Done means every task receives its interrupt during shutdown, before the leader's network disappears.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- docker, go
- Domain
- distributed-systems, infrastructure
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Mostly clear
- Newbie friendliness
- 35/100