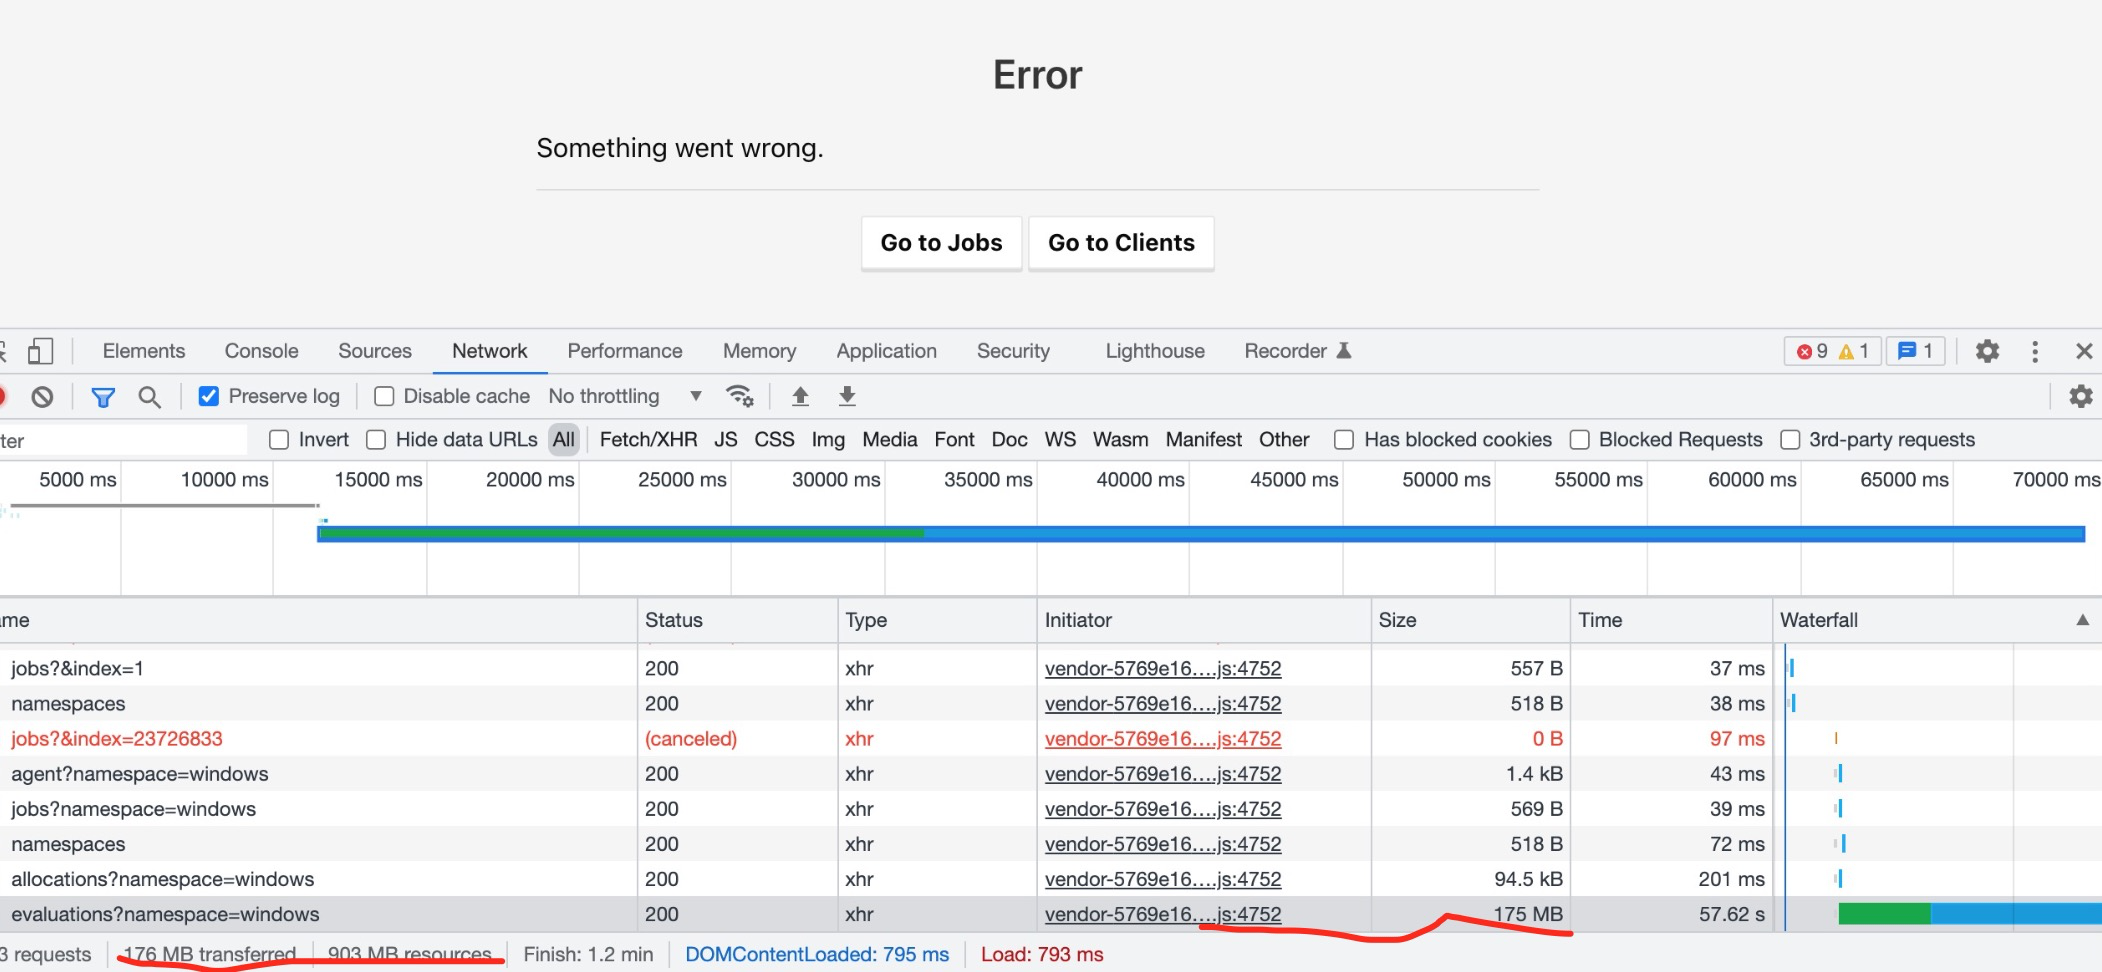
Return the data is too large, causing the ui to crash.
- Dominant language
- Go
- Stars
- 17k
- Forks
- 2.1k
- Avg merge
- 1d 9h
- Merged PRs (30d)
- 105
Description
### Nomad version
1.2.4
### Operating system and Environment details
centos7
### Issue
### Reproduction steps
The number of allocation errors of job exceeded 100,000 records due to frequent client shutdown restart.
```
// stop job and purge
nomad stop -namespace=windows -purge agent
// start
nomad run agent.hcl
```
#### Expected Result
#### Actual Result
Stop the job and recycle the entire job related raft state data and start the task again as if the previous job state data is still in the raft
### Job file (if appropriate)
```
job "agent" {
type = "system"
datacenters = [ "dc1" ]
namespace = "windows"
constraint {
attribute = "${attr.kernel.name}"
value = "windows"
}
group "agent" {
task "telegraf" {
driver = "raw_exec"
config {
command = "local/telegraf.exe"
args = ["--console","--config", "http://10.2.18.79:8086/api/v2/telegrafs/08652db510c47000"]
}
env {
INFLUX_TOKEN = "xxx"
}
artifact {
source = "http://10.2.18.78:8000/telegraf.small-${attr.kernel.name}-${attr.cpu.arch}.tar.gz"
}
}
}
}
```
### Nomad Server logs (if appropriate)
### Nomad Client logs (if appropriate)
Contributor guide
No contributing guide indexed for this repository
Research direction
Start by reproducing the reported case with more than 100,000 allocation errors after stopping and restarting the `agent` job in Nomad 1.2.4. Inspect the UI response and related Raft state to determine where the excessive data is returned; done means the same workflow no longer crashes the UI.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- go
- Domain
- backend
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 20/100