Cross-DC RPC failures after yamux ping timeout causes DNS query timeouts
- Dominant language
- Go
- Stars
- 30.1k
- Forks
- 4.6k
- Avg merge
- 1d 18h
- Merged PRs (30d)
- 39
Description
### Overview of the Issue
We end up having to do a decent amount of cross-dc dns lookups. A few times a day hundreds of these lookups fail. What's weird is during one instance I only see 25 errors during this issue across all servers with the message "RPC failed to server" but I see 136 errors with the message "RPC failed to server in DC". I'm confused why there would be a such a discrepancy? We have `dns.use_cache` enabled with `dns.cache_max_age` set to `1s`. I don't see any `consul_consul_cache_prepared_query_fetch_error` metrics during this time but I do see `consul_consul_cache_prepared_query_fetch_success`. I don't know why there wouldn't be any errors at the cache level.
The instance with logs below happened at 15:02 but there wasn't a huge spike in DNS query timeouts until a few minutes later:
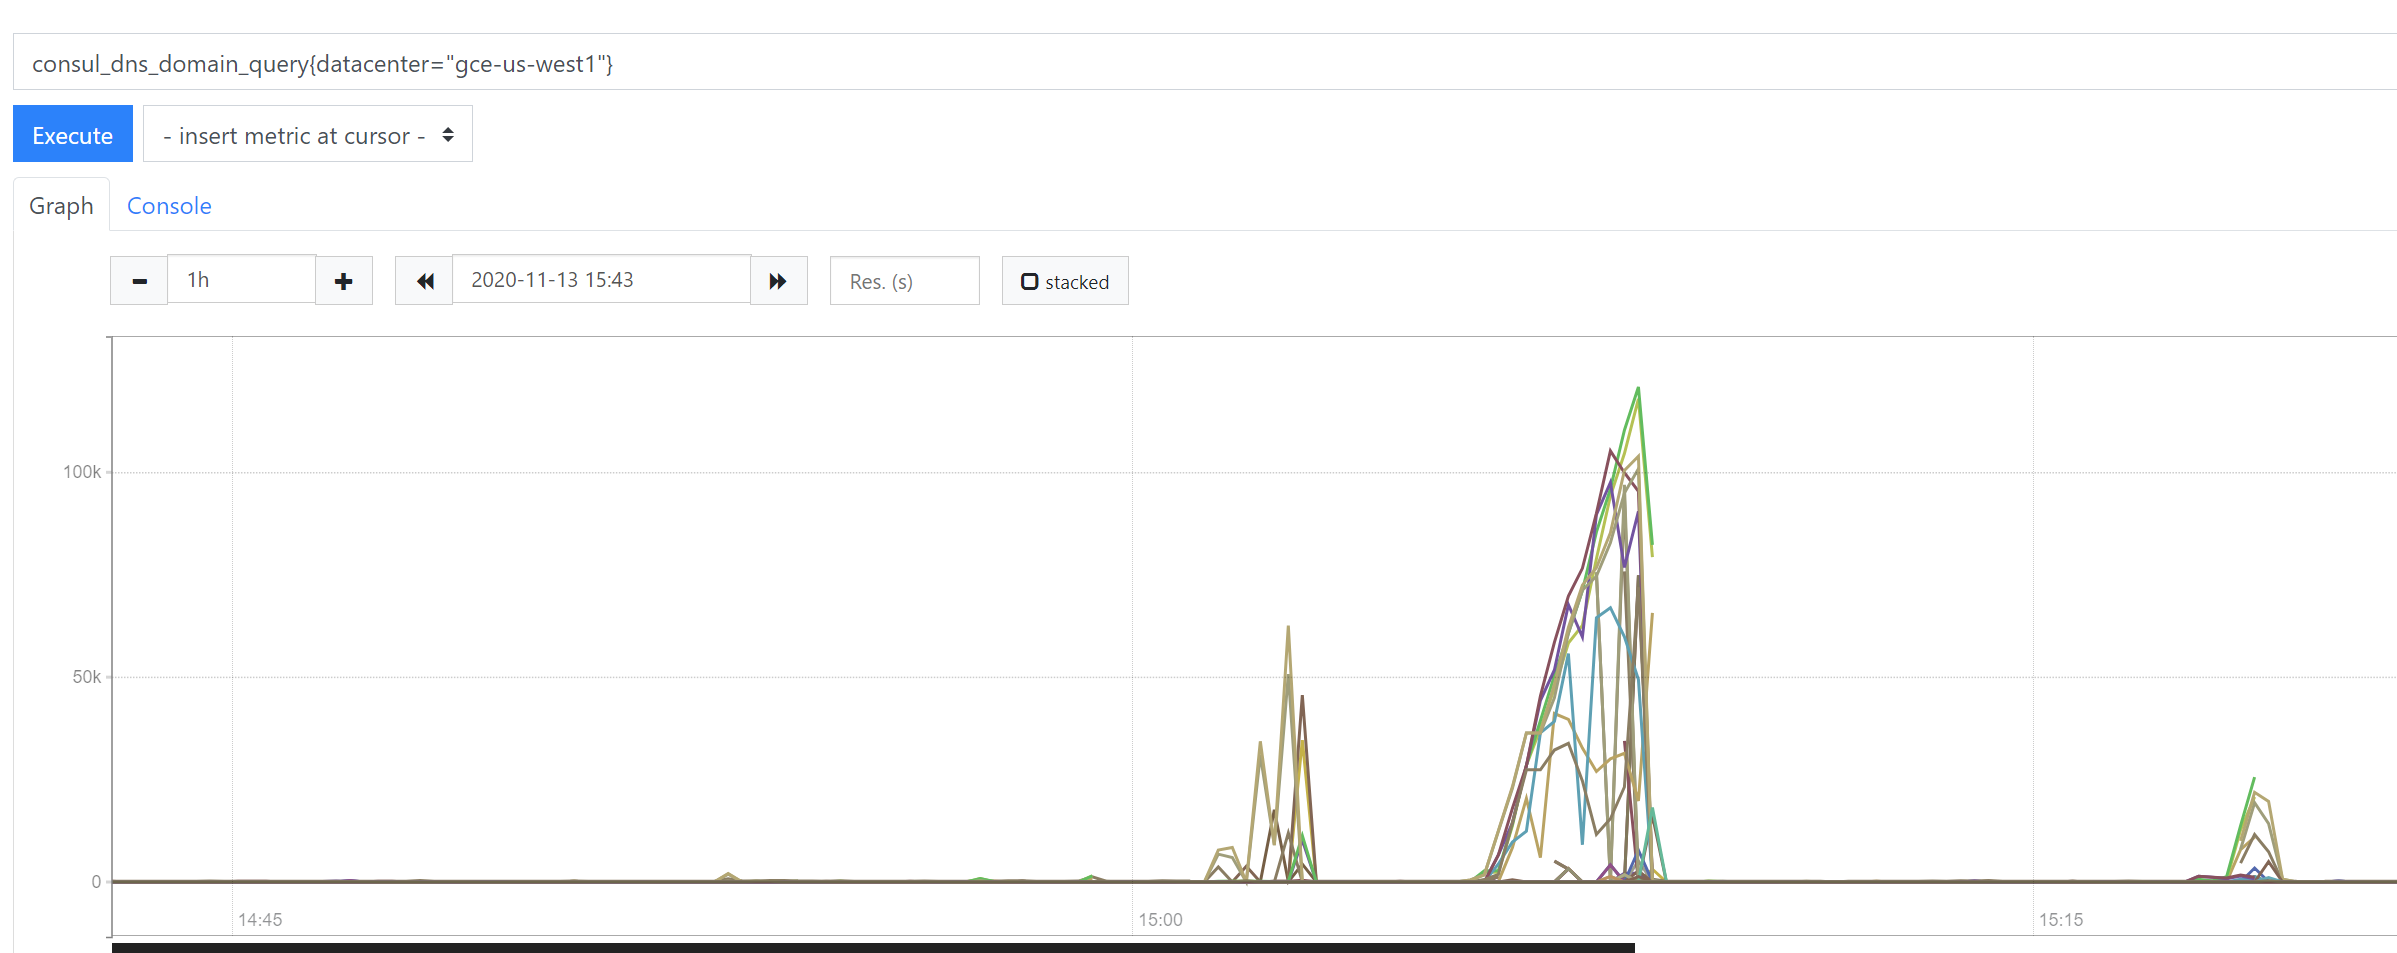
I don't see any logs about failed RPCs after 15:02 so I don't understand how to debug the increase in DNS query latency that happened a few minutes later.
I haven't determined the exact network conditions that trigger the initial yamux errors. It could be a network blip or something that causes the underlying session to fail, I'm not sure. I'm still trying to understand what causes the ping to fail.
#### Reproduction Steps
Unknown yet
### Consul info for both Client and Server
Server info
```
agent:
check_monitors = 0
check_ttls = 6
checks = 7
services = 6
build:
prerelease =
revision = a9322b9c
version = 1.8.3
consul:
acl = disabled
bootstrap = false
known_datacenters = 7
leader = false
leader_addr = 10.138.0.11:8300
server = true
raft:
applied_index = 79511512
commit_index = 79511512
fsm_pending = 0
last_contact = 40.635469ms
last_log_index = 79511512
last_log_term = 63
last_snapshot_index = 79504437
last_snapshot_term = 63
latest_configuration = [{Suffrage:Voter ID:35bcf6cf-e41d-3dad-9ea5-4cfa519d9cdc Address:10.138.0.12:8300} {Suffrage:Voter ID:4e041722-daeb-60bf-be7f-2de6b0865508 Address:10.138.0.13:8300} {Suffrage:Voter ID:e49a0ba6-3d0b-6fd4-a70c-ef1eff762905 Address:10.138.0.11:8300}]
latest_configuration_index = 0
num_peers = 2
protocol_version = 3
protocol_version_max = 3
protocol_version_min = 0
snapshot_version_max = 1
snapshot_version_min = 0
state = Follower
term = 63
runtime:
arch = amd64
cpu_count = 1
goroutines = 836
max_procs = 1
os = linux
version = go1.15
serf_lan:
coordinate_resets = 0
encrypted = true
event_queue = 0
event_time = 73
failed = 0
health_score = 0
intent_queue = 0
left = 0
member_time = 16022
members = 44
query_queue = 0
query_time = 1
serf_wan:
coordinate_resets = 0
encrypted = true
event_queue = 0
event_time = 1
failed = 0
health_score = 0
intent_queue = 0
left = 0
member_time = 1554
members = 21
query_queue = 0
query_time = 1
```
### Operating system and Environment details
CentOS 7 in GCE across multiple regions though it usually happens between us-central1 and us-east1.
### Log Fragments
The following are in the logs on the client DC's server:
```
2020-11-13T15:02:37.738Z [ERROR] agent: yamux: keepalive failed: i/o deadline reached
2020-11-13T15:02:37.739Z [ERROR] agent: yamux: Failed to read stream data: read tcp 10.138.0.13:20276->10.142.0.41:8300: use of closed network connection
2020-11-13T15:02:37.741Z [ERROR] agent: yamux: Failed to write header: tls: use of closed connection
2020-11-13T15:02:37.742Z [ERROR] agent.server.rpc: RPC failed to server in DC: server=10.142.0.41:8300 datacenter=gce-us-east1 method=Catalog.NodeServices error="rpc error making call: EOF"
2020-11-13T15:02:37.742Z [ERROR] agent.server.rpc: RPC failed to server in DC: server=10.142.0.41:8300 datacenter=gce-us-east1 method=PreparedQuery.Execute error="rpc error making call: unexpected EOF"
2020-11-13T15:02:37.743Z [ERROR] agent.server.rpc: RPC failed to server in DC: server=10.142.0.41:8300 datacenter=gce-us-east1 method=Catalog.NodeServices error="rpc error making call: EOF"
2020-11-13T15:02:37.744Z [ERROR] agent.server.rpc: RPC failed to server in DC: server=10.142.0.41:8300 datacenter=gce-us-east1 method=PreparedQuery.Execute error="rpc error making call: unexpected EOF"
2020-11-13T15:02:37.745Z [ERROR] agent.server.rpc: RPC failed to server in DC: server=10.142.0.41:8300 datacenter=gce-us-east1 method=Catalog.NodeServices error="rpc error making call: EOF"
2020-11-13T15:02:37.745Z [ERROR] agent.server.rpc: RPC failed to server in DC: server=10.142.0.41:8300 datacenter=gce-us-east1 method=Catalog.NodeServices error="rpc error making call: EOF"
2020-11-13T15:02:37.746Z [ERROR] agent.server.rpc: RPC failed to server in DC: server=10.142.0.41:8300 datacenter=gce-us-east1 method=PreparedQuery.Execute error="rpc error making call: EOF"
... repeated 100+ times
```
The server/destination DC's server has the following logs:
```
2020-11-13T15:02:37.775Z [ERROR] agent.server: yamux: Failed to write body: write tcp 10.142.0.41:8300->10.138.0.13:20276: use of closed network connection
2020-11-13T15:02:37.779Z [ERROR] agent.server.rpc: multiplex conn accept failed: conn=from=10.138.0.13:20276 error="session shutdown"
```
The originating client has the following logs:
```
2020-11-13T15:02:37.771Z [ERROR] agent.client: RPC failed to server: method=PreparedQuery.Execute server=10.138.0.13:8300 error="rpc error making call: rpc error making call: unexpected EOF"
2020-11-13T15:02:37.774Z [ERROR] agent.client: RPC failed to server: method=Catalog.NodeServices server=10.138.0.13:8300 error="rpc error making call: rpc error making call: EOF"
```
Contributor guide
Research direction
Start with the yamux keepalive failure and the agent.server.rpc messages in the supplied client and destination logs, then compare them with the originating client RPC errors. Reproduction is currently unknown, so investigate the cross-DC session shutdown and the later DNS query latency. Done means establishing the failure sequence and a reproducible cause or clearly documenting why the cache metrics diverge.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- gcp, go, linux
- Domain
- backend, distributed-systems, networking
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 25/100