The disk space of the backup node is full, the master node is running normally, but the registration from the master node fails
- Dominant language
- Go
- Stars
- 30.1k
- Forks
- 4.6k
- Avg merge
- 1d 18h
- Merged PRs (30d)
- 39
Description
#### Overview of the Issue
The disk space of the backup node is full, the master node is running normally, but the registration from the master node fails.
The behavior I expect is that when there is a problem with the standby node, it should be normal to register through the master node, rather than when the standby node is abnormal, the registration function of the cluster cannot be used.
### Consul info for both Client and Server
consul --version
```
Consul v1.12.2
Revision 19041f20
```
### Operating system and Environment details
Rocky Linux release 8.6
### Scenes
When there was a problem with my standby node, I registered the service through the primary node, but found that the registration was stuck, and the following error appeared in the log.
register:
```
# test-payload.json
{
"Datacenter": "dc1",
"ID": "10e4a748-2192-161a-0510-9bf59fe950b6",
"Node": "x.x.x.x",
"Address": "x.x.x.x",
"Service": {
"ID": "node-x.x.x.x",
"Service": "node-x.x.x.x",
"Address": "x.x.x.x",
"Port": 9100,
"Meta": {
"my-label-key": "my-label-value"
}
},
"SkipNodeUpdate": false
}
curl --request PUT --data @test-payload.json http://x.x.x.x:8500/v1/catalog/register
^
this will get stuck...
```
### Log Fragments
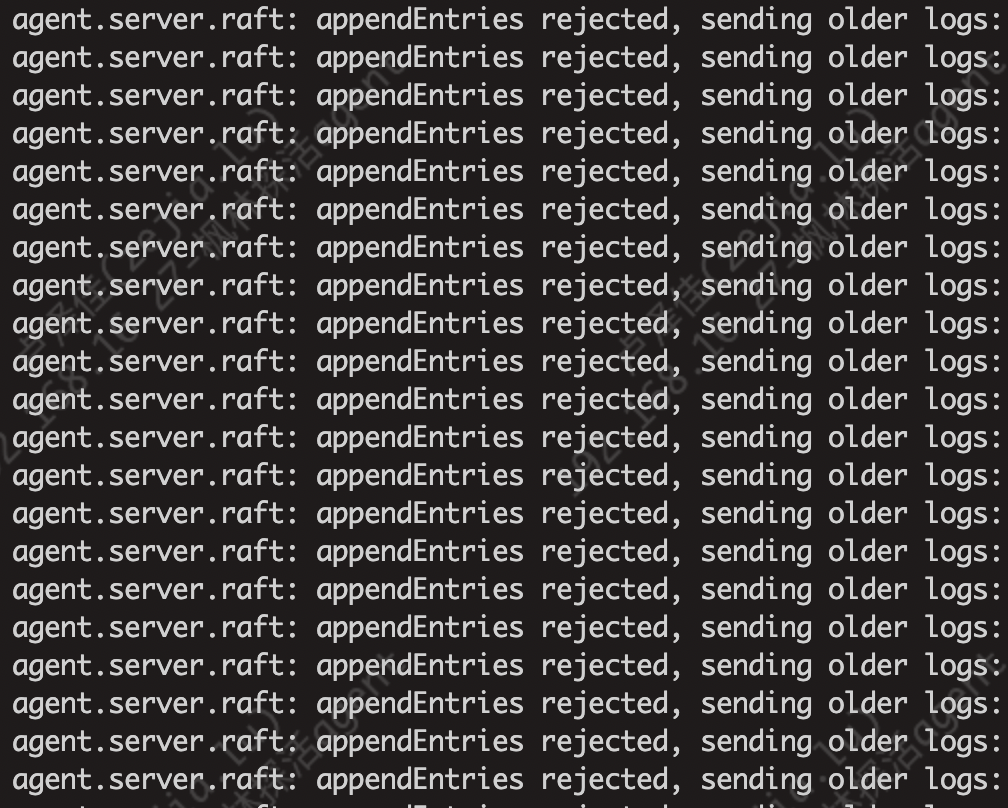
leader:
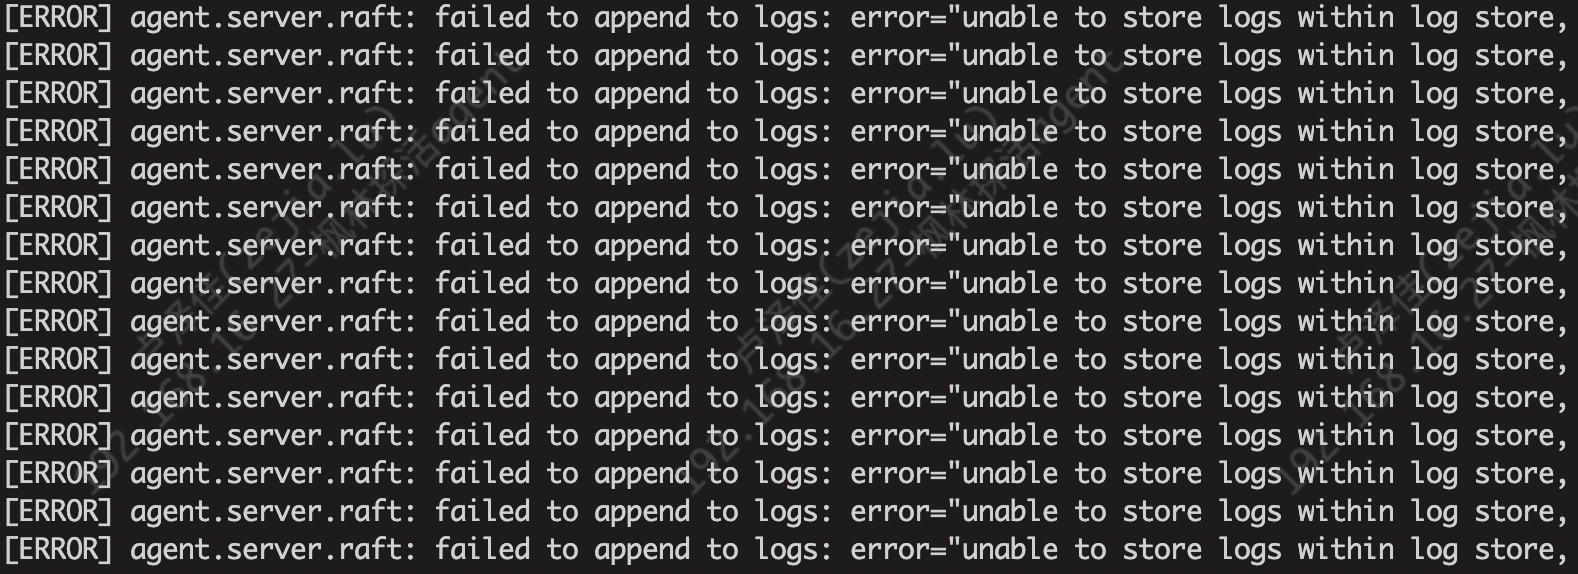
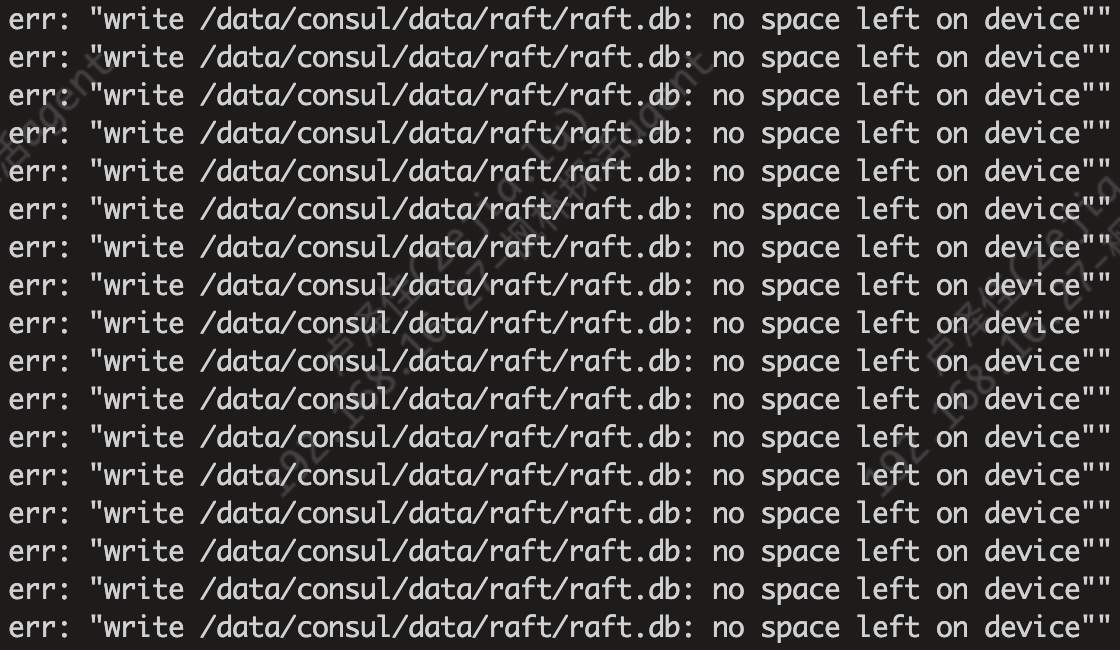
follower:
### My problem is as follows:
Is there a way to register normally through the primary node when the standby node is abnormal? After the standby node is normal, the leader and standby nodes perform data synchronization again, and the data consistency has been reached
Contributor guide
Research direction
Start by reproducing the hanging PUT request to /v1/catalog/register with the provided test-payload.json while the standby node has a full disk, then compare the leader and follower log fragments. Done should mean registration through the primary node completes normally despite the standby-node failure, with synchronization able to resume after recovery.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- go
- Domain
- api, distributed-systems
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 30/100