google-research / google-research/google-research
[depth_from_video_in_the_wild] Convolution kernel regularization
- Dominant language
- Jupyter Notebook
- Stars
- 38.8k
- Forks
- 8.5k
- PR merge metrics
- No merged PRs in 30d
Description
Hi @gariel-google,
first of all thanks for your great work, also with [depth_and_motion_learning]. Upon porting this model to tf2, I've stumbled upon the following issue and it would be very kind if you could help me with that.
In [train.py line 64](https://github.com/google-research/google-research/blob/b12b5753dc0870af2e3c30a0ac1d0adfb3da0754/depth_from_video_in_the_wild/train.py#L64) the default weight regularization is set to 1e-2, so it seems to be active by default. Also in the CVF [paper](https://openaccess.thecvf.com/content_ICCV_2019/papers/Gordon_Depth_From_Videos_in_the_Wild_Unsupervised_Monocular_Depth_Learning_ICCV_2019_paper.pdf) it is stated
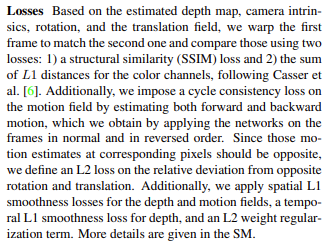
that a l2 regularization term is used. Digging deeper in the code, special care is taken where the l2-weights are applied:
- In the Resnet encoder, the parameter is ignored.
- For the depth decoder, it is applied to each Conv2D and Conv2DTranspose layer.
- For the motion network, we apply it in the enocder, decoder, and refinements in the v2-variants, but only to the encoder in the v1-variants.
If I load the [Cityscapes + KITTI checkpoint](https://www.googleapis.com/download/storage/v1/b/gresearch/o/depth_from_video_in_the_wild%2Fcheckpoints%2Fcityscapes_kitti_learned_intrinsics.zip?generation=1566493762028542&alt=media) in my new implementation and train with the same l2-weight, I get a quite high l2-loss. Additionally, in your reference training code I didn't find a call to `tf.GraphKeys.REGULARIZATION_LOSSES`, so I'm now wondering if this l2-regularization is really active.
Thank you already in advance
xerxesr
Contributor guide
Research direction
Start in depth_from_video_in_the_wild/train.py at line 64 and trace how the configured L2 weight reaches the ResNet encoder, depth decoder, and motion network variants. Check the reference training code for use of tf.GraphKeys.REGULARIZATION_LOSSES and compare behavior with the linked Cityscapes + KITTI checkpoint. Done means establishing whether the regularization is active and documenting the expected loss behavior or required correction.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- python, tensorflow
- Domain
- machine-learning
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Mostly clear
- Newbie friendliness
- 25/100