Backpressure: overly susceptible to temporary issues
- Dominant language
- Python
- Stars
- 44.8k
- Forks
- 4.9k
- Avg merge
- 22h 21m
- Merged PRs (30d)
- 586
Description
### Environment
SaaS (https://sentry.io/)
### Steps to Reproduce
Over the last 30 days, we've experienced ~265 instances where backpressure has been marked as unhealthy due to a connection timeout when checking the health of a redis or rabbitmq cluster: https://cloudlogging.app.goo.gl/KNZDAduqrHWQn5At7

Each of these come with a corresponding pause and delay in ingestion:
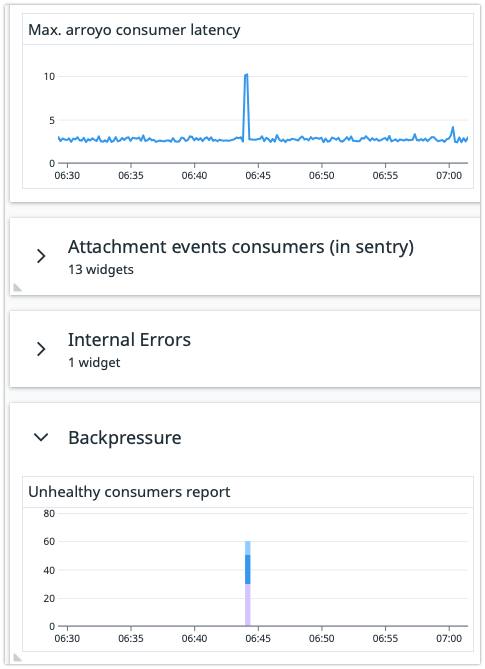
1 timeout seems to trigger about 15s of ingestion latency.
There can also be instances where multiple trigger in succession, which seems to be enough to trigger a backlog large enough that it may page SRE while it burns down the backlog:

### Expected Result
Some possible improvements we can make:
* Add some retry functionality to avoid flakes
* Require multiple events in a row to trigger the unhealthy state
* Have backpressure fail open instead of closed (could have negative impact if the failures are caused by a real outage of a cluster).
I would probably start with adding retries on failure as it seems like the simplest thing that can work.
### Actual Result
Backpressure pauses ingestion from a single failure.
### Product Area
Ingestion and Filtering
### Link
_No response_
### DSN
_No response_
### Version
_No response_
Contributor guide
Assessment
This issue has not been assessed yet.