facebookresearch / facebookresearch/sam3
SAM3 → ONNX → Triton Inference Server: full image-model deployment (text, box + cross-crop exemplars, interactive PVS)
- Dominant language
- Python
- Stars
- 11.7k
- Forks
- 1.8k
- PR merge metrics
- No merged PRs in 30d
Description
Sharing a deployment path that I couldn't find elsewhere in the issues here: **SAM3's image model exported to ONNX and served on NVIDIA Triton Inference Server**, with the full prompting surface exposed as runtime inputs.
**https://github.com/ilanmotiei/sam3-triton** (MIT)
Several excellent ONNX/TensorRT exports already exist (#224, #159). What this adds is the **serving layer** — real ONNX graphs on Triton's ONNX backend with `config.pbtxt` and ensembles, rather than a python-backend wrapper around the PyTorch code — plus the parts of the image model that usually get dropped in an export.
### The split
```
images_u8[1,3,H,W] ─► sam3_unified_encoder ─► 7 vision tensors ┐
token_ids[1,32] ────► sam3_text ────────────► 3 text tensors ─┼─► sam3_decoder ─► sam3_postprocess ─► RLE
box / concept exemplars ─► gate ────────────► 3 tensors ───────┘
```
- The ViT backbone (~1.9 GB) runs **once per image**; every prompt is a cheap runtime input on the grounding head.
- One backbone serves **both** heads — the grounding neck and the PVS (interactive) neck — instead of shipping two ~1.9 GB encoders.
- SAM3's BPE tokenizer can't be represented in ONNX, so it stays client-side and the ensemble takes `token_ids`. Since it pads to 32, every text tensor is fixed-shape — **no dynamic axes anywhere**.
### What it covers
| | |
|---|---|
| **text prompts** | open-vocabulary, prompt is a runtime input |
| **box exemplars** | positive *and* negative, in the same image |
| **cross-crop concepts** | encode an appearance on crop A, reuse it on crop B (see below) |
| **multi-keyword** | encode once, decode per keyword server-side |
| **interactive (PVS)** | point / box / mask prompts, plus automatic mask generation |
### The cross-crop concept split
This one was the interesting part. In `sam3_decoder`, the geometry encoder lives *inside* the graph and pools the **current** image's features at the box — so a box exemplar is a pointer into the image being segmented, and a box from crop A prompts with garbage on crop B.
Splitting `forward_grounding` at the boundary where `geo_feats` is consumed turns the concept into a **portable tensor**:
```
sam3_concept_encoder : 7 vision + boxes -> concept_tokens[18,1,256]
sam3_decoder_ct : 7 vision + text + tokens -> the same head outputs
```
Feeding the encoder's output into `sam3_decoder_ct` reproduces the original decoder **bit-for-bit on the same image** (torch `max|diff| = 0`, 200/200 query agreement). The tokens are image-independent once produced, so you can bank a concept and reuse it on any raster later.
### Results
Real output on the bundled sample tile (1008×1008), reproducible with `examples.py`:
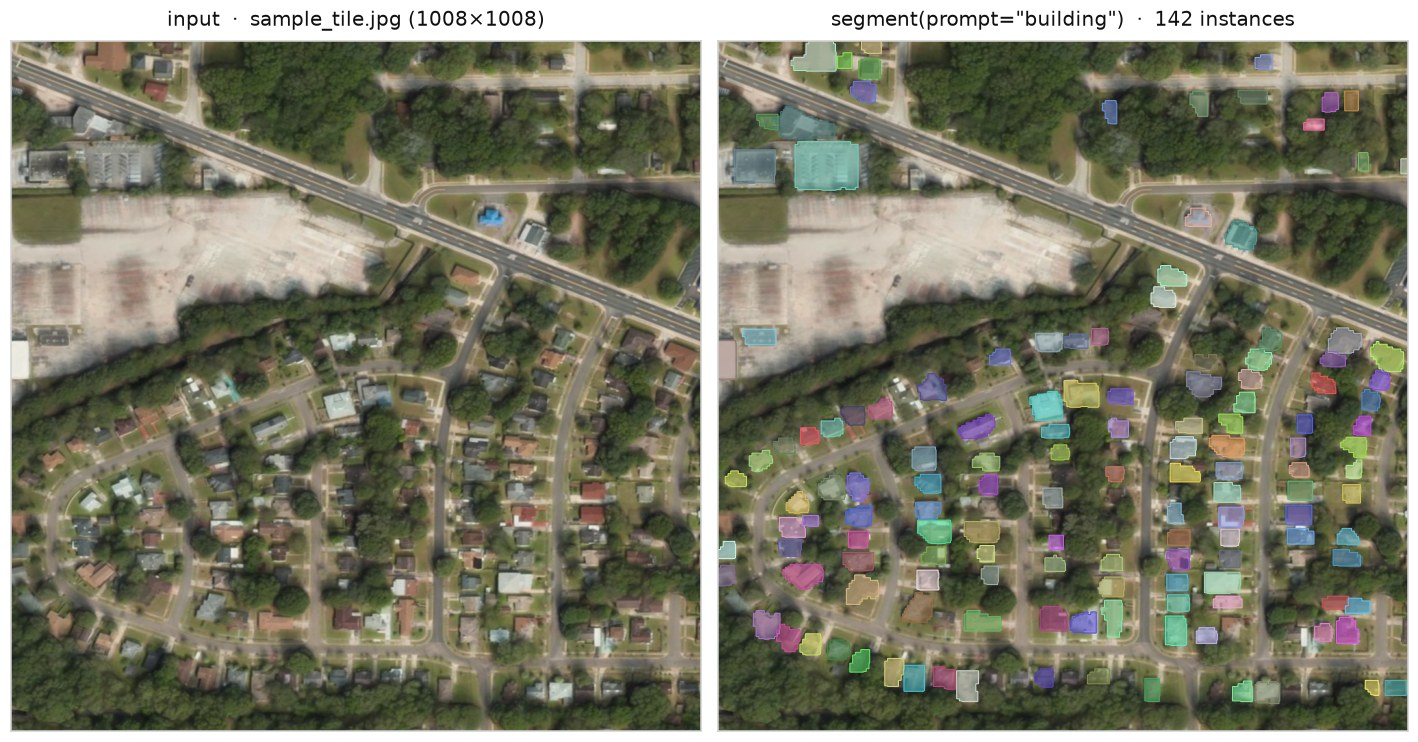
`segment(tile, "building")` → 142 instances.
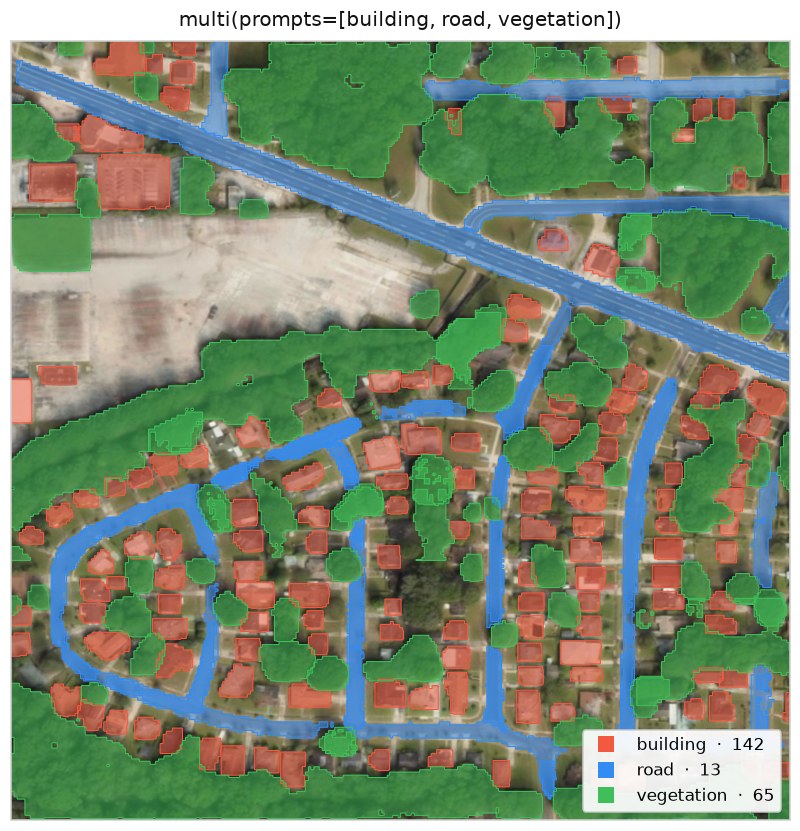
`multi(tile, ["building", "road", "vegetation"])` → 142 / 13 / 65, one vision pass.
### Export gotchas that might save someone time
- **`aten::view_as_complex`** — the vitdet RoPE uses complex rotary embeddings ONNX can't represent. `sam3_rope_patch.py` swaps in an algebraic real/imag rotation.
- **`aten::_pin_memory` NYI** in the fake-tensor tracer — made identity (value-neutral host transfer).
- **`GuardOnDataDependentSymNode`** in the decoder — forcing the static-cache path avoids the assert-only guards.
- **The 0-box/0-point dummy prompt** exports to a rank-mismatched `Add` that ORT rejects; passing one fully-masked box+point keeps text-only results identical.
### The Python client
The repo also ships `sam3_triton_client`, so you're not hand-rolling gRPC tensor plumbing. It runs the BPE tokenizer, frames the image, and decodes the server's condensed RLE payload back into masks.
```bash
pip install ./client
```
```python
from sam3_triton_client import Sam3Client
c = Sam3Client("localhost:8001") # gRPC; connect_timeout= blocks until models load
```
Everything returns a `pandas.DataFrame` with **`box`** (`[x1,y1,x2,y2]` in the *original* image's pixels), **`score`**, and a full-frame `HxW` **`mask`** — so results drop straight into pandas/numpy without any coordinate bookkeeping on your side.
**Text prompt** — all instances of a concept:
```python
df = c.segment("sample_tile.jpg", "building")
```
```text
box score mask
0 [107.0, 0.0, 173.0, 44.0] 0.796 <1008x1008 px, 2277 fg>
1 [194.0, 59.0, 231.0, 90.0] 0.785 <1008x1008 px, 941 fg>
... 142 rows total
```
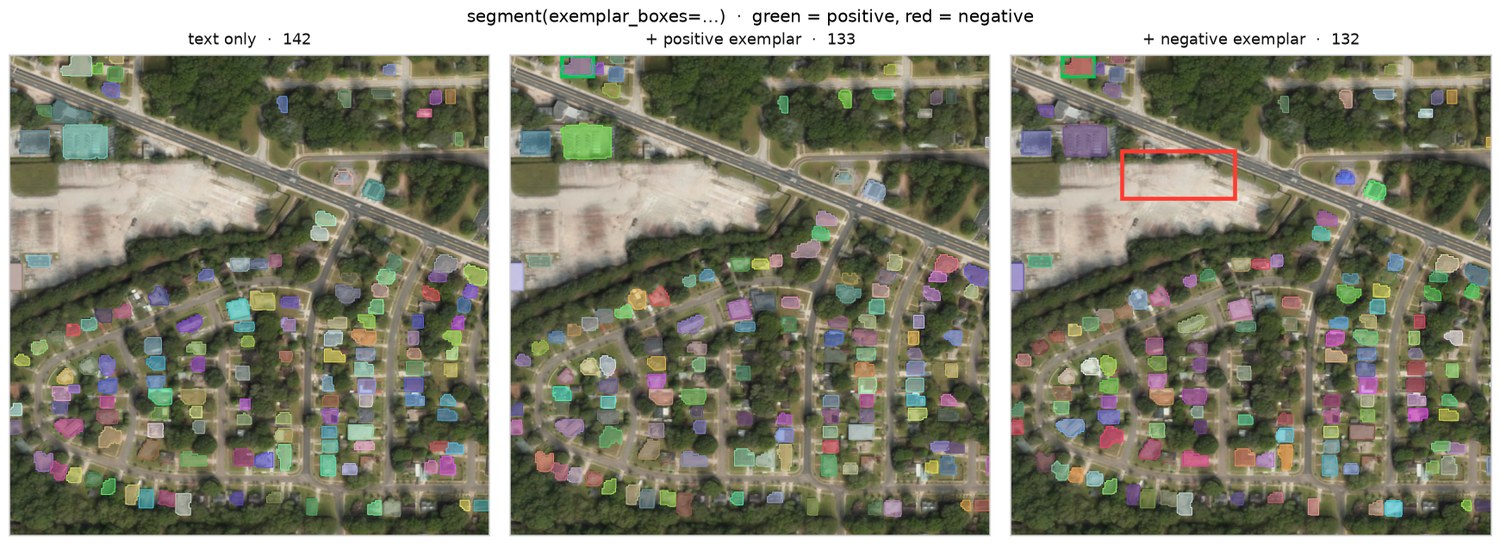
**Box exemplars** — steer the concept with examples in the same image. Not a spatial filter: a positive box means "things that look like this", a negative one suppresses an appearance.
```python
c.segment(tile, "building", exemplar_boxes=[POS]) # 133
c.segment(tile, "building", exemplar_boxes=[POS, NEG], exemplar_labels=[1, 0]) # 132
c.segment(tile, None, exemplar_boxes=[POS]) # pure visual query, no text
```
**Multi-keyword** — one encode, a `keyword` column on the way back:
```python
df = c.multi(tile, ["building", "road", "vegetation"]) # 142 / 13 / 65
```
**Portable concepts** — encode an appearance once, reuse it anywhere, including across processes:
```python
concept = c.encode_exemplars(cropA, boxes=[[120, 80, 210, 160]])
open("concept.npz","wb").write(concept.to_bytes()) # bank it
df = c.segment(cropB, prompt=None, concept=concept) # find it on a different crop
```
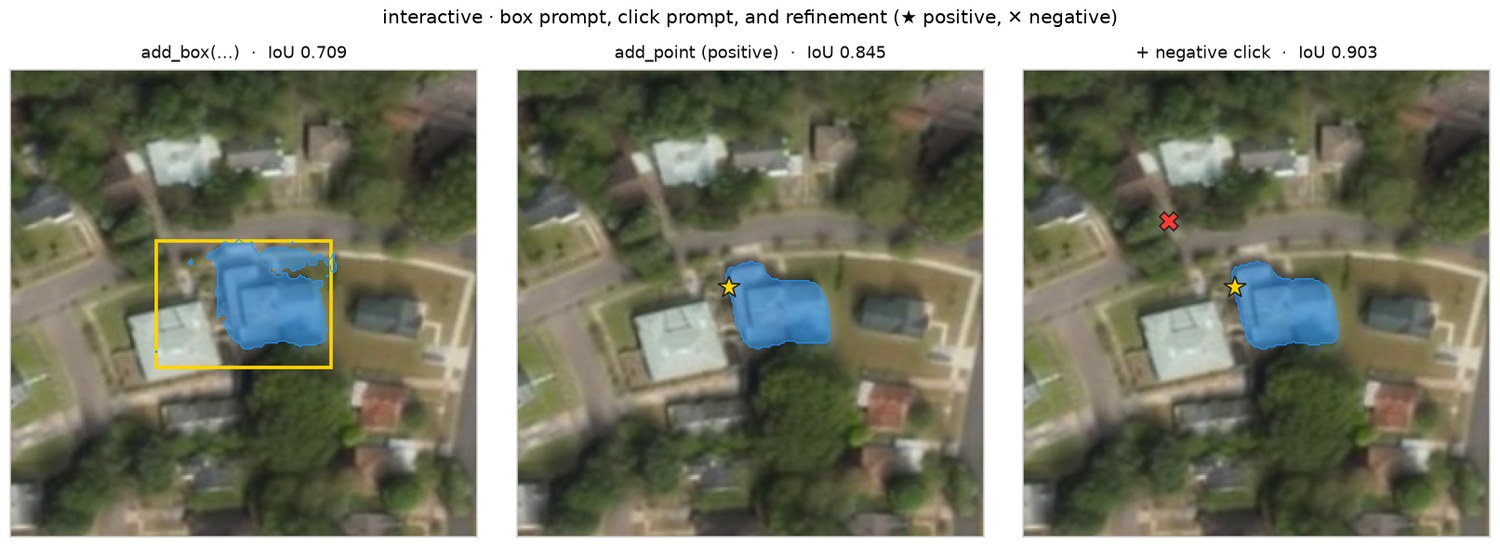
**Interactive session** — encode once, then cheap prompts; each call returns 3 candidates ranked by predicted IoU:
```python
s = c.interactive(tile)
s.add_point((504, 504)) # positive click -> best IoU 0.845
s.add_point((470, 470), positive=False) # negative refinement -> best IoU 0.903
s.add_box([470, 480, 560, 545]) # box prompt -> best IoU 0.709
s.add_mask(df.iloc[0]["mask"]) # seed from a segment() result, then refine by hand
s.undo(); s.reset() # reset keeps the cached embedding
df = s.everything(points_per_side=16) # automatic mask generation -> 47 objects
```
Other conveniences worth knowing:
- **Any input dtype.** `uint16`/float rasters are percentile-stretched to 8-bit (robust to hot pixels), grayscale is replicated to RGB, alpha dropped — so 12-bit satellite tiles work without pre-conversion.
- **Client-side dedup.** SAM3 grounding is set prediction with **no server-side NMS**, so at low thresholds it emits masks nested inside larger ones. `dedup=` (default 0.85) suppresses those by overlap coefficient `inter/min(area)` — plain IoU-NMS misses them because the union stays large.
- **Per-request hyperparameters.** `score_thr` / `mask_thr` / `max_det` are optional ensemble inputs, so you tune without redeploying: on the sample tile `score_thr` 0.2/0.3/0.5/0.7 → 153/142/93/17 instances.
- **Connection handling.** round-robin LB (point it at a headless Service to spread across pods), gRPC-native retries for transient transport errors only, and `connect_timeout` to block through a cold start — a full SAM3 load is ~60–90 s.
### Caveats
- **Image model only** — no video, tracking, or memory propagation.
- **fp32.** The ViT correlations overflowed fp16 in my testing.
- Fixed **1008** image input and **32**-token text; other sizes need a re-export.
- **No weights shipped** — the repo is tooling; you run the export against your own checkpoint, and SAM3 itself stays under Meta's license.
Happy to answer questions on the split or the Triton configs. Disclosure: this is my repo.
Contributor guide
Research direction
This issue presents the external sam3-triton repository rather than naming a change in facebookresearch/sam3. Start with its examples.py, Triton config.pbtxt files, sam3_rope_patch.py, and sam3_triton_client; the payload does not define a target file, test, or acceptance criteria for work in this repository.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- python
- Domain
- ai, devops
- Issue type
- Feature
- Difficulty
- 5/5
- Estimated time
- Over a week
- Activity status
- Quiet
- Clarity
- Needs clarification
- Newbie friendliness
- 25/100