facebookresearch / facebookresearch/SlowFast
Cannot reproduce the result on AVA
- Dominant language
- Python
- Stars
- 7.4k
- Forks
- 1.3k
- PR merge metrics
- No merged PRs in 30d
Description
Hi, thank you for your great code base.
Now I'm trying to reproduce the result on AVA claimed in paper and tech report. However, I cannot reproduce the result.
I chose [configs/AVA/c2/SLOWFAST_32x2_R101_50_50.yaml](https://github.com/facebookresearch/SlowFast/blob/master/configs/AVA/c2/SLOWFAST_32x2_R101_50_50.yaml) configuration file for training.
The modifications I did to this config file are: (**Here, the commented are original settings**.)
```yaml
TRAIN:
ENABLE: True #False
DATASET: ava
BATCH_SIZE: 80 #16
EVAL_PERIOD: 2 # 1
CHECKPOINT_PERIOD: 1
AUTO_RESUME: True
CHECKPOINT_FILE_PATH: path to pretrain model downloaded from the third entry in this table(https://github.com/facebookresearch/SlowFast/blob/master/MODEL_ZOO.md#ava)
CHECKPOINT_TYPE: caffe2 # pytorch
DETECTION:
ENABLE: True
ALIGNED: True #False
#SOLVER:
# MOMENTUM: 0.9
# WEIGHT_DECAY: 1e-7
# OPTIMIZING_METHOD: sgd
SOLVER:
BASE_LR: 0.1
LR_POLICY: steps_with_relative_lrs
STEPS: [0, 20, 30]
LRS: [1, 0.1, 0.01, 0.001]
MAX_EPOCH: 40
MOMENTUM: 0.9
WEIGHT_DECAY: 1e-7
WARMUP_EPOCHS: 5
WARMUP_START_LR: 0.000125
OPTIMIZING_METHOD: sgd
```
As you can see, I modified the learning policy from `cosine` to `steps_with_relative_lrs`, which is stated in paper, with reference to the settings in https://github.com/facebookresearch/SlowFast/blob/a8a47ced376a681e76d8b904e7be76d67fe999b3/configs/AVA/SLOWFAST_32x2_R50_SHORT.yaml#L52-L62
However, the result is not good.
Below is the picture of training loss and mAP on val set,
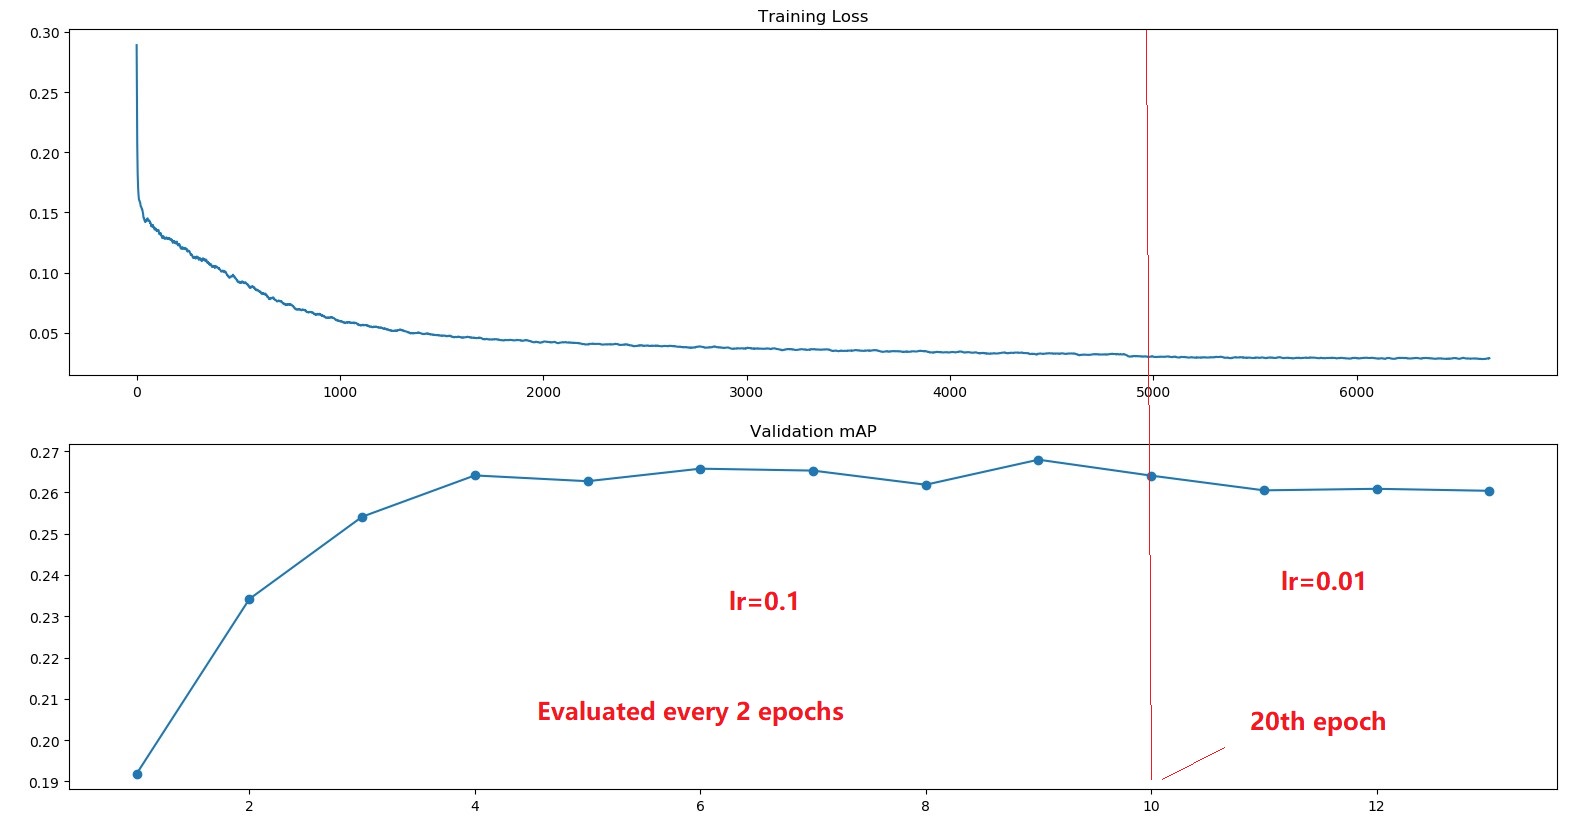
From the picture, we can find that the mAP on Val set saturates around `26 .0` quickly and cannot reach the value (**`29.0`**) stated in paper.
How do you think about this, is this because of the `STEPS` parameter I set that cause overfitting?
Thank you!
Contributor guide
Assessment
This issue has not been assessed yet.