facebookresearch / facebookresearch/ImageBind
ImageBind with SAM Simple Demo: Segment with Different Modalities
- Dominant language
- Python
- Stars
- 9.1k
- Forks
- 842
- PR merge metrics
- No merged PRs in 30d
Description
Thanks a lot for release such an amazing work!
We implement a simple and interesting demo by combing ImageBind with SAM here: [ImageBind-SAM](https://github.com/IDEA-Research/Grounded-Segment-Anything/tree/main/playground/ImageBind_SAM) which can segment things with different modalities, and the project is still under develop
This basic idea is followed with [IEA: Image Editing Anything](https://github.com/feizc/IEA) and [CLIP-SAM](https://github.com/maxi-w/CLIP-SAM) which generate the referring mask with the following steps:
- Step 1: Generate auto masks with `SamAutomaticMaskGenerator`
- Step 2: Crop all the box region from the masks
- Step 3: Compute the similarity with cropped images and different modalities
- Step 4: Merge the highest similarity mask region
And the result is shown as:
| Input Model | Modality | Generate Mask |
|:----:|:----:|:----:|
|  | [car audio](https://github.com/IDEA-Research/Grounded-Segment-Anything/blob/main/playground/ImageBind_SAM/.assets/car_audio.wav) | 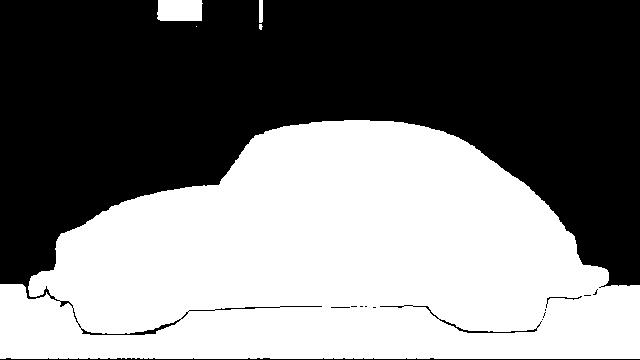 |
|  | "A car" | 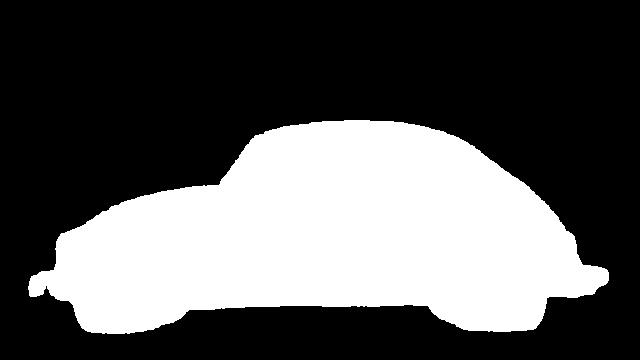 |
And the threshold for each box will influence a lot on the final result, we will do more test on it!
Contributor guide
Assessment
This issue has not been assessed yet.