HTTP 2 connection draining is non-graceful for low-volume listeners
- Dominant language
- C++
- Stars
- 28.9k
- Forks
- 5.6k
- Avg merge
- 1d 20h
- Merged PRs (30d)
- 428
Description
*Title*: *HTTP 2 connection draining is non-graceful for low-volume listeners*
### Description:
When a listener enters into a draining state _either_ due to a hot-restart or an LDS update, it __should not__ accept new requests but should let existing requests finish gracefully. There is a drain-time limit that, when reached will terminate any open connections non-gracefully.
For HTTP 2, putting a connection into a draining state should be equivalent with Envoy sending a `GOAWAY` frame on the connection. This signals that no new streams should be created on the connection, but existing streams are allowed to finish. Assuming a well-behaved client (one that respects the `GOAWAY`), this should mirror the desired behavior for connection draining. However, Envoy does not send a `GOAWAY` proactively when the drain-time begins. Instead, Envoy issues a `GOAWAY` _after_ the next request made on the connection is _completed_. Represented visually, this would look like:
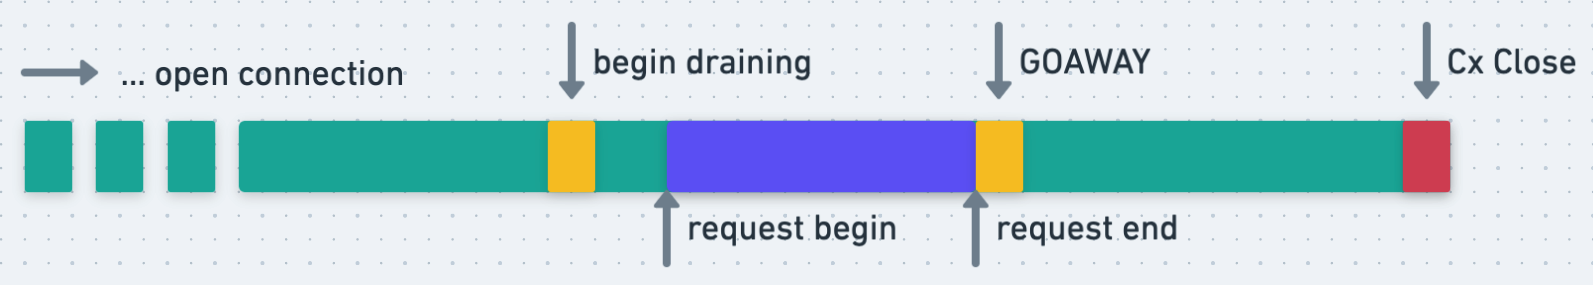
With appropriately long drain-time for your traffic and a sufficiently busy listener, this delayed `GOAWAY` does not generally lead to issues. However, if the listener is processing a low volume of long-requests, then it is possible to find ourselves in the following scenario:
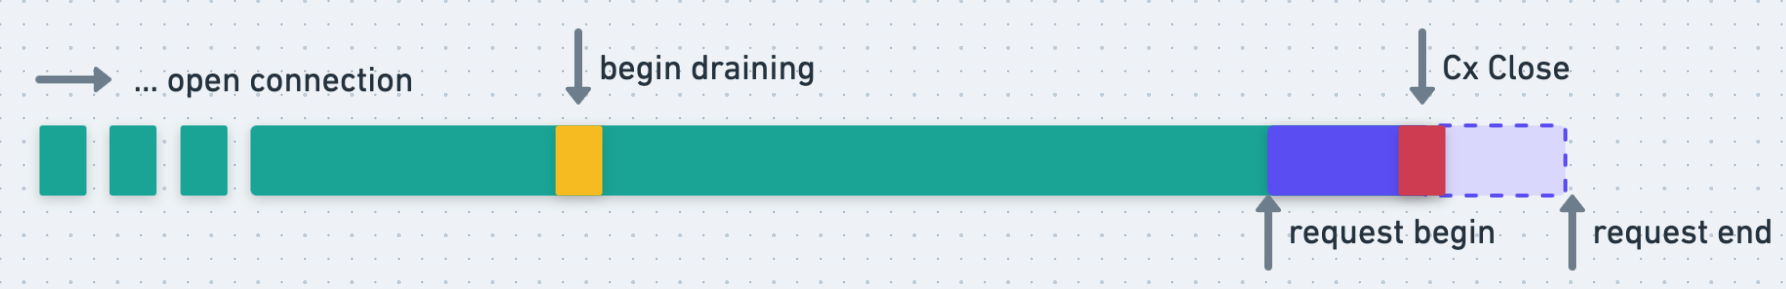
In this scenario the request does not begin until near the end of the drain-time window. Because the `GOAWAY` signal is not sent until the request _ends_. This results in a request being interrupted as the connection is non-gracefully closed -- non-graceful defined as 1) without a `GOAWAY` and 2) with in-flight requests.
An interrupted request is logged into the access log with the `DC` flag and will return a `503` response. If the downstream is another Envoy instance, then the downstream will have an access log with a `UC` flag.
__I would expect__ that Envoy would issue a `GOAWAY` (`NO_ERROR` error-code) at the beginning of the drain-period (without the external tigger of a request) as this already matches the desired behavior of Envoy's connection-draining. I _suspect_ the current implementation to be an artifact of how connections would be closed for persistent HTTP 1.
### Repro steps:
This has been reproduced in our internal integration-test suite, but can be reproduced readily with the following:
+ Configure drain-time of 20 seconds
+ Configure parent-shutdown time of 25 seconds
+ Start Envoy
+ Create a client (either H1 or H2) and generate some traffic to ensure established connections
+ Begin a reload or perform an LDS update
+ Issue a request over the same connection that:
+ Begins 10s after the reload/LDS-update was initiated
+ Lasts for 30s (upstream service sleeps 30s before responding)
+ Observe non-graceful connection termination
All tests were done using a concurrency of 1 to ensure a single listener/connection.
Contributor guide
Assessment
This issue has not been assessed yet.