Allow upload endpoint to store an item without processing (OCR/conversion/analysis)
- Dominant language
- Elm
- Stars
- 2.3k
- Forks
- 184
- Avg merge
- 8h 2m
- Merged PRs (30d)
- 4
Description
## Problem
Every upload always goes through the full joex pipeline (`process-item`): archive extract → PDF conversion → text extraction/OCR → preview → text analysis. There is no way for the insertion/upload API to say “just store this; processing is not required (or not required immediately).”
That hurts for large **reference** files — for example Excel workbooks or big merged PDFs — where we mainly need the binary stored and findable as an item, but do **not** need text extraction or analysis.
### Concrete example
Joex spent nearly **3 hours** (`02:55:11`) processing an Excel upload that we only needed stored for reference:
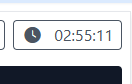
*Joex spent nearly 3 hours processing an Excel upload that we only needed stored.*
## Current behavior
1. Upload stores file bytes.
2. A `process-item` (or `multi-upload-process`) job is **always** enqueued.
3. The item only becomes UI-visible (`Created`) after processing finishes (or fails on last retry).
Closest existing knobs:
- upload `priority` (high/low)
- `skipDuplicates`
- global joex OCR / NLP config
None of these provide **per-upload store-only**.
## Desired behavior
A per-upload flag that:
1. Creates a **visible item + attachments immediately**
2. Applies given metadata (folder, tags, direction, language, …)
3. **Skips** conversion / OCR / text extraction / preview / analysis
4. Allows optional full processing later via the existing reprocess APIs:
- `POST /api/v1/sec/item/{itemId}/reprocess`
- `POST /api/v1/sec/items/reprocess`
## Proposed API strawman
Add optional `process` (boolean, **default `true`**) to `ItemUploadMeta`.
- `process: true` (default) — current behavior
- `process: false` — store-only path: create visible item, skip heavy stages
Available on secured, open/source, and integration upload endpoints; documented in the upload API docs.
### Implementation sketch (for discussion)
Keep enqueueing a lightweight `process-item` job so duplicate-check, `CreateItem`, and `SetGivenData` still run, then short-circuit the heavy stages in joex when `process: false`, and mark the item `Created`. Reuse existing reprocess for “process later.”
## Out of scope (v1)
- Source/tag-based auto-skip (related to #1766)
- Finer-grained stage flags (e.g. skip OCR only)
- Large-file streaming / upload size improvements (#1819)
## Related
- #1766 — Skip OCR for certain source or tag
- #1819 — Very large documents cannot be uploaded
- Recent upload metadata work: optional `priority`, immediate `fileKeys` on submit
Happy to implement this if the direction looks good.
Contributor guide
Research direction
Start with ItemUploadMeta and the secured, open/source, and integration upload entry points, then trace the process-item and multi-upload-process jobs. Compare the proposed process flag with the existing reprocess APIs and upload API documentation; done means store-only uploads create visible items with metadata, skip heavy processing, and retain later reprocessing.
Written by the indexing model from the issue text.
Assessment
- Domain
- api, backend, documentation
- Issue type
- Feature
- Difficulty
- 5/5
- Estimated time
- Over a week
- Activity status
- Active
- Clarity
- Mostly clear
- Newbie friendliness
- 52/100