dotnet / dotnet/machinelearning-modelbuilder
Help understand results: Show estimate for chance of being above random
- Dominant language
- Dockerfile
- Stars
- 285
- Forks
- 66
- PR merge metrics
- No merged PRs in 30d
Description
**Background**
The "ethics of AI" is increasing in importance, especially in government projects. Tools like Model Builder make building machine learning models very fast and easy which could lead to de-emphasis on testing and validation. Low-performing models have ethical implications in certain cases as it may influence decision making.
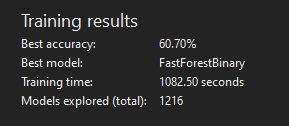
While tracking a potential bug, I am running a random values dataset with only 1000 items (Excel random function for range 0...1). Model Builder reports 60.7% accuracy after a short run which could easily be mistaken as good enough. It probably gets slightly better with time (now 62.22%)
** Suggestion **
Model Builder could report one more metric about the chance of accuracy being above random. It needs someone smarter than me to create the equation, but it probably should be based on number of examples, size of validation data and number of experiments and the range of the results from different experiments.
Or, it could be just reported as low/medium/high based on some experiments with random datasets.
Or, it could be just a warning about low number of examples if the accuracy is relatively low.
**Additional context**
A challenge is how to deal with overfitted data. Adding this metric could create false trust in the results if the metric shows high change of being above random.
[random-dataset.csv](https://github.com/dotnet/machinelearning-modelbuilder/files/7417663/random-dataset.csv)
Contributor guide
No contributing guide indexed for this repository
Assessment
This issue has not been assessed yet.