[Bug] Wrong feature contributions and probabilities for multiclass model in XGBoost4j Scala Spark
- Dominant language
- C++
- Stars
- 28.8k
- Forks
- 8.9k
- Avg merge
- 1d 12h
- Merged PRs (30d)
- 54
Description
### Problem
I'm building a simple multiclass classification model on the Iris dataset and trying to predict feature contributions (i.e. obtain SHAP values).
In a binary classification problem, this works correctly and provides an array of `n` values for the `n` features of the model. However, in this multiclass example I'm obtaining the following contributions:
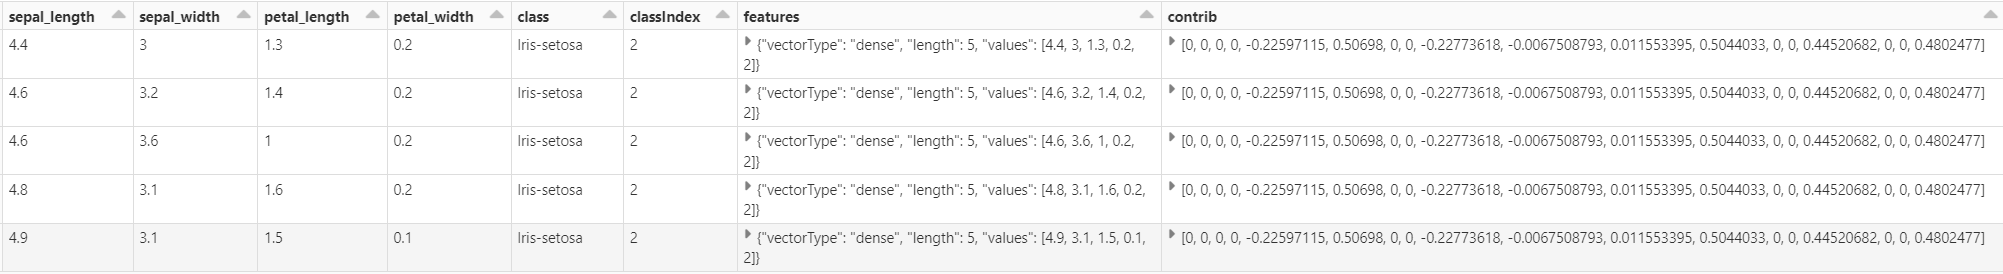
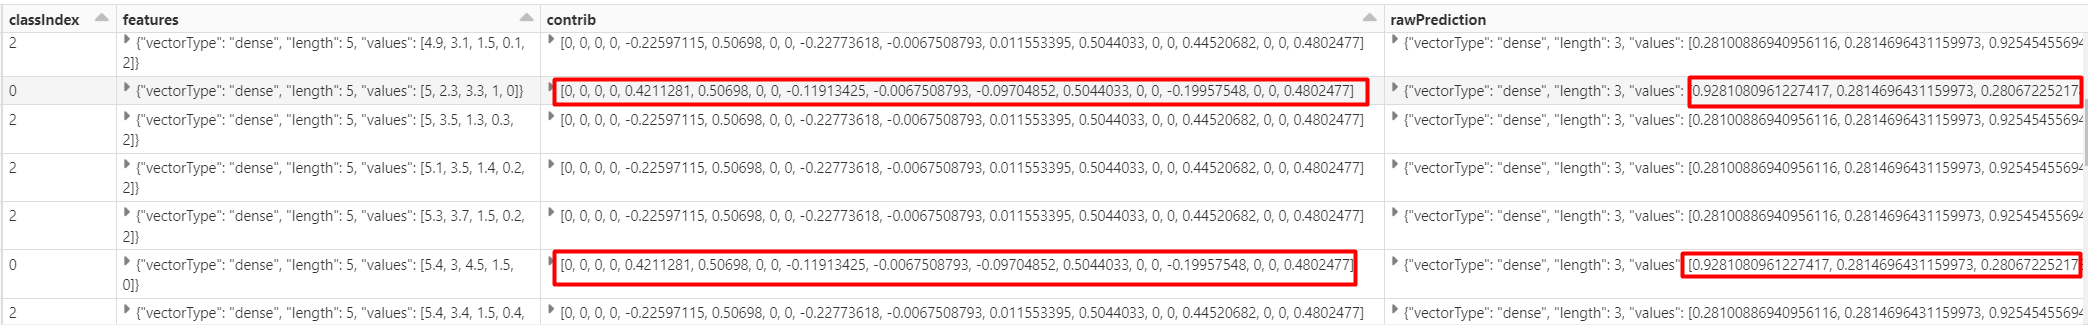
That is, for a model with 4 features and 3 classes I'm obtaining 17 feature contributions + intercept. Not only this, but I also see that the predicted probabilities are exactly the same for every element pertaining to a class, and the same happens with feature contributions, they don't vary per instance:
### Expected result
I would expect the "contrib" column to contain an array of 13 values (4 features * 3 classes + intercept) and instead I'm obtaining 18.
I would also expect the values of the contributions and the predicted probabilities to vary across each instance.
### Steps to reproduce
Below you can find a MWE to reproduce this code:
```scala
import org.apache.spark.ml.feature._
import org.apache.spark.ml.Pipeline
import ml.dmlc.xgboost4j.scala.spark.XGBoostClassifier
import org.apache.spark.sql.types._
val schema = new StructType(
Array(StructField("sepal_length", DoubleType),
StructField("sepal_width", DoubleType),
StructField("petal_length", DoubleType),
StructField("petal_width", DoubleType),
StructField("class", StringType))
)
val data = spark.read
.schema(schema)
.csv("iris.csv")
.na.fill(0)
.toDF("sepal_length", "sepal_width", "petal_length", "petal_width", "class")
val indexer = new StringIndexer().setInputCol("class").setOutputCol("classIndex").setHandleInvalid("error")
val vectorAssembler = new
VectorAssembler()
.setInputCols(Array("sepal_length", "sepal_width", "petal_length", "petal_width", "classIndex"))
.setOutputCol("features")
val xgbParam = Map(
"contrib_prediction_col" -> "contrib",
"features_col" -> "features",
"label_col" -> "classIndex",
"objective" -> "multi:softprob",
"prediction_col" -> "prediction",
"num_class" -> 3,
"max_depth" -> 5,
"seed" -> 42,
"num_workers" -> 4,
"rabbit_timeout" -> 30,
)
val xgbClassifier = new XGBoostClassifier(xgbParam)
val pipeline = new Pipeline().setStages(Array(indexer, vectorAssembler, xgbClassifier))
val Array(trainDF, testDF) = data.randomSplit(Array(0.8, 0.2), seed=42)
val fitted_pipeline = pipeline.fit(trainDF)
fitted_pipeline.transform(testDF).limit(20).show()
```
### Environment
```
Databricks Runtime Version: 9.1 LTS ML (includes Apache Spark 3.1.2, Scala 2.12)
XGBoost4j versions:
- ml.dmlc:xgboost4j_2.12:1.5.2
- ml.dmlc:xgboost4j-spark_2.12:1.5.2
```
Contributor guide
No contributing guide indexed for this repository
Research direction
Start by running the supplied Iris MWE with Spark 3.1.2, Scala 2.12, and XGBoost4j 1.5.2, then inspect the contrib and prediction columns for multiclass output. Done means the contribution array has 13 values and both probabilities and contributions vary by instance, as described in Expected result.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- scala
- Domain
- distributed-systems, machine-learning
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Mostly clear
- Newbie friendliness
- 35/100