[Discussion] The difference between reference paper and coding
- Dominant language
- Python
- Stars
- 28.4k
- Forks
- 3.1k
- PR merge metrics
- No merged PRs in 30d
Description
I have read your conference paper “Singing Voice Separation with Deep U Net Convolutional Networks”, which is very impressive.
In this paper, the U-net your team introduced only process one amplitude spectrum of STFT for one time. The architecture is:
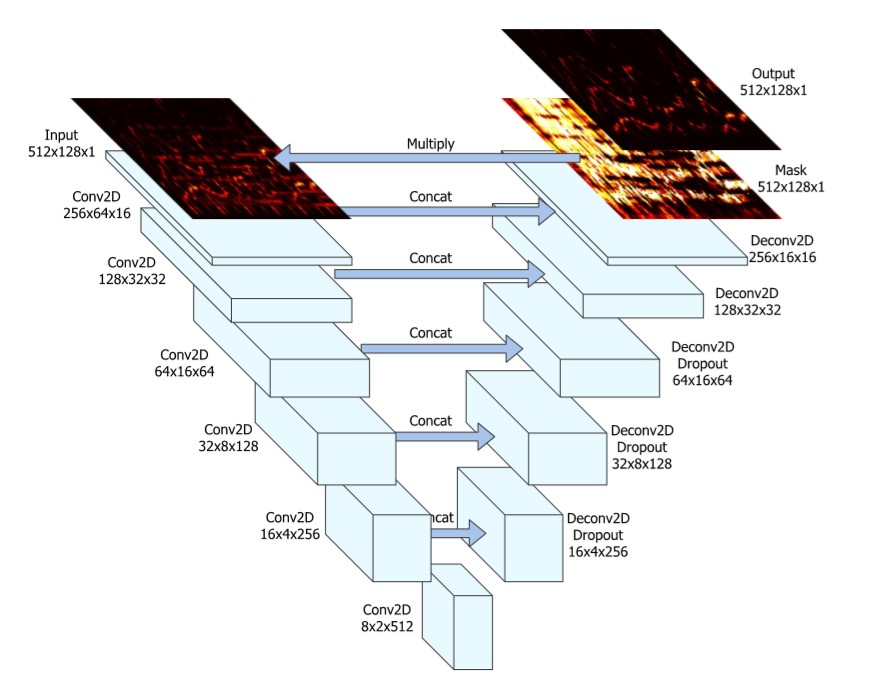
However, when I refer to the code, I find the output has two channels:
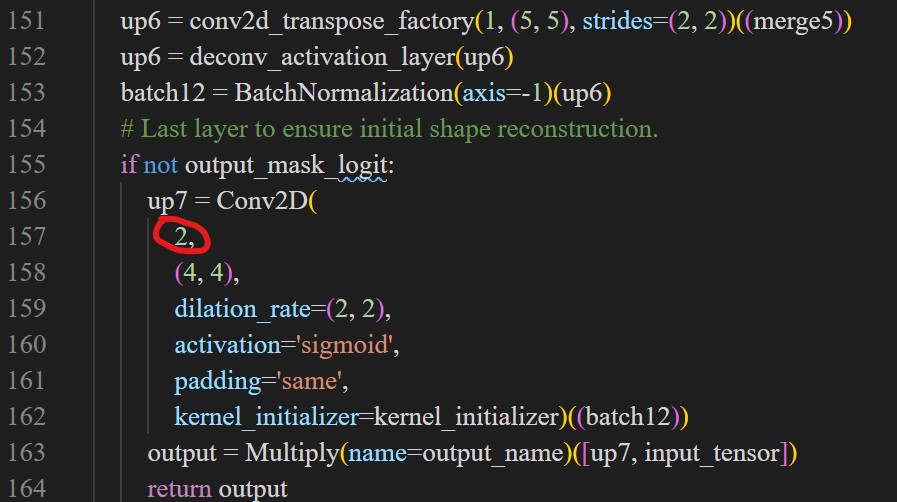
I wander, whether there is a bug in the code, or you have come up with other idea of processing the signal. I have two guesses: (1) the network processes the amplitude and phase spectrum at the same time. (2) the network processes the amplitude of vocal and accompaniment at the same time.
I will be very appreciative if you could give me some guidance or provide other reference papers. Hoping for your reply.
Contributor guide
Assessment
This issue has not been assessed yet.