deepspeedai / deepspeedai/DeepSpeed
Not getting convergence in Bert Large Training.
Nobody has claimed this yet.
- Dominant language
- Python
- Stars
- 43.1k
- Forks
- 5k
- Avg merge
- 4d 15h
- Merged PRs (30d)
- 112
Description
Hey,
I have been trying out Deepspeed for a while, thank you for all the cool features.
I am trying to train a bert large from scratch using 335Million token sequences. After considering gradient accumulation and number of GPU's involved, the effective batch size comes out to be 1920.
The loss graph looks something like this :
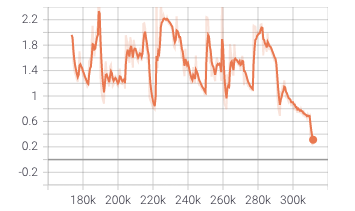
Note that with small batches it converges well, and the loss stays between 0 and 1 but it takes too long and we have more data coming in.
Following is my config :
{
  "fp16": {
    "enabled": true,
    "loss_scale": 0,
    "loss_scale_window": 1000,
    "hysteresis": 2,
    "min_loss_scale": 1
  },
  "zero_optimization": {
    "stage": 1,
    "allgather_partitions": true,
    "allgather_bucket_size": 100000000,
    "overlap_comm": true,
    "reduce_scatter": true,
    "reduce_bucket_size": 100000000,
    "contiguous_gradients": true,
    "cpu_offload": false
  },
  "optimizer": {
    "type": "Lamb",
    "params": {
      "lr": 0.001,
      "weight_decay": 0.01,
      "bias_correction": false,
      "max_coeff": 0.3,
      "min_coeff": 0.01
    }
  },
  "zero_allow_untested_optimizer": true,
  "scheduler": {
    "type": "WarmupLR",
    "params": {
      "warmup_min_lr": 0,
      "warmup_max_lr": 0.0003,
      "warmup_num_steps": 200
    }
  }
}
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
No repository file, test, or entry point is named. Start by reproducing the large-batch training behavior from the supplied DeepSpeed configuration, then compare the optimizer, learning-rate warmup, gradient accumulation, and batch-size settings with the small-batch run; done means identifying a supported configuration or a confirmed convergence defect.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- python
- Domain
- distributed-systems, machine-learning
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 25/100