deepspeedai / deepspeedai/DeepSpeed
[BUG]The inference error is large
Nobody has claimed this yet.
- Dominant language
- Python
- Stars
- 43.1k
- Forks
- 5k
- Avg merge
- 4d 15h
- Merged PRs (30d)
- 112
Description
Describe the bug
The results generated based on DS inference and the results generated by the original model have certain errors, and the results generated by DS inference will be randomly generated later
To Reproduce
Steps to reproduce the behavior:
tokenizer = LlamaTokenizer.from_pretrained(base_model)
model = LlamaForCausalLM.from_pretrained(
    base_model,
    torch_dtype=torch.float16,
)
model = deepspeed.init_inference(
            model=model,
            mp_size=1,
            dtype=torch.float16,
            replace_method="auto",
            replace_with_kernel_inject=True,
            )
instruction = "xxxx"
inputs = "xxxx"
t1 = time.time()
prompt = generate_prompt(instruction, inputs)
inputs = tokenizer(prompt, return_tensors="pt")
input_ids = inputs["input_ids"].to("cuda")
generation_config = GenerationConfig(
	temperature=0.1,
	top_p=0.75,
	top_k=40,
	num_beams=1,
)

with torch.no_grad():
	generation_output = model.generate(
		input_ids=input_ids,
		generation_config=generation_config,
		return_dict_in_generate=True,
		output_scores=True,
		max_new_tokens=1024,
	)
Expected behavior

ds_report output
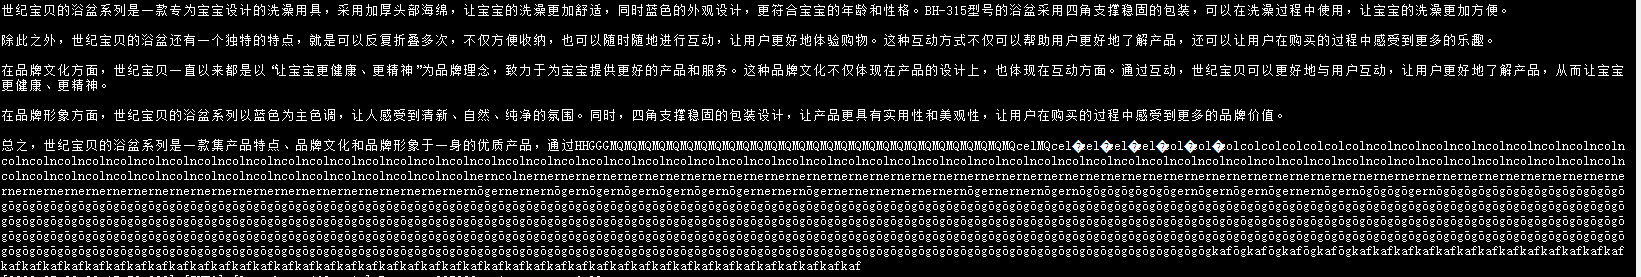
Screenshots
If applicable, add screenshots to help explain your problem.
System info (please complete the following information):
- OS: [e.g. Ubuntu 18.04]
- GPU count and types [e.g. two machines with x2 V100s each]
- (if applicable) what DeepSpeed-MII version are you using
- (if applicable) Hugging Face Transformers/Accelerate/etc. versions 4.28
- Python version 3.8
- Any other relevant info about your setup
Docker context
Are you using a specific docker image that you can share?
Additional context
Add any other context about the problem here.
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
Start by running the supplied LlamaTokenizer, LlamaForCausalLM, and deepspeed.init_inference reproduction with the reported Python and Transformers versions, then compare generated outputs against the original model. Inspect the inference replacement path and its interaction with model.generate. Done means the discrepancy is reproduced and fixed or clearly characterized with a regression test and the required system details.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- python, pytorch
- Domain
- distributed-systems, machine-learning, performance
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 22/100