deepspeedai / deepspeedai/DeepSpeed
[BUG] ds inference succeed for 2 gpus, oom for 4 gpus
Nobody has claimed this yet.
- Dominant language
- Python
- Stars
- 43.1k
- Forks
- 5k
- Avg merge
- 4d 15h
- Merged PRs (30d)
- 112
Description
Describe the bug
I run ds inference. It succeed for 2 gpus, oom for 4 gpus.
To Reproduce
cd DeepSpeedExamples/inference/huggingface/text-generation
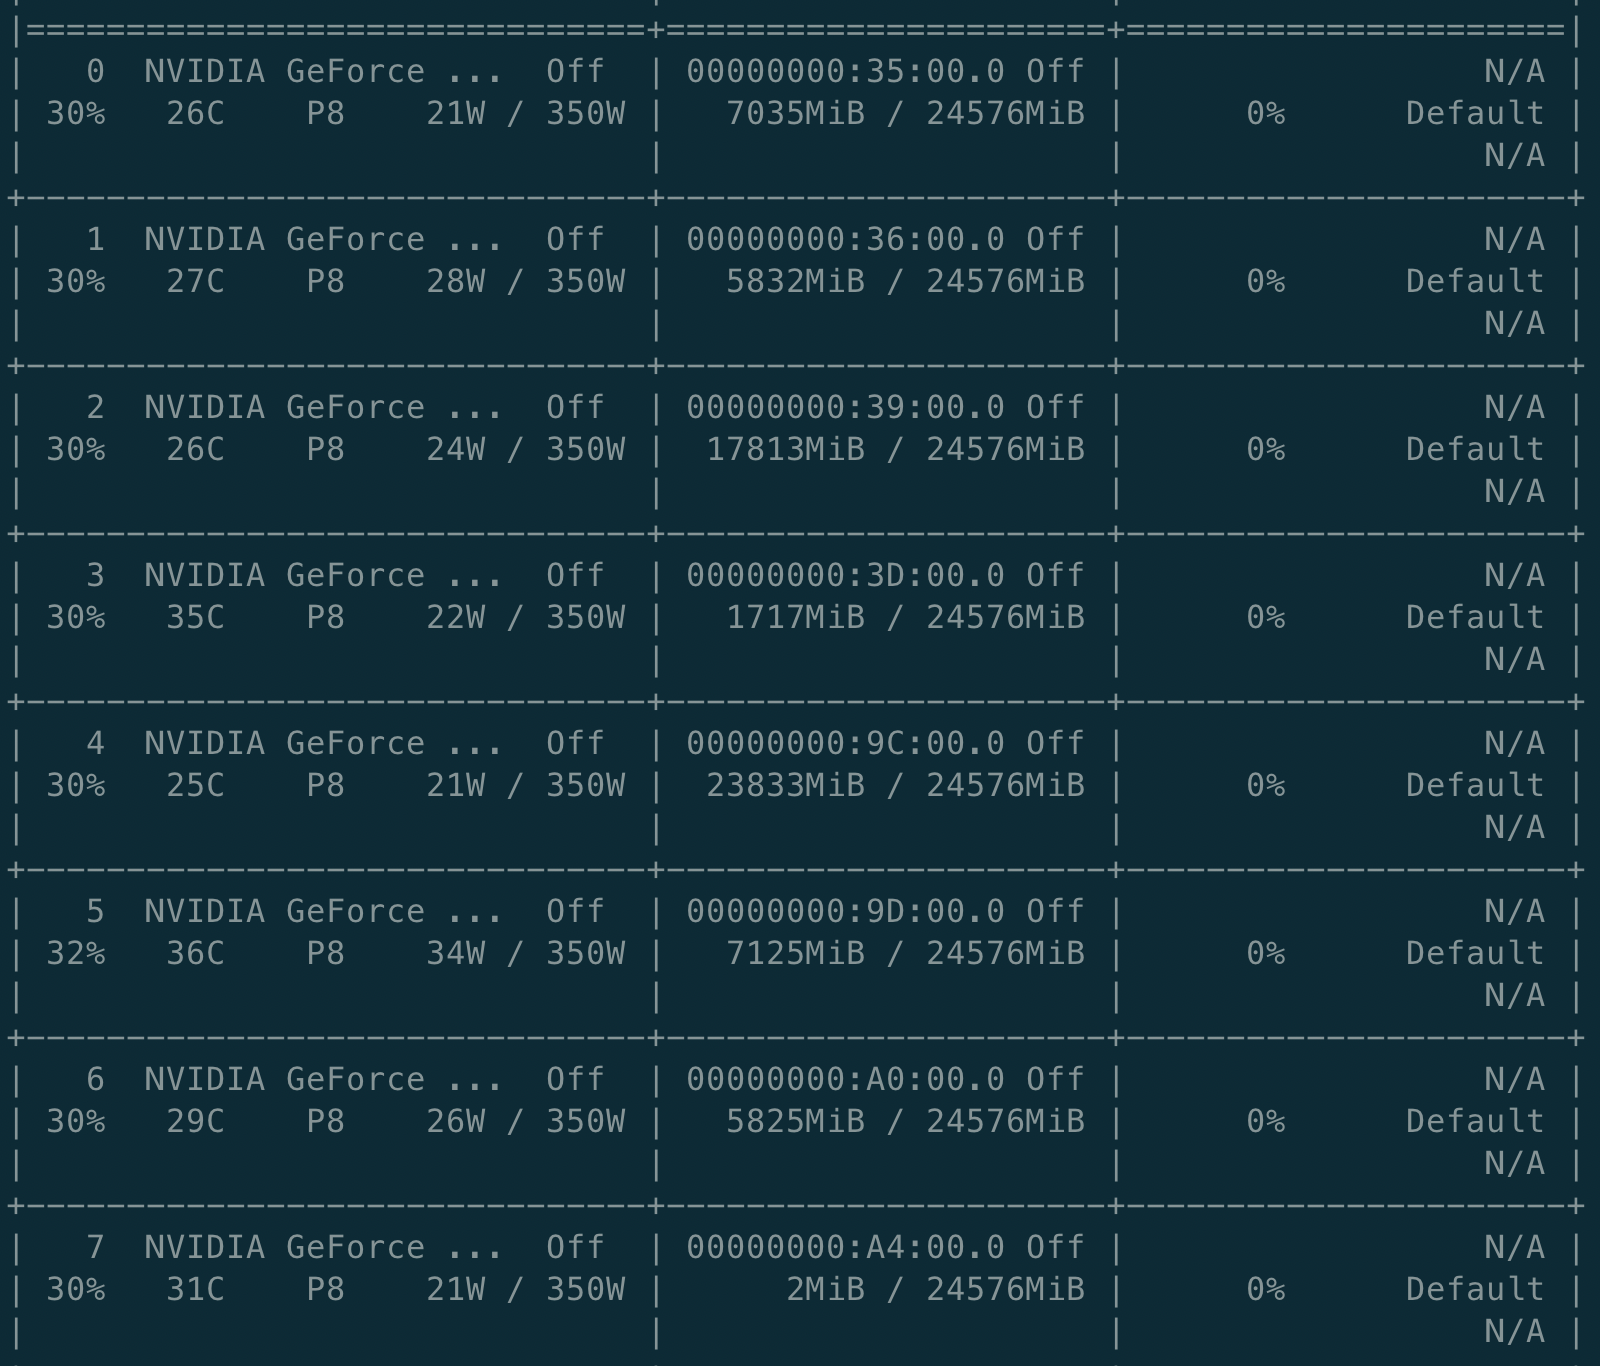
CUDA_VISIBLE_DEVICES=3,5 deepspeed inference-test.py --name facebook/opt-1.3b --test_performance
CUDA_VISIBLE_DEVICES=3,5,6,7 deepspeed inference-test.py --name facebook/opt-1.3b --test_performance (oom)
nvidia-smi before script running:
Error log
Traceback (most recent call last):
  File "inference-test.py", line 113, in <module>
    outputs = pipe(inputs,
  File "/home/xuyangyang/dsexamples/inference/huggingface/text-generation/utils.py", line 66, in __call__
    outputs = self.generate_outputs(input_list, num_tokens=num_tokens, do_sample=do_sample)
  File "/home/xuyangyang/dsexamples/inference/huggingface/text-generation/utils.py", line 109, in generate_outputs
    self.model.cuda().to(self.device)
  File "/home/xuyangyang/miniconda3/envs/python38/lib/python3.8/site-packages/torch/nn/modules/module.py", line 905, in cuda
    return self._apply(lambda t: t.cuda(device))
  File "/home/xuyangyang/miniconda3/envs/python38/lib/python3.8/site-packages/torch/nn/modules/module.py", line 797, in _apply
    module._apply(fn)
  File "/home/xuyangyang/miniconda3/envs/python38/lib/python3.8/site-packages/torch/nn/modules/module.py", line 797, in _apply
    module._apply(fn)
  File "/home/xuyangyang/miniconda3/envs/python38/lib/python3.8/site-packages/torch/nn/modules/module.py", line 797, in _apply
    module._apply(fn)
  [Previous line repeated 3 more times]
  File "/home/xuyangyang/miniconda3/envs/python38/lib/python3.8/site-packages/torch/nn/modules/module.py", line 820, in _apply
    param_applied = fn(param)
  File "/home/xuyangyang/miniconda3/envs/python38/lib/python3.8/site-packages/torch/nn/modules/module.py", line 905, in <lambda>
    return self._apply(lambda t: t.cuda(device))
torch.cuda.OutOfMemoryError: CUDA out of memory. Tried to allocate 16.00 MiB (GPU 0; 23.70 GiB total capacity; 4.35 GiB already allocated; 14.56 MiB free; 4.36 GiB reserved in total by PyTorch) If reserved memory is >> allocated memory try setting max_split_size_mb to avoid fragmentation.  See documentation for Memory Management and PYTORCH_CUDA_ALLOC_CONF
Traceback (most recent call last):
  File "inference-test.py", line 113, in <module>
    outputs = pipe(inputs,
  File "/home/xuyangyang/dsexamples/inference/huggingface/text-generation/utils.py", line 66, in __call__
    outputs = self.generate_outputs(input_list, num_tokens=num_tokens, do_sample=do_sample)
  File "/home/xuyangyang/dsexamples/inference/huggingface/text-generation/utils.py", line 111, in generate_outputs
    outputs = self.model.generate(**input_tokens, **generate_kwargs)
  File "/home/xuyangyang/miniconda3/envs/python38/lib/python3.8/site-packages/torch/utils/_contextlib.py", line 115, in decorate_context
    return func(*args, **kwargs)
  File "/home/xuyangyang/miniconda3/envs/python38/lib/python3.8/site-packages/transformers/generation_utils.py", line 1326, in generate
    return self.sample(
  File "/home/xuyangyang/miniconda3/envs/python38/lib/python3.8/site-packages/transformers/generation_utils.py", line 1942, in sample
    outputs = self(
  File "/home/xuyangyang/miniconda3/envs/python38/lib/python3.8/site-packages/torch/nn/modules/module.py", line 1501, in _call_impl
    return forward_call(*args, **kwargs)
  File "/home/xuyangyang/miniconda3/envs/python38/lib/python3.8/site-packages/transformers/models/opt/modeling_opt.py", line 923, in forward
    outputs = self.model.decoder(
  File "/home/xuyangyang/miniconda3/envs/python38/lib/python3.8/site-packages/torch/nn/modules/module.py", line 1501, in _call_impl
    return forward_call(*args, **kwargs)
  File "/home/xuyangyang/miniconda3/envs/python38/lib/python3.8/site-packages/transformers/models/opt/modeling_opt.py", line 687, in forward
    layer_outputs = decoder_layer(
  File "/home/xuyangyang/miniconda3/envs/python38/lib/python3.8/site-packages/torch/nn/modules/module.py", line 1501, in _call_impl
    return forward_call(*args, **kwargs)
  File "/home/xuyangyang/miniconda3/envs/python38/lib/python3.8/site-packages/transformers/models/opt/modeling_opt.py", line 318, in forward
    hidden_states, self_attn_weights, present_key_value = self.self_attn(
  File "/home/xuyangyang/miniconda3/envs/python38/lib/python3.8/site-packages/torch/nn/modules/module.py", line 1501, in _call_impl
    return forward_call(*args, **kwargs)
  File "/home/xuyangyang/miniconda3/envs/python38/lib/python3.8/site-packages/transformers/models/opt/modeling_opt.py", line 260, in forward
    attn_output = self.out_proj(attn_output)
  File "/home/xuyangyang/miniconda3/envs/python38/lib/python3.8/site-packages/torch/nn/modules/module.py", line 1501, in _call_impl
    return forward_call(*args, **kwargs)
  File "/home/xuyangyang/miniconda3/envs/python38/lib/python3.8/site-packages/torch/nn/modules/linear.py", line 114, in forward
    return F.linear(input, self.weight, self.bias)
torch.cuda.OutOfMemoryError: CUDA out of memory. Tried to allocate 2.00 MiB (GPU 0; 23.70 GiB total capacity; 4.93 GiB already allocated; 6.56 MiB free; 4.95 GiB reserved in total by PyTorch) If reserved memory is >> allocated memory try setting max_split_size_mb to avoid fragmentation.  See documentation for Memory Management and PYTORCH_CUDA_ALLOC_CONF
[2023-04-10 23:43:22,847] [INFO] [launch.py:318:sigkill_handler] Killing subprocess 26687
[2023-04-10 23:43:22,886] [INFO] [launch.py:318:sigkill_handler] Killing subprocess 26688
[2023-04-10 23:43:23,528] [INFO] [launch.py:318:sigkill_handler] Killing subprocess 26689
[2023-04-10 23:43:23,528] [INFO] [launch.py:318:sigkill_handler] Killing subprocess 26690
[2023-04-10 23:43:24,139] [ERROR] [launch.py:324:sigkill_handler] ['/home/xuyangyang/miniconda3/envs/python38/bin/python', '-u', 'inference-test.py', '--local_rank=3', '--name', 'facebook/opt-1.3b', '--test_performance'] exits with return code = 1
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
Start in DeepSpeedExamples/inference/huggingface/text-generation/inference-test.py and utils.py, especially generate_outputs where the traceback shows model placement and generation. Reproduce the OPT-1.3B commands with two and four GPUs, then trace why the four-GPU run exhausts GPU 0 memory; done means the four-GPU inference run completes without CUDA out-of-memory errors.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- python, pytorch
- Domain
- distributed-systems, machine-learning
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 25/100