deepinsight / deepinsight/insightface
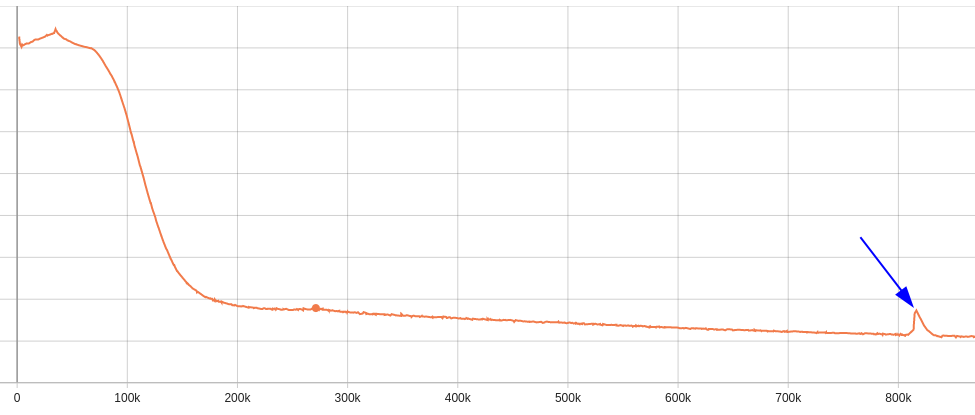
Resume learning after stopping. Loss growth.
- Dominant language
- Python
- Stars
- 29.7k
- Forks
- 6.1k
- PR merge metrics
- No merged PRs in 30d
Description
Hi all. I use the transformer model `vit_l_dp005_mask_005` on a dataset of 5 million identities.
Use `arcface_torch` version. 1 machine - 8 х V100 (32Gb)
Training params:
```
Training: 2022-10-27 06:32:28,027-: margin_list [1.0, 0.0, 0.4]
Training: 2022-10-27 06:32:28,027-: network vit_l_dp005_mask_005
Training: 2022-10-27 06:32:28,028-: resume True
Training: 2022-10-27 06:32:28,028-: output ./work_dirs/VIT/weights
Training: 2022-10-27 06:32:28,028-: embedding_size 256
Training: 2022-10-27 06:32:28,028-: sample_rate 0.3
Training: 2022-10-27 06:32:28,028-: interclass_filtering_threshold0
Training: 2022-10-27 06:32:28,028-: fp16 True
Training: 2022-10-27 06:32:28,028-: batch_size 256
Training: 2022-10-27 06:32:28,028-: optimizer adamw
Training: 2022-10-27 06:32:28,028-: lr 0.001
Training: 2022-10-27 06:32:28,028-: momentum 0.9
Training: 2022-10-27 06:32:28,028-: weight_decay 0.1
Training: 2022-10-27 06:32:28,028-: verbose 2000
Training: 2022-10-27 06:32:28,028-: frequent 10
Training: 2022-10-27 06:32:28,028-: dali False
Training: 2022-10-27 06:32:28,028-: gradient_acc 1
Training: 2022-10-27 06:32:28,028-: seed 2048
Training: 2022-10-27 06:32:28,028-: num_workers 0
Training: 2022-10-27 06:32:28,028-: epoch_resume 29
Training: 2022-10-27 06:32:28,028-: rec /media/Data2/ramdisk/
Training: 2022-10-27 06:32:28,028-: rec_val /media/Data2/valid
Training: 2022-10-27 06:32:28,028-: num_classes 5000000
Training: 2022-10-27 06:32:28,028-: num_image 79341362
Training: 2022-10-27 06:32:28,028-: num_epoch 70
Training: 2022-10-27 06:32:28,028-: warmup_epoch 10
Training: 2022-10-27 06:32:28,028-: val_targets ['lfw', 'agedb_30', 'cfp_ff', 'cfp_fp', 'cplfw', 'vgg2_fp']
Training: 2022-10-27 06:32:28,029-: total_batch_size 2048
Training: 2022-10-27 06:32:28,029-: warmup_step 387400
Training: 2022-10-27 06:32:28,029-: total_step 2711800
```
After stopping training and resuming, there is an increase in loss, as if this is new data for the model. Moreover, the loss first starts to grow, and then stabilizes.
Mixing in the dataloader is enabled and working.
Has anyone encountered such problems? In which direction can you look?
Loss Plot:
Contributor guide
No contributing guide indexed for this repository
Assessment
This issue has not been assessed yet.