Localcluster memory leak
- Dominant language
- Python
- Stars
- 1.7k
- Forks
- 778
- Avg merge
- 2h 50m
- Merged PRs (30d)
- 3
Description
**What happened**:
Start a localcluster alone and no request for it. But worker's memory increase continually.
**What you expected to happen**:
The memory should be stable.
**Anything else we need to know?**:
we have same issue when in version, dask==2.19.0, dask==2021.10.0 and dask==2021.12.0
**Environment**:
- Dask version:
2021.12.0
- Python version:
Python 3.10.1
- Operating System:
centos:latest
- Install method (conda, pip, source):
1. create env by dockerfile.
```python
FROM centos:latest
# Install miniconda
RUN yum update -y && \
yum install -y wget bzip2 passwd openssl cronie openssh-server ca-certificates curl git ; \
yum clean all && \
wget --quiet https://repo.anaconda.com/miniconda/Miniconda3-latest-Linux-x86_64.sh -O ~/miniconda.sh && \
/bin/bash ~/miniconda.sh -b -f -p /opt/conda && \
rm ~/miniconda.sh && \
ln -s /opt/conda/etc/profile.d/conda.sh /etc/profile.d/conda.sh
RUN yum -y install epel-release
# Environments
ENV PATH=/opt/conda/envs/tsflow/bin:/opt/conda/bin:$PATH
ENV LANG=en_US.utf8
ENV LC_ALL=en_US.utf8
# Install most common packages
RUN /opt/conda/bin/conda config --add channels conda-forge \
&& /opt/conda/bin/conda config --set show_channel_urls yes \
&& /opt/conda/bin/conda create --name tsflow python=3.6 \
&& echo "source activate tsflow" > ~/.bashrc
RUN ssh-keygen -q -t rsa -b 2048 -f /etc/ssh/ssh_host_rsa_key -N '' && \
ssh-keygen -q -t ecdsa -f /etc/ssh/ssh_host_ecdsa_key -N '' && \
ssh-keygen -t dsa -f /etc/ssh/ssh_host_ed25519_key -N ''
ENTRYPOINT /usr/sbin/sshd && /usr/sbin/crond && sleep 99999999d
```
2. enter docker
```python
docker run -it -d --name daskclean -p 8687:8687 --net=host jdostest:4.1-conda-simple-v1 /bin/bash
docker exec -it daskclean /bin/bash
--
3. create dask test env
```python
conda create -n tsflow2testclean dask
# then enter python env
python
>>> from distributed import Client, LocalCluster
>>> dashboard_address = "0.0.0.0:8687"
>>> memory_limit = "400m"
>>> cluster = LocalCluster(n_workers=1, dashboard_address=dashboard_address, memory_limit=memory_limit)
--
4. use dashboard to watch the memory
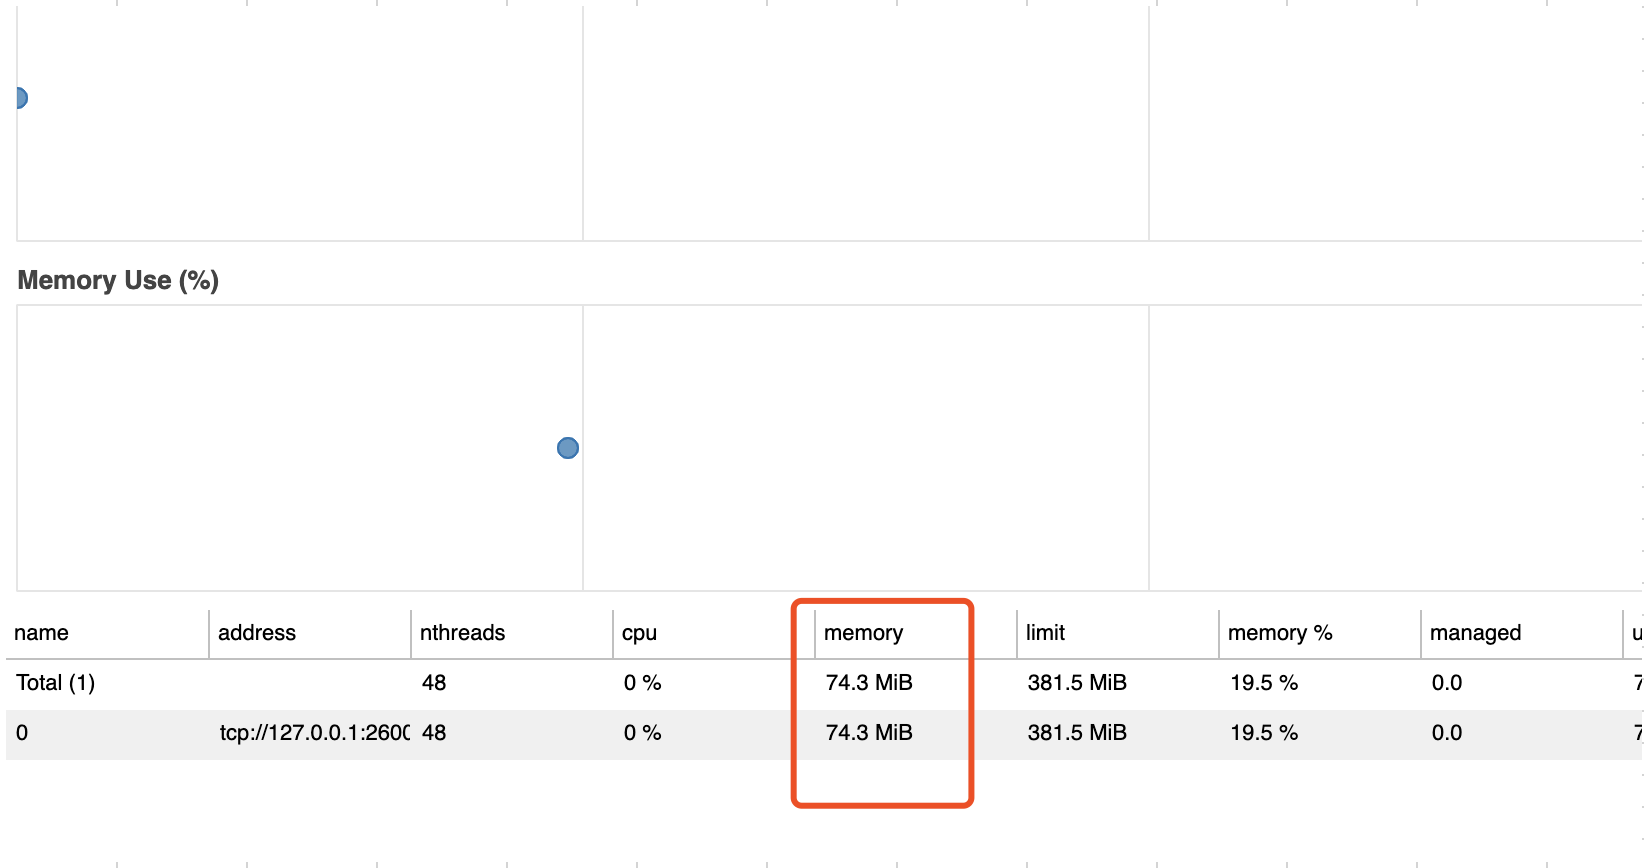
worker mem about 74m
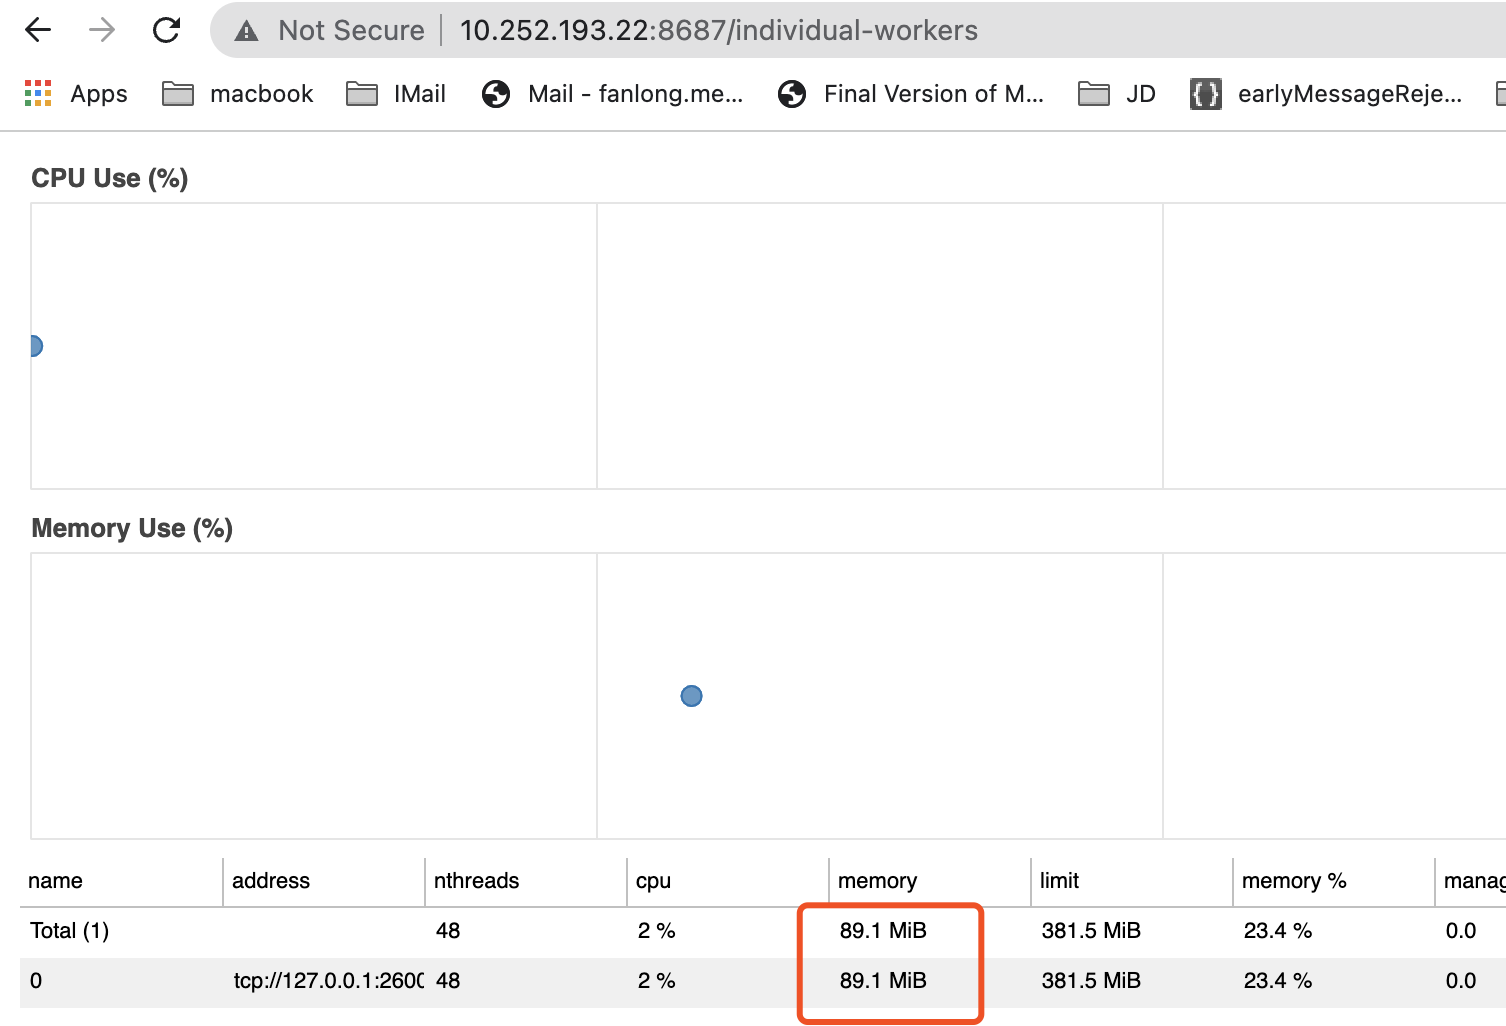
after a while, worker mem about 90m
**client.dump_cluster_state()
[mfldump.msgpack.gz](https://github.com/dask/distributed/files/7790762/mfldump.msgpack.gz)
bound method Client.dump_cluster_state of
Contributor guide
Assessment
This issue has not been assessed yet.