KilledWorker exception with dask dataframes
- Dominant language
- Python
- Stars
- 1.7k
- Forks
- 778
- Avg merge
- 2h 50m
- Merged PRs (30d)
- 3
Description
**What happened**:
KilledWorker exception for a rather small computation using dask dataframes.
We schedule a dask computation based on simulated data as part of our integration tests. In our test code, we create 1k partitions filled with random data which have a fixed size of 7k rows and 50 columns (see example below). The worker seems to go out of memory, the task is unsuccessfully retried on a different worker a couple of times until a `KilledWorker` exception is raised.
**What you expected to happen**:
The computation succeeds, especially because the partition size seems to be small enough and the workers have enough memory (more information to that below).
**Minimal Complete Verifiable Example**:
```python
import pandas as pd
import numpy as np
import dask.bag as db
import dask.dataframe as dd
from dask.delayed import delayed
from dask.distributed import Client
group_by_columns_count = 20
value_columns_count = 30
partition_count = 1000
rows_per_partition = 70000
group_by_columns = [f"G{i}" for i in range(group_by_columns_count)]
value_columns = [f"V{i}" for i in range(value_columns_count)]
def create_partition(partition_id: int) -> pd.DataFrame:
np.random.seed(partition_id)
return pd.DataFrame(
{
"PARTITION_ID": partition_id,
**{
group_col: np.random.randint(0, 10, size=rows_per_partition)
for group_col in group_by_columns
},
**{
value_col: np.random.random(rows_per_partition)
for value_col in value_columns
},
}
)
dask_endpoint = "my-dask-endpoint"
# This computation consumes a lot of memory during dataframe-groupby-* steps
with Client(dask_endpoint, timeout=30) as c:
dfs = [delayed(create_partition)(partition_id) for partition_id in range(partition_count)]
ddf = dd.from_delayed(dfs)
ddf = ddf.groupby(by=group_by_columns)
ddf = ddf.mean()
ddf.compute()
# Equivalent computation using bags runs fine
with Client(dask_endpoint, timeout=30) as c:
bag = db.from_sequence(range(partition_count), partition_size=1).map(create_partition)
bag = bag.groupby(grouper=lambda df: df.groupby(group_by_columns))
bag = bag.map(func=lambda groupby_result: groupby_result[0].mean())
bag.compute()
```
**Anything else we need to know?**:
* Scheduling the computation based on dataframes leads to worker OOM and ultimately fails with the `KilledWorker` exception
* The size of a single partition/dataframe is about 30 MB:
```python
df = create_partition(42)
print(f"{df.memory_usage().sum()/ 1024**2} MB")
# 27.237060546875 MB
```
* We assume that the upper limit of the resulting dask dataframe could be very roughly estimated to max 30 GB
```python
df = create_partition(42)
print(f"{df.memory_usage().sum() * partition_count / 1024**3} GB")
# 26.598691940307617 GB
```
* Worker size is 32 GB, this should be sufficient memory for the given partition size as well as the resulting ddf (?)
* The euqivalent computation using dask bags is working fine and also needs way less memory
* We also very frequently see messages like this:
`distributed.utils_comm - INFO - Retrying get_data_from_worker after exception in attempt 3/5: Timed out during handshake while connecting to tcp://172.20.10.118:9000 after 60 s`
Things we have tried to debug/mitigate the issue:
* enabling/disabling spill to disk
* using jemallac
* actibating the garbage collection and disabling the throttling
* removing our service mesh (istio)
* different (azure) kubernetes versions (1.19 and 1.20)
--> result doesn't change, still worker OOMs and finally a KilledWorker exception.
**Environment**:
10 Dask workers with 32 GB each, deployed on a kubernetes cluster with istio as service mesh
* Dask version: 2021.11.2
* Python version: 3.9.7
* Operating System: ~debian9~ debian10
* Base image: python:3.9.7-slim-buster
* Install method (conda, pip, source): pip
Cluster Dump State:
Computation fails, can't seem to retrieve this after that?
Traceback:
```python
---------------------------------------------------------------------------
KilledWorker Traceback (most recent call last)
/tmp/ipykernel_29/1086427464.py in
38 ddf = ddf.groupby(by=group_by_columns)
39 ddf = ddf.mean()
---> 40 ddf.compute()
41
42 # Equivalent computation using bags
/usr/local/lib/python3.9/site-packages/dask/base.py in compute(self, **kwargs)
286 dask.base.compute
287 """
--> 288 (result,) = compute(self, traverse=False, **kwargs)
289 return result
290
/usr/local/lib/python3.9/site-packages/dask/base.py in compute(traverse, optimize_graph, scheduler, get, *args, **kwargs)
569 postcomputes.append(x.__dask_postcompute__())
570
--> 571 results = schedule(dsk, keys, **kwargs)
572 return repack([f(r, *a) for r, (f, a) in zip(results, postcomputes)])
573
/usr/local/lib/python3.9/site-packages/distributed/client.py in get(self, dsk, keys, workers, allow_other_workers, resources, sync, asynchronous, direct, retries, priority, fifo_timeout, actors, **kwargs)
2723 should_rejoin = False
2724 try:
-> 2725 results = self.gather(packed, asynchronous=asynchronous, direct=direct)
2726 finally:
2727 for f in futures.values():
/usr/local/lib/python3.9/site-packages/distributed/client.py in gather(self, futures, errors, direct, asynchronous)
1978 else:
1979 local_worker = None
-> 1980 return self.sync(
1981 self._gather,
1982 futures,
/usr/local/lib/python3.9/site-packages/distributed/client.py in sync(self, func, asynchronous, callback_timeout, *args, **kwargs)
866 return future
867 else:
--> 868 return sync(
869 self.loop, func, *args, callback_timeout=callback_timeout, **kwargs
870 )
/usr/local/lib/python3.9/site-packages/distributed/utils.py in sync(loop, func, callback_timeout, *args, **kwargs)
330 if error[0]:
331 typ, exc, tb = error[0]
--> 332 raise exc.with_traceback(tb)
333 else:
334 return result[0]
/usr/local/lib/python3.9/site-packages/distributed/utils.py in f()
313 if callback_timeout is not None:
314 future = asyncio.wait_for(future, callback_timeout)
--> 315 result[0] = yield future
316 except Exception:
317 error[0] = sys.exc_info()
/usr/local/lib/python3.9/site-packages/tornado/gen.py in run(self)
760
761 try:
--> 762 value = future.result()
763 except Exception:
764 exc_info = sys.exc_info()
/usr/local/lib/python3.9/site-packages/distributed/client.py in _gather(self, futures, errors, direct, local_worker)
1843 exc = CancelledError(key)
1844 else:
-> 1845 raise exception.with_traceback(traceback)
1846 raise exc
1847 if errors == "skip":
KilledWorker: ("('dataframe-groupby-sum-combine-615fc68191b82bd112a35cf039ec8c0c', 3, 1, 0)", )
```
Logs:
```log
09:46:14.518 Lost connection to 'tcp://127.0.0.1:41066' while reading message: in : Stream is closed. Last operation: get_data
09:46:15.791 Send compute response to scheduler: ('dataframe-groupby-sum-combine-4e4be275569a8a6b774ff817cb0bcf39'
8x
09:46:15.795 Release key {'key': "('dataframe-groupby-sum-combine-4e4be275569a8a6b774ff817cb0bcf39'
09:46:15.805 Ensure communicating. Pending: 1. Connections: 0/50
09:46:15.805 Data task already known {'task': from tcp://172.20.9.194:9000
-
10+ Heartbeats
-
09:46:44.466 Calling gc.collect(). 56.048s elapsed since previous call.
09:46:44.898 Worker is at 80% memory usage. Pausing worker. Process memory: 11.54 GiB – Worker memory limit: 14.31 GiB
09:46:44.900 Calling gc.collect(). 0.224s elapsed since previous call.
-
10+ Heartbeats and gc.collect()
09:46:51.218 Lost connection to 'tcp://127.0.0.1:50678' while reading message: in : Stream is closed. Last operation: get_data
09:46:54.499 Worker process 21 was killed by signal 9
09:46:54.499 [] process 21 exited with code -9
restart of worker ...
```
Screenshots of dask dashboard:
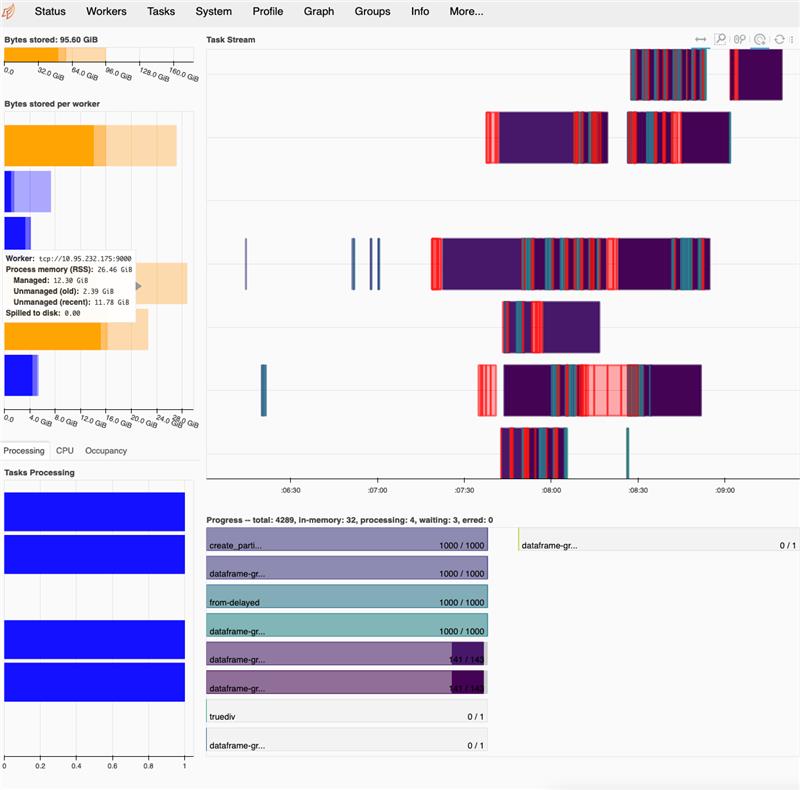
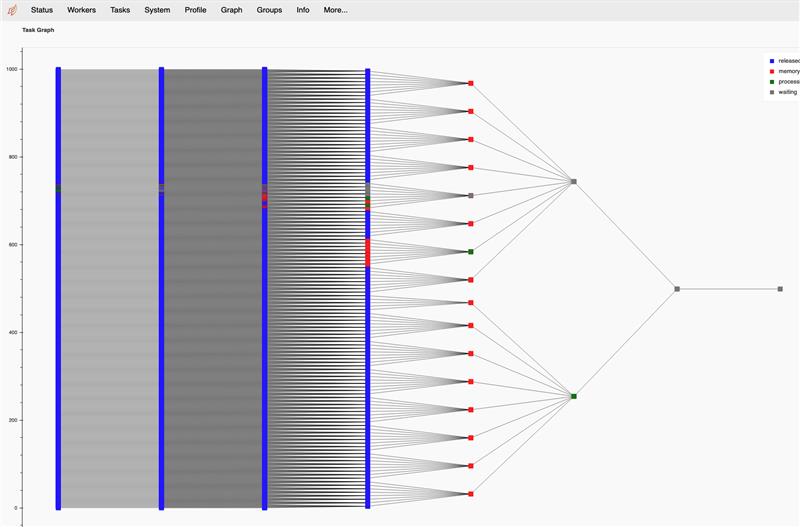
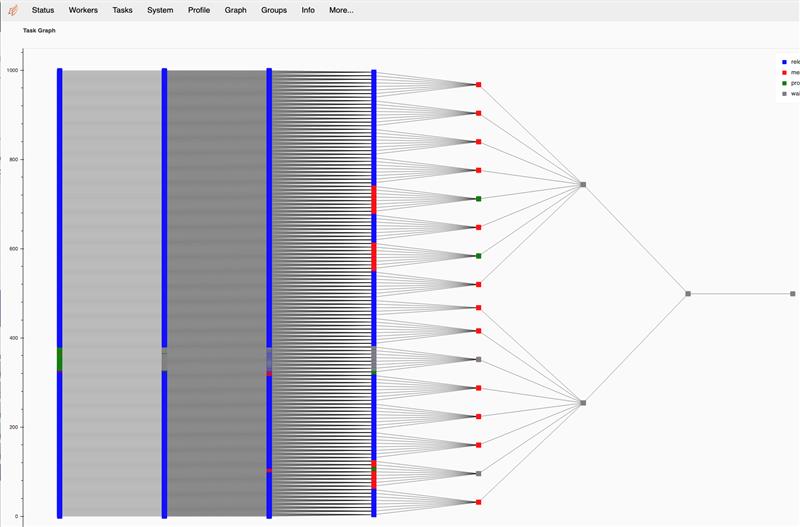
Contributor guide
Assessment
This issue has not been assessed yet.